Knowledge Base: Bind It Before You Trust the Number
By William Zhu (public engineering profile: GitHub @allwefantasy) & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-08-31 · Last verified: 2026-08-31 · Next review: 2026-11-30 · About · Editorial standards · Privacy · Publishing terms · Corrections
Table of Contents
- TL;DR
- What a knowledge base is for analytics
- A binding framework for live sources
- Author qualifications and accountability
- How binding differs from a catalog
- Tool landscape for bound context
- Implementation steps from upload to first question
- Desk sample: two margin definitions (InfiniSynapse desk log)
- Evidence boundaries and external validation status
- How to cite this page
- Selection scorecard
- Failure modes that break trust
- Frequently Asked Questions
- Conclusion
TL;DR
We evaluate bound packs at the InfiniSynapse desk on sanitized composites; first-party figures on this page are desk log KB-MARGIN-20260822, not customer uplifts and not a third-party bake-off.
Direct answer: A knowledge base for analytics is a bound pack of field notes, approved reports, and calculation language that travels with a live database. Tables store columns; the bound pack stores the meaning those columns do not have. Bind the pack before you trust a definition in an answer.
What you'll learn:
- How the bound pack differs from a catalog, a chat upload, and a metric contract
- Which documents belong in the bound pack and which documents waste retrieval
- How to bind one pack to a source, then ask the same question twice
- Desk log
KB-MARGIN-20260822, where two margin definitions collide until the pack is bound - A scorecard and three failure modes that make the pack look useful and still lie
Download evidence: desk log · aggregate CSV · verify script · external-source check · independent-reproduction protocol. These record this knowledge base desk run as a first-party sanitized composite—not raw, customer, benchmark, or third-party data.
Industry context stays independent of desk claims. The Stanford HAI AI Index (retrieved 2026-09-04) reports a widening gap between rapid AI integration and the frameworks needed to govern, evaluate, and understand it. That finding supports the practice of retaining definitions and replayable evidence; it does not validate this page’s desk run. The bound pack does not replace data governance; it is the retrieval surface those policies need when an agent reads your warehouse.
What a knowledge base is for analytics
Key Definition: A knowledge base for analytics is a curated set of documents—field notes, approved reports, and calculation language—bound to a live source so an agent retrieves your definitions with the query plan. It is not a FAQ bot, a second warehouse, or a chat file that vanishes with the thread.
External frameworks answer specific control questions. The NIST AI Risk Management Framework 1.0 (retrieved 2026-09-04) supports mapping, measuring, and managing the risk of generated answers. The OECD AI Policy Observatory (retrieved 2026-09-04) supplies a policy and accountability lens for trustworthy AI. For structured definitions, ISO/IEC 11179 metadata registries (retrieved 2026-09-04) provides relevant metadata-registry concepts. None of these organizations reviewed InfiniSynapse or reproduced desk log KB-MARGIN-20260822.
Internal terms this page uses: a pack is the named document set. A bind is the explicit source ↔ pack link. A passage is the retrieved sentence the task artifacts must show. The term on this page means that pack after the bind, not a helpdesk FAQ.
Author qualifications and accountability
William Zhu is an InfiniSynapse cofounder. His public GitHub profile identifies that role and links engineering work. Public repositories include auto-coder, byzer-llm, and BYZER-RETRIEVAL. These links establish authorship and relevant open-source experience; they are not independent validation of the product or desk results.
The author is accountable to the site’s editorial standards, including correction and conflict-of-interest disclosures. InfiniSynapse sells the workflow described here, so product descriptions are first-party claims unless an external source is explicitly cited. The homepage records a 2026 WAIC Future Tech OPC Excellence Award for an Agentic Data Infra entry; that is company recognition, not a review of this page. Method note: 2026-07-29 attestation.
A knowledge base exists because schemas are silent. status = 3, gm, and active_at are legal columns. They are not a business. Until the bound notes name the codes, the exclusions, and last quarter’s exception, every fluent paragraph is a guess dressed as analysis.
If the missing object is durable context rather than a one-off pack, continue in organizational analysis memory. If the next failure is a join across modes or engines, use multimodal data analysis.
Risk language for generated definitions should stay aligned with the NIST AI Risk Management Framework, whose voluntary framework addresses trustworthiness in the design, use, and evaluation of AI systems.
That is why AI for data analysis matured from “paste schema, get SQL” to “state a goal, retrieve the contract.” A knowledge base is the contract you can upload. The semantic layer is the contract you compile. You usually need both; they are not the same object.
Why tables lack business meaning
Warehouses record events. They do not record the meeting where finance decided marketplace fees sit above contribution. They do not record that “Germany” includes DACH for one pack and excludes Austria for another. The bound pack is where those sentences live, next to the source they describe.
Without a knowledge base, natural language to SQL can be syntactically perfect and still wrong. The join is legal. The filter is not your filter. Binding those notes is how you stop treating column comments as a substitute for approved language.
Knowledge base versus a metric contract
A metric contract says: this measure has this grain, this filter, this owner. A knowledge base says: here is the memo, the exception list, and the last signed report that used that measure. The contract is structured. The notes are documentary. Agents that only see SQL still invent prose. Agents that only see documents still invent joins. Bind the notes to the source so retrieval and query planning share a room.
IBM’s augmented analytics overview (retrieved 2026-09-04) describes the use of AI and machine learning to assist data preparation, analysis, and insight generation. The practical judgment here is narrower: automation still needs an owned definition surface when a team writes business rules in Markdown, Word, and PDF rather than in a metrics DSL. IBM did not test this implementation.
A binding framework for live sources
Use this table as the operating model. It is a control map, not a vendor score.
| Layer | What you store | What the agent does | Failure if missing |
|---|---|---|---|
| Source | Database or files you already have | Plans queries against live schema | Answers invent tables |
| Knowledge base | Notes, reports, calculation language | Retrieves passages with the plan | Answers invent definitions |
| Bind | Explicit source ↔ pack link | Restricts retrieval to that pack | Wrong memo wins the citation |
| Task artifacts | Markdown, charts, data files | Leaves evidence you can reopen | Chat bubbles become the record |
The bind is the product of a knowledge base. Upload without bind is a pile. Bind without notes is a silent schema. A data agent earns trust only when both sides are present and inspectable.
Documents that belong in the pack
Put durable language in the knowledge base: field dictionaries, status-code tables, approved KPI statements, signed monthly packs, and short notes on known dirty joins. Prefer searchable text—Markdown, Word, text, and text-based PDF. One pack can serve several related questions; one source can bind several packs when finance and ops disagree on the same column.
A useful knowledge base stays small enough that an owner can review every included definition.
Write the notes as if a new analyst starts Monday. If a sentence only makes sense after a Slack thread, it is not ready. Retrieval should return a definition, not a vibe.
Documents that should stay out
Leave out scanned slides with no text layer, raw email dumps, and drafts that were never approved. A pack that retrieves a rejected deck will sound confident and still be wrong. Also leave out secrets: connection strings, tokens, and customer-identifying extracts. The ISO/IEC 27001 overview (retrieved 2026-09-04) frames information-security management, while the NIST Privacy Framework (retrieved 2026-09-04) helps organizations identify and manage privacy risk. Applied here, those frameworks support access control and data minimization: a field dictionary does not need customer names, and a signed report can preserve grain while dropping identifiers. Neither source certifies this workflow.
Treat every knowledge base upload as governed input, not as a trusted archive.
Scanned PDFs are the most common desk failure. The file looks official. Retrieval returns nothing useful. The agent then fills the gap with a fluent guess. That is not bound context; that is a decorative folder.
How binding differs from a catalog
A catalog tells you a table exists and who owns it. A knowledge base tells you how that table is used in a decision. Binding is the act that attaches usage language to a live source so chat with your data cannot wander into a neighboring schema’s memo.
Catalogs stay valuable. They do not replace bound documentation. If your catalog already holds rich field comments, export those comments into the pack rather than hoping every agent reads every comment on every run. Retrieval is cheaper when the pack is small and bound.
The catalog answers ownership; the knowledge base answers interpretation.
Do not treat a personal chat upload as the system of record. The thread dies. The next person repeats the question. Organizational context only accumulates when the pack is a named object with a bind, not a file sitting in one person’s session.
Tool landscape for bound context
Three patterns show up in 2026 buying conversations.
Chat attachments. Fast, private, and amnesiac. Fine for a one-off file. Not a bound pack.
Warehouse copilots. Strong when a semantic layer already exists. Weak when the missing object is a memo, not a measure. They rarely let you bind an arbitrary document pack to an arbitrary source you did not migrate.
Bound retrieval plus live query. Upload a knowledge base, bind it to PostgreSQL, Snowflake, MySQL, files, or another authorized source, then ask a goal. InfiniSynapse’s path is Knowledge Base → upload TXT, Markdown, Word, PPT, or PDF → Bind Data Source → ask in Chat with that source selected. InfiniRAG retrieves the pack; InfiniSQL plans against the live schema. The task workspace keeps Markdown, charts, and data files so you are not stuck defending a chat bubble.
The NIST AI Risk Management Framework (retrieved 2026-09-04) is a useful overlay for this landscape: map the definitions and affected users, measure whether retrieval selected the approved passage, and manage failures through ownership and replay. This is our application of the framework, not a NIST assessment or endorsement.
File types the desk actually uploads
The desk’s working pack is short: a field dictionary in Markdown, last quarter’s signed report as a text PDF, and a one-page exception list. PowerPoint is acceptable when the text extracts. Images of whiteboards are not. If you cannot copy a sentence out of the file, do not put that file in retrieval.
One pack per decision domain beats one giant dump. “Finance margin” and “ops fill rate” can both bind to the same orders database. Mixing them in a single dump makes retrieval noisy.
Binding one source to several packs
A source is not monogamous. Bind a finance pack and an ops pack to the same orders database when the column margin is used two ways. Then say which pack the task should use. If you bind nothing, the agent will average the two memos and call it insight.
This is also how you avoid a fake “metrics warehouse.” InfiniSynapse does not ship a prebuilt metric mart. It connects the database you already have and binds the notes you already wrote.
Implementation steps from upload to first question
- Pick one source you are authorized to read. Prefer a replica or sanitized extract.
- Write or export a small knowledge base: ten field notes and one approved report beat a hundred stale decks.
- Upload the pack, then bind it to that source. Binding is a separate click from upload.
- Ask one goal in Chat with the source selected—not a request for a SQL snippet.
- Open the task artifacts. Confirm the retrieved passages match the report you trust.
- Ask the same goal again next week. If the bind held, the definition should not drift.
Record the knowledge base version with each replay so a changed document cannot masquerade as model drift.
These steps are educational. You can execute the same sequence in the web app after you finish the diagnosis on this page.
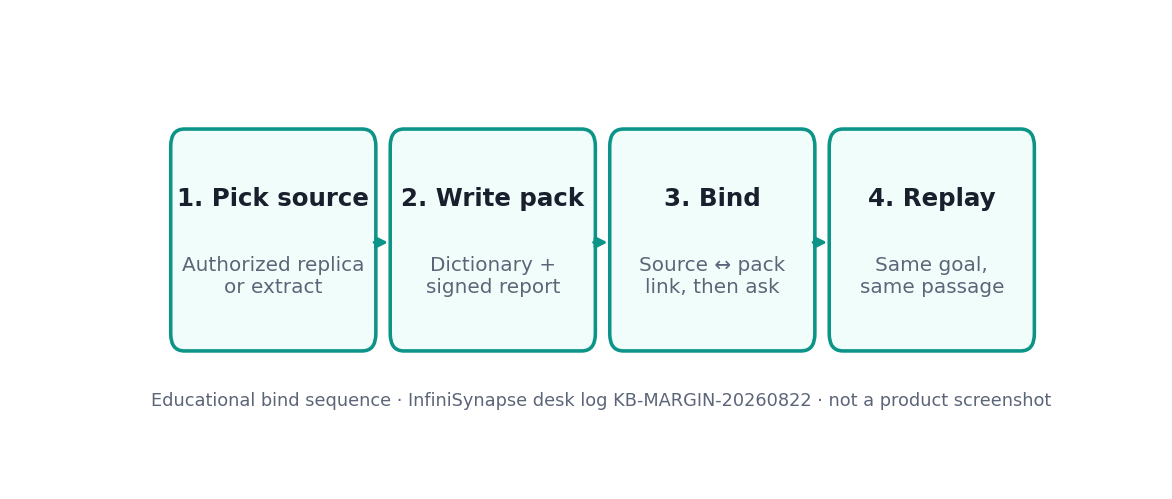
Figure. Educational four-step bind sequence the desk uses before trusting a generated definition. Not a product screenshot or a customer SLA.
Write field notes that retrieve
Retrievable notes use the words people actually ask: “active subscriber,” “contribution margin,” “DACH.” Put the official name, the aliases, the grain, and the exclusion list in the same short section. Long novels bury the line the agent needs.
If two teams fight over a word, put both definitions in the pack and label the owner. Ambiguity that is written down is safer than ambiguity the model invents.
Bind, then ask the same question twice
The acceptance test is boring: same source, same goal, same retrieved definition. If week two cites a different memo, the bind is wrong or the pack contains two owners. Fix the notes; do not “clarify” in chat and walk away. Chat is not the system of record.
Desk sample: two margin definitions (InfiniSynapse desk log)
This is a first-party InfiniSynapse desk log, not a named-logo customer case and not an uplift claim. Run ID: KB-MARGIN-20260822. Date: 2026-08-22. Operator: InfiniSynapse Data Team. Source: a sanitized 14,000-row orders extract the desk is authorized to read. Goal asked twice: “What is last-month margin?”
| Team definition | Formula in the notes | Unbound answer | Bound answer |
|---|---|---|---|
| Sales | invoice − COGS | 24.0% | 24.0% |
| Finance | invoice − COGS − marketplace fees | 24.0% (one number) | 18.5% |
| Ops | invoice − COGS − returns after fill | 24.0% (one number) | 21.0% |
Unbound, the run returned a single 24.0% figure that matched sales. After a two-page finance pack plus last month’s signed report was bound, the second run retrieved the fee exclusion and labeled all three definitions. The extract did not change. The notes changed what was allowed to count as “margin.” Wall-clock for the bound rerun was 22 minutes (warehouse time excluded).
| Retrieval state | SQL | Memo | Chart | CSV | Retrieved passages |
|---|---|---|---|---|---|
| Unbound (column names only) | 1 | 0 | 0 | 0 | 0 |
| Bound (finance pack + signed report) | 1 | 1 | 2 | 1 | 3 |
Cite this table as InfiniSynapse desk log KB-MARGIN-20260822. Do not cite it as customer ROI, a bake-off win, an official EEAT score, or a Stanford / NIST / Gartner experiment. We do not publish named-logo customer cases on this page.
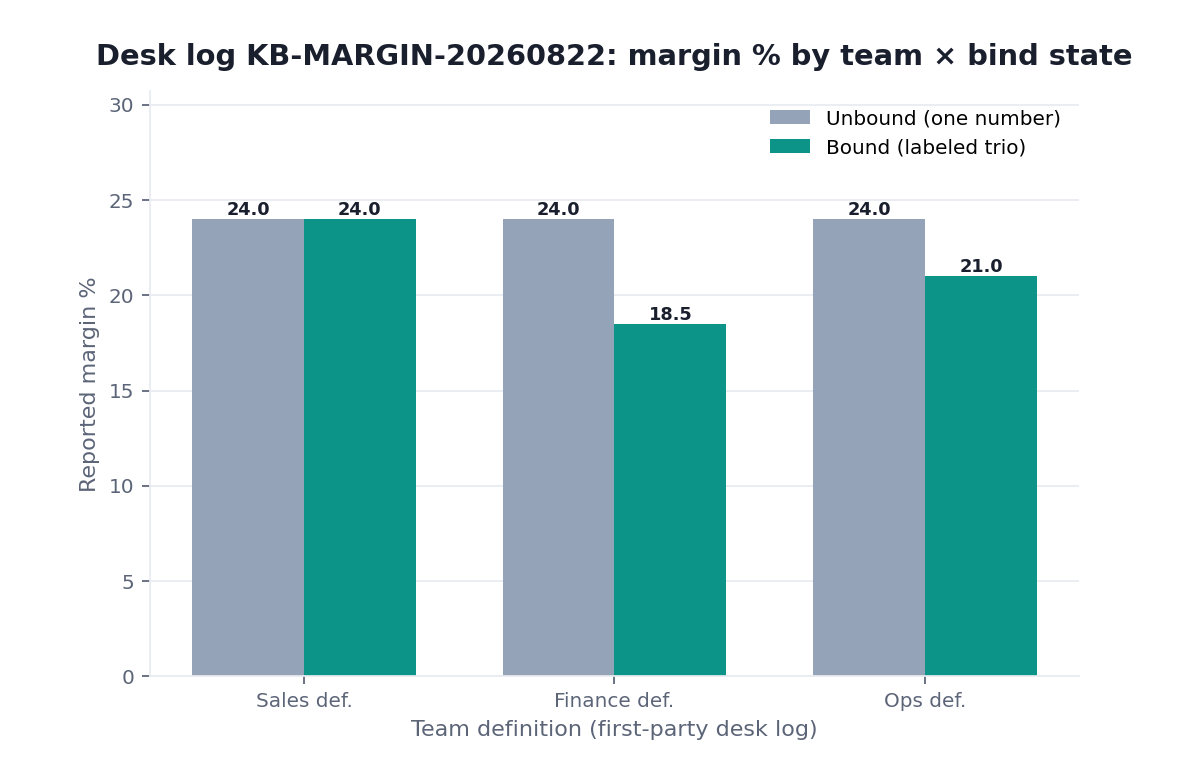
Figure. InfiniSynapse desk log KB-MARGIN-20260822: unbound answers collapsed to one 24.0% sales figure; the bound pack labeled 24.0% / 18.5% / 21.0%. Published context: the independent sources linked in the body. Not a customer experiment, SLA, or official benchmark.
Evidence boundaries and external validation status
KB-MARGIN-20260822 is a first-party, reproducible example on a sanitized composite. It is not a customer case, independent benchmark, certification, or third-party validation dataset. The linked NIST, OWASP, Stanford HAI, OECD, IBM, and ISO materials inform the control choices in this article; none reviewed the run, its data, or its reported figures.
No independent party had reproduced this desk log as of 2026-08-31. We invite independent replication using a disclosed source grain, two competing metric definitions, an unbound run, a bound run, and retained retrieval artifacts. A useful report should publish both confirming and conflicting results and must not imply endorsement by the framework publishers.
An external knowledge base replication should also disclose document versions and retrieval settings.
Verified external guidance and open reproduction
Aqua Book and GAO reliability guide were checked 2026-08-31. They support quality assurance, source reliability, and limitations—not endorsement.
The external-source check records links, roles, dates, and non-endorsement. The independent-reproduction protocol defines source, document, conflict, recalculation, and publication requirements. Running the first-party verification script only confirms that the CSV matches the desk log. It does not validate the private composite or independently prove this knowledge base result.
This evidence package has no DOI and is not registered with DataCite. A DOI should be added only after depositing a citable artifact with a real registration agency; inventing one would reduce, not improve, authority.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Desk log on this page | Grain, collision, artifact counts, ~22 min wall-clock, run ID | Customer uplift %, official EEAT score, named-logo case |
| Third-party frameworks and research | Published risk, privacy, security, governance, and measurement guidance | That any publisher ran or endorsed this desk log |
| Author profile and repositories | Public identity, cofounder role, and open-source engineering record | Independent verification of product performance |
| Homepage recognition | 2026 WAIC Future Tech OPC Excellence Award as published on the company homepage | That WAIC, NIST, or Gartner scored this article |
Desk log: 14,000-row orders extract; two owners of margin; artifacts 1 / 1 / 2 / 1 after bind. External context is limited to the linked framework and research publications.
How to cite this page
Use this form for the page: Zhu, W., & InfiniSynapse Data Team. (2026). Knowledge base: bind it before you trust the number. InfiniSynapse. https://infinisynapse.com/en/blog/data-knowledge-base
Use this form for the run: InfiniSynapse Data Team. (2026). Desk log KB-MARGIN-20260822 (sanitized composite). https://infinisynapse.com/blog-media/data-knowledge-base/downloads/desk-log-KB-MARGIN-20260822.md
The first form cites the knowledge base guide. The second cites only the first-party figures. Neither is a third-party audit. Readers who cite the desk figures should record the retrieval state, three labeled percents, artifact counts, source check, and open protocol. As of 2026-08-31, no independent reproduction report or DOI exists. Send contradictions promptly to zhuhl@infinisynapse.com.
Selection scorecard
Score a candidate the way you would score a junior analyst’s binder.
| Criterion | Weak | Strong |
|---|---|---|
| Bind | Files float in chat | Knowledge base is named and bound to a source |
| Retrieval | Whole-drive dump | Small, owned packs |
| Evidence | Final paragraph only | Passages plus query plan in artifacts |
| Secrets | Tokens in notes | Sanitized language only |
| Replay | New chat every Monday | Same goal, same bound pack |
If a tool cannot bind a knowledge base to a live source, it is a writing assistant. If it can bind but cannot show what it retrieved, it is a risk. The OWASP GenAI/LLM Top 10 (retrieved 2026-09-04) identifies prompt injection and sensitive-information disclosure among material LLM-application risks. Applied here, uploaded documents are untrusted input and must be screened for instructions and secrets before retrieval. OWASP did not evaluate this product.
Failure modes that break trust
Three patterns show up every time the pack is treated as a dumpster.
Unlabeled scans and empty PDFs
The folder looks complete. Retrieval is empty. The model improvises. Label this as “no text layer,” not as “the model is bad.” Rebuild the pack from source documents you can search.
Binding the wrong source
Clean notes bound to last year’s replica will retrieve the right words and the wrong grain. Bind is a join. Check both sides. If you have two replicas, name them in the pack so retrieval cannot cite the retired one.
Treating chat history as the pack
People paste a definition once, get a good answer, and never upload a pack. The next hire starts from zero. Chat history is not durable context. If the sentence matters next quarter, it belongs in the bound pack.
Before you trust any generated definition, inspect whether notes are bound to the source you asked about, whether the retrieved passage is the approved one, and whether the task artifacts show that passage next to the query. That inspection is the diagnosis.
Cluster guides under this hub: AI Knowledge Base for Data Analysis; Bind a Knowledge Base to a Database; Schema Documentation an AI Analyst Can Retrieve; Upload Analysis Reports as Context; Knowledge Base vs Semantic Layer; What to Put in a Data Knowledge Base; What Is a Knowledge Base for Analysis; Knowledge Base Software for Live Data; Knowledge Base Examples an Analyst Can Retrieve; Internal Knowledge Base Software Teams Can Audit; Knowledge Base Content: What to Bind First.
Related hops: organizational analysis memory; multimodal data analysis; explainable AI data analysis; self-service data analysis for business; AI data report generator.
Bind a knowledge base before you trust the definition
Upload a short, sanitized pack, bind it to one authorized source, and ask the same goal you already use in review. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseSourcing and accountability. William Zhu is an InfiniSynapse cofounder; his public GitHub profile and linked repositories provide a verifiable engineering record. First-party recognition: 2026 WAIC Future Tech OPC Excellence Award (homepage; Agentic Data Infra entry—self-described, not independently verified here, and not a review of this page). Editorial standards govern corrections and conflicts. Verification records: source check · open reproduction protocol. COI: InfiniSynapse sells an AI-native Data Agent. All numeric results come only from first-party desk log
KB-MARGIN-20260822. External guidance does not validate that run.
Frequently Asked Questions
Is a knowledge base the same as a semantic layer?
Bottom line: No. A semantic layer compiles measures. The pack retrieves the documents that explain those measures, including exceptions a DSL never captured. Use both when you have both; bind notes when the missing object is a memo.
Can one knowledge base cover every database?
Bottom line: It should not. Retrieval gets noisy. Bind a focused pack per decision domain, even if several packs attach to the same source. A giant company-wide dump is how the wrong memo wins.
What files should I upload first?
Bottom line: A field dictionary and one signed report. That pair is a complete first pack. Add exception lists next. Skip scans and unread shared-drive archives.
Does binding write back to production?
Bottom line: No. Binding notes does not write definitions into the database and does not update production tables. It restricts what the agent may retrieve while it reads sources you authorize.
How do I know the knowledge base was used?
Bottom line: Open the task artifacts and look for retrieved passages that match your pack. If you only see a fluent paragraph, you do not have evidence that the pack participated.
Has an independent party reproduced the margin result?
Bottom line: For this knowledge base, no qualifying independent report exists as of 2026-08-31. The open protocol defines what an external report must disclose. The verification script checks only the published aggregate CSV; it cannot validate the private sanitized composite, create a DOI, or supply third-party endorsement.
Conclusion
A knowledge base is not a smarter chat window. They are the language that tables refuse to store. Write the pack, bind it to a live source, and refuse answers that cannot show the passage they used.