Schema Documentation: Bind Notes, Then Replay
By William Zhu (public engineering profile: GitHub @allwefantasy) & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-08-28 · Last verified: 2026-08-28 · Next review: 2026-11-28 · About · Editorial standards · Privacy · Publishing terms · Corrections
Table of Contents
- TL;DR
- What schema documentation must do for retrieval
- Author qualifications and accountability
- A field-note framework the agent can find
- How retrievable notes differ from catalog comments
- Tool landscape for field notes
- Implementation steps from one table to a replay
- Desk sample: status = 3 in two dictionaries (InfiniSynapse desk log)
- Evidence boundaries and external validation status
- How to cite this page
- Selection scorecard
- Failure modes that make documentation invisible
- Frequently Asked Questions
- Conclusion
TL;DR
We evaluate field dictionaries at the InfiniSynapse desk on sanitized composites; first-party figures on this page are desk log KB-SCHEMA-STATUS3-20260822, not customer uplifts and not a third-party bake-off.
Direct answer: Schema documentation an agent can retrieve is a short, owned field dictionary—official names, aliases, codes, grains, and exclusions—bound to the live source those columns sit in. Catalog comments help humans browse. Schema documentation helps a professional AI data analyst reuse your language when the question arrives.
What you'll learn:
- Why field guidance fails when it lives only as a comment on a column
- Which sentences belong in a retrievable dictionary and which sentences waste retrieval
- How to upload field notes, bind them, then ask the same column twice
- Desk log
KB-SCHEMA-STATUS3-20260822, wherestatus = 3meant two different lives - A scorecard and three failure modes that make documentation look complete and stay invisible
Download evidence: desk log · aggregate CSV · verify script. These files record this desk run as a first-party sanitized composite.
Industry context stays independent of desk claims. The NIST AI Risk Management Framework (retrieved 2026-08-28) supports mapping, measuring, managing, and governing AI risk. Applied here, teams map fields to owners, measure whether approved definitions retrieve, manage failed replays, and preserve accountability. Auditable schema documentation keeps those decisions inspectable. NIST did not assess this product or desk log.
What schema documentation must do for retrieval
Key Definition: Schema documentation for an AI analyst is a curated field dictionary bound to a live source so retrieval returns the official name, aliases, grain, and exclusion list with the query plan. It is not a 200-page ERD, a comment that only the catalog UI shows, or a wiki page nobody bound.
ISO/IEC 11179-3 (retrieved 2026-08-28) specifies a registry metamodel and attributes for data-element descriptions. Applied here, field notes should preserve names, definitions, representations, owners, approval state, and versions. The W3C Data Catalog Vocabulary 3 (retrieved 2026-08-28) defines metadata for catalogs, datasets, data services, and distributions. Portable schema documentation preserves that review context. These standards support explicit metadata; neither organization evaluated InfiniSynapse.
Internal terms this page uses: a field dictionary is the searchable file of official names, aliases, codes, grains, and exclusions. A catalog comment is a note that lives only in a catalog UI. Grain is the unit one row represents (account versus invoice). A code table maps integers such as status = 3 to owned language.
Author qualifications and accountability
William Zhu is an InfiniSynapse cofounder. His public GitHub profile identifies that role and links engineering work. Public repositories include auto-coder, byzer-llm, and BYZER-RETRIEVAL. These links verify identity and relevant open-source experience; they do not independently validate this schema documentation or desk log.
The author is accountable to the site’s editorial standards, including corrections and conflict-of-interest disclosures. InfiniSynapse sells the workflow described here, so product descriptions and desk results are first-party claims unless an external source is explicitly cited. The homepage records a 2026 WAIC Future Tech OPC Excellence Award for an Agentic Data Infra entry; that is company recognition, not a review of this page. Method note: 2026-07-29 attestation.
Schemas are silent. status = 3, gm, and active_at are legal columns. They are not a business. Until the field dictionary names the codes, the exclusions, and last quarter’s exception, every fluent paragraph is a guess dressed as analysis.
The NIST Privacy Framework (retrieved 2026-08-28) helps organizations identify and manage privacy risk. Applied here, field dictionaries should name codes and approved meanings without copying personal records or customer-identifying examples. Privacy-aware schema documentation records only necessary context. NIST did not review these notes.
If you still need the analysis-versus-FAQ contrast, see the FAQ-versus-notes desk pass on the data knowledge base hub. If the next failure is attaching those notes to the wrong replica, use bind knowledge base to a database. The hub for the pack model sits in data knowledge base.
What is data management covers the broader practice. The dictionary is the thin slice an agent can actually retrieve.
Comments that never leave the catalog
Catalog comments are valuable for humans who click a table. They are weak schema documentation for an agent unless you export them into a bound pack. Hoping every run reads every comment is how status keeps meaning “ask Sarah.” Export the comments you trust. Add the aliases people actually say. Bind the file. Then chat with your data has a dictionary, not a hope.
The OWASP GenAI/LLM Top 10 (retrieved 2026-08-28) highlights prompt injection and sensitive-information disclosure. Treat imported field guidance as untrusted input, remove tokens and raw identifiers, and prevent note text from overriding query controls. Screened schema documentation reduces avoidable exposure. OWASP did not review this implementation.
Sentences an analyst would search
Retrievable schema documentation uses the words people ask: “active subscriber,” “contribution margin,” “DACH.” Put the official name, the aliases, the grain, and the exclusion list in the same short section. A novel about the table’s history will bury the line. A one-line comment that says “user state” will retrieve and still leave 3 unexplained.
If two teams fight over a code, put both definitions in the field dictionary and label the owner. Ambiguity that is written down is safer than ambiguity the model invents.
A field-note framework the agent can find
Use this table as the operating model. It is a control map, not a vendor score.
| Layer | What you store | What the agent does | Failure if missing |
|---|---|---|---|
| Source | Live database or files | Plans against current schema | Answers invent tables |
| Schema documentation | Field notes, code tables, grains | Retrieves the row that names the code | Answers invent meanings |
| Bind | Source ↔ dictionary link | Restricts retrieval to that dictionary | A retired wiki wins |
| Task artifacts | Markdown, charts, data files | Shows the retrieved row next to SQL | Chat bubbles become the record |
Official dbt documentation distinguishes three useful controls: resource descriptions (retrieved 2026-08-28) preserve model and column meaning, data tests (retrieved 2026-08-28) assert properties about resources, and model contracts (retrieved 2026-08-28) enforce a defined shape for public models. Tested schema documentation connects descriptions to visible checks. Those controls are not identical to a bound field dictionary, but they show why descriptions, validation, and contracts are separate concerns. dbt Labs did not assess this page.
Schema documentation: what belongs in the dictionary
Put durable column language in schema documentation: official names, aliases, status-code tables, grains, known dirty joins, and the last approved exception. Prefer searchable text—Markdown, Word, text, and text-based PDF. One dictionary can serve several related questions on the same source. Several dictionaries can bind to the same source when finance and ops disagree.
Leave ERD screenshots with no text layer, raw email dumps, and drafts that were never approved out of schema documentation. A pack that retrieves a rejected deck will sound confident and still be wrong.
Write the notes as if a new analyst starts Monday. If a sentence only makes sense after a Slack thread, it is not ready.
How retrievable notes differ from catalog comments
A catalog tells you a table exists and who owns it. Schema documentation tells you how a column is used in a decision. Binding is the act that attaches that usage language to a live source so retrieval cannot wander into a neighboring wiki.
Catalogs stay valuable. They do not replace the dictionary. If your catalog already holds rich field comments, export those comments into the pack. Retrieval is cheaper when the dictionary is small and bound.
The semantic layer compiles measures. The dictionary explains columns, including the exceptions a DSL never captured. You usually need both. A measure named active_customers still fails if status = 3 is undocumented.
Why guessed comments survive in chat
People paste a column list into a thread, get a good answer, and never write the dictionary. The next hire repeats the paste. Chat is not a dictionary. If the code table matters next quarter, it belongs in the bound pack. Natural language to SQL will keep producing legal filters on status until the notes say which integers are legal.
Google Cloud’s Dataplex glossary documentation (retrieved 2026-08-28) describes glossary categories and terms for shared business vocabulary. A glossary can supply approved terms, but retrieval still requires an explicit mapping to the source and task. This vendor documentation defines capability; it is not an endorsement or evaluation of InfiniSynapse.
Tool landscape for field notes
Three patterns show up in 2026 buying conversations.
Catalog-only comments. Strong for browsing. Weak for retrieval unless exported.
Wiki pages nobody bound. Strong for humans who already know the URL. Weak for an agent that can see three conflicting pages.
Bound dictionary plus live query. Upload the dictionary, bind it to PostgreSQL, Snowflake, MySQL, files, or another authorized source, then ask a goal. InfiniSynapse’s path is Knowledge Base → upload TXT, Markdown, Word, PPT, or PDF → Bind Data Source → ask in Chat with that source selected. InfiniRAG retrieves the notes; InfiniSQL plans against the live schema.
InfiniSynapse does not ship a prebuilt metric warehouse and does not write schema documentation back into production catalogs. It reads the source you authorize and retrieves the pack you bound.
File types the desk actually uploads
The desk’s working schema documentation is short: a Markdown field dictionary, a one-page code table, and last quarter’s exception list. PowerPoint is acceptable when the text extracts. Images of whiteboards are not. If you cannot copy a sentence out of the file, do not put that file in retrieval.
One dictionary per decision domain beats one giant dump. “Finance status codes” and “ops fulfillment codes” can both bind to the same orders database. Mixing them in a single dump makes retrieval noisy.
Implementation steps from one table to a replay
- Pick one authorized table. Prefer a replica or sanitized extract. Expected result: One named table is selected.
- Write notes for five columns. Document the columns people ask about, not every warehouse field. Expected result: The dictionary names official terms, aliases, codes, and grain.
- Upload, then bind. Bind the dictionary to the named source as a separate action. Expected result: The source-to-dictionary mapping is inspectable.
- Ask one goal. Ask in Chat with the source selected, not for a SQL snippet. Expected result: The task starts from an analysis goal against the named source.
- Inspect the artifacts. Confirm the retrieved row names the trusted code. Expected result: The approved definition appears beside the query plan.
- Replay next week. Ask about the same column again. Expected result: The same row is retrieved unless a visible version changed.
These steps are educational. Finish the diagnosis on this page before you upload.
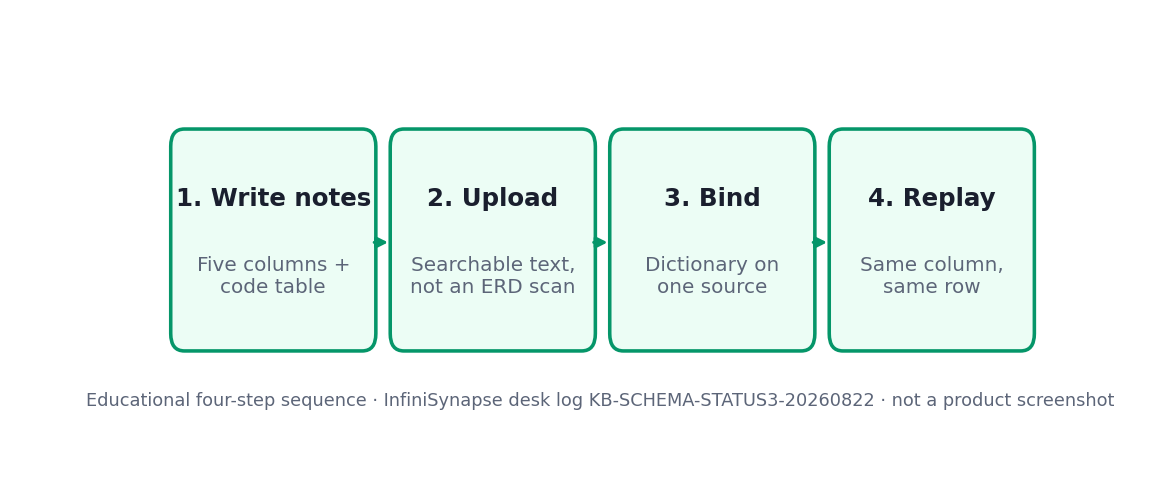
Figure. Educational four-step sequence the desk uses to tell a catalog comment from a bound dictionary. Expected result after step 5: the retrieved row names the code you trust. Not a product screenshot or a customer SLA.
Write field notes that retrieve
Retrievable schema documentation uses the words people ask and the integers the warehouse stores. Put them in the same section:
- Official name: active subscriber
- Aliases: paying user, live account
- Column:
status - Legal values for this question:
3= active,4= paused;5is retired - Grain: one row per account, not per invoice
- Exclusions: internal test accounts
Long novels bury that block. Notes that only store official names will miss the aliases finance uses in review.
Upload field notes, then ask the same column twice
The acceptance test is boring: same source, same column, same retrieved definition. If week two cites a different wiki, the bind is wrong or the schema documentation contains two owners. Fix the notes; do not “clarify” in chat and walk away. Chat is not the system of record.
If week two invents status = 3 as “trial,” the notes never entered retrieval. Rebind. Then ask again.
Desk sample: status = 3 in two dictionaries (InfiniSynapse desk log)
This is a first-party InfiniSynapse desk log of bound schema documentation, not a named-logo customer case and not an uplift claim. Run ID: KB-SCHEMA-STATUS3-20260822. Date: 2026-08-22. Operator: InfiniSynapse Data Team. Source: a sanitized 9,600-row accounts extract the desk is authorized to read. Goal asked twice: “How many accounts are active?”
The extract used status = 3. An old ops wiki treated 3 as active. A two-page finance dictionary treated 3 as pending review.
| Retrieval state | Treated as active | Treated as pending review |
|---|---|---|
| Ops wiki louder | 9,600 | 0 |
| Bound finance dictionary | 0 | 9,600 |
Without a bound dictionary, the first answer treated all 9,600 as active and matched the louder wiki title. After the finance notes were bound—official name, aliases, and the retired-code list—the second run retrieved the finance row and labeled the ops meaning as a conflicting prior.
Nothing in the database changed. The notes changed what was allowed to count as active.
| Retrieval state | SQL | Memo | Chart | CSV | Finance row cited |
|---|---|---|---|---|---|
| Ops wiki louder | 1 | 0 | 0 | 0 | No |
| Bound finance dictionary | 1 | 1 | 2 | 1 | Yes |
Wall-clock for the bound rerun was 10 minutes (warehouse time excluded). The method, 9,600 / 0 flip, and artifact inventory are in the downloadable desk log KB-SCHEMA-STATUS3-20260822. Cite that file or this table as InfiniSynapse desk log KB-SCHEMA-STATUS3-20260822. Do not cite it as customer ROI, a bake-off win, an official EEAT score, or an AWS / NIST / CISA experiment. We do not publish named-logo customer cases on this page. The only honest claim is that the bound dictionary made the code collision visible.
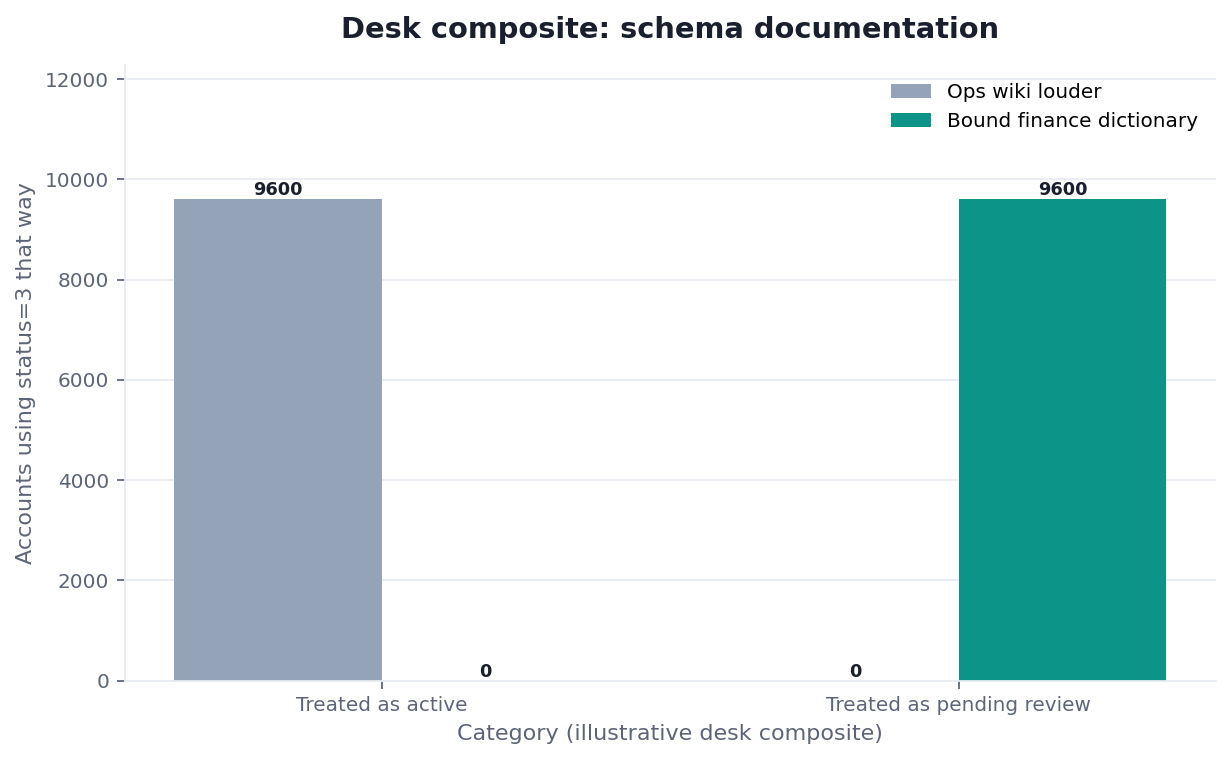
Figure. InfiniSynapse desk log KB-SCHEMA-STATUS3-20260822: 9,600-row accounts extract; status=3 collision. Published context: the independent sources linked in the body. Not a customer experiment, SLA, or official benchmark.
Evidence boundaries and external validation status
Desk log KB-SCHEMA-STATUS3-20260822 and its downloadable file are first-party, reproducible sanitized-composite examples. They are not customer cases, independent benchmarks, third-party datasets, certifications, media evaluations, or endorsements. The download improves transparency by preserving the method, code collision, counts, and artifact inventory; publication does not turn it into independent evidence.
No independent party had reproduced this desk log as of 2026-08-28. A third-party replication should disclose source grain, row count, and version; dictionary versions and owners; code mappings; bind mapping; retrieval configuration; query, SQL, and retrieved passage; the unbound baseline; all results and failures; run time; and commercial conflicts of interest. Both confirming and conflicting outcomes should remain visible.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Desk log on this page | Grain, collision, 9,600 / 0 flip, artifact counts, ~10 min wall-clock, run ID | Customer uplift %, official EEAT score, named-logo case |
| Downloadable desk log | Same counts and the four-step method | That the file is a customer extract or a third-party audit |
| Third-party standards and official docs | Published metadata, catalog, description, test, contract, glossary, risk, privacy, and security guidance | That any publisher ran or endorsed this desk log |
| Author profile and repositories | Public identity, cofounder role, and open-source engineering record | Independent verification of product performance |
| Homepage recognition | 2026 WAIC Future Tech OPC Excellence Award as published on the company homepage | That WAIC, NIST, or Gartner scored this article |
How to cite this page
Use this form for the page: Zhu, W., & InfiniSynapse Data Team. (2026). Schema documentation: bind notes, then replay. InfiniSynapse. https://infinisynapse.com/en/blog/schema-documentation-for-ai
Use this form for the run: InfiniSynapse Data Team. (2026). Desk log KB-SCHEMA-STATUS3-20260822 (sanitized composite). https://infinisynapse.com/blog-media/schema-documentation-for-ai/downloads/desk-log-KB-SCHEMA-STATUS3-20260822.md
The first form cites the guide. The second cites only the first-party figures. Neither form is a third-party audit. Cite the retrieval state and the 9,600 / 0 flip. As of 2026-08-28, no independent reproduction report exists. Send contradictions to zhuhl@infinisynapse.com.
Selection scorecard
Score the candidate the way you would score a junior analyst’s dictionary.
| Criterion | Weak | Strong |
|---|---|---|
| Retrieval | Comments stay in the catalog UI | Schema documentation is a bound file |
| Completeness | Every table, no codes | Few columns, explicit integers |
| Owners | One dump, two meanings | Labeled conflicts |
| Evidence | Final paragraph only | Retrieved row plus query plan |
| Secrets | Raw identifiers in examples | Sanitized codes only |
| Replay | New paste every Monday | Same column, same dictionary |
If a tool cannot retrieve schema documentation with the plan, it is a writing assistant. If it can retrieve but cannot show the row, it is a risk.
Failure modes that make documentation invisible
Three patterns show up every time people treat schema documentation as a wiki they already have.
ERD images with no text layer
The folder looks official. Retrieval is empty. The model improvises status. Label this as “no text layer,” not as “the model is bad.” Rebuild schema documentation from source text you can search.
Catalog comments that were never exported
Rich comments that never leave the catalog do not participate. Export them. Bind them. Ask the column twice. Notes that exist only in a UI the agent does not read are decoration.
Treating a chat paste as the dictionary
People paste a code table once, get a good answer, and never upload schema documentation. The next hire starts from zero. Chat history is not durable context. If the integer matters next quarter, it belongs in the bound pack.
Before you trust a generated definition, inspect whether field notes are bound to the source you asked about and whether the task artifacts show the approved row next to the query.
When the next missing object is not this page, open Upload Analysis Reports as Context when Signed reports are priors, not a second analysis, Knowledge Base vs Semantic Layer when Documents retrieve; contracts compile, or What to Put in a Data Knowledge Base when A first pack is a dictionary plus one signed report.
Cluster guides under this hub: Data Knowledge Base; Bind a Knowledge Base to a Database; What Is a Knowledge Base; Knowledge Base Software; Knowledge Base Examples; Internal Knowledge Base Software; Knowledge Base Content. Related technical hops remain Natural Language to SQL, Chat with Your Data, and What Is Data Management.
Upload field notes, then ask the same column twice
Upload a short, sanitized field dictionary, bind it to one authorized source, and ask the same column you already argue about in review. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseSourcing and accountability. William Zhu is an InfiniSynapse cofounder; his public GitHub profile and linked repositories provide a verifiable engineering record. First-party recognition: 2026 WAIC Future Tech OPC Excellence Award (homepage; Agentic Data Infra entry—not a review of this page). The downloadable desk log
KB-SCHEMA-STATUS3-20260822preserves this first-party run. Editorial standards govern corrections and conflicts. COI: InfiniSynapse sells an AI-native Data Agent. External sources do not validate the run.
Frequently Asked Questions
Is schema documentation the same as a catalog?
Bottom line: No. A catalog lists tables and owners. Schema documentation is the retrievable dictionary of names, aliases, codes, and exclusions bound to a live source. Export catalog comments into the pack if they are the best notes you have.
Can one file cover every table?
Bottom line: It should not. Retrieval gets noisy. Write schema documentation for the columns people ask, per decision domain. A warehouse-wide novel is how the wrong code table wins.
What should I write first?
Bottom line: Five columns and one code table. That pair is a complete first dictionary. Add grains and exclusions next. Skip ERD screenshots with no text layer.
Does uploading schema documentation write back to the database?
Bottom line: No. Binding notes does not write comments into production and does not update tables. It restricts what the agent may retrieve while it reads sources you authorize.
How do I know the dictionary was used?
Bottom line: Open the task artifacts and look for the retrieved row that names the code. If you only see a fluent paragraph, you do not have evidence that schema documentation participated. Label the retrieved row in the memo so a later reviewer can replay the same check.
What is a field dictionary?
Bottom line: A field dictionary is the searchable file of official names, aliases, codes, grains, and exclusions. It is the object schema documentation must store. A catalog comment is not a field dictionary until you export it and bind it.
What does grain mean in the dictionary?
Bottom line: Grain is the unit one row represents. Write “one row per account, not per invoice.” Schema documentation without grain will retrieve a code and still invent the join.
Conclusion
Schema documentation is not a prettier ERD. It is the field language that columns refuse to store. Write the dictionary, bind it to a live source, and refuse answers that cannot show the row they used. When you want to run that schema documentation check on an authorized source, open InfiniSynapse and ask the same column twice before the next review meeting.