Institutional Knowledge: Bind, Then Replay
By William Zhu (independent public engineering profile: GitHub @allwefantasy; no personal LinkedIn) & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-08-29 · Last verified: 2026-08-29 · Next review: 2026-11-29 · About · Editorial standards · Privacy · Publishing terms · Corrections
Table of Contents
- TL;DR
- What institutional knowledge means in analysis
- An accumulation framework
- How organizational memory differs from personal chat
- Tool landscape for accumulating context
- Implementation steps from lock-in to second run
- Desk sample: two-week KPI pack (InfiniSynapse desk log)
- Selection scorecard
- Failure modes that erase context
- Frequently Asked Questions
- Conclusion
TL;DR
We evaluate these patterns at the InfiniSynapse desk on sanitized composites; first-party figures on this page are desk log OAM-HUB-20260822, not customer uplifts and not a third-party bake-off.
Direct answer: Institutional knowledge includes routines, documents, roles, norms, systems, repositories, and social memory. This page presents an analytics-specific pattern: governed definitions and replayable evidence. Properly retained and governed chat can contribute evidence, but raw private threads are rarely an authoritative system of record.
Download evidence: desk log · aggregate CSV · verify script. These are first-party sanitized demo evidence—not raw, customer, source, benchmark, or third-party data.
What you'll learn:
- Why durable organizational context is not a transcript or a warehouse project
- How to lock five definitions before you scale a memory program
- How replay templates turn last week’s pack into this week’s starting point
- Desk log
OAM-HUB-20260822, of a two-week KPI comparison on one bound pack - Failure modes: definition drift, personal notebooks, and rewriting the prompt instead of replay
Foundational research frames the subject broadly. Walsh and Ungson’s organizational memory paper describes organizational acquisition, retention, and retrieval; Argote and Miron-Spektor’s organizational learning framework examines experience, context, and knowledge; and Alavi and Leidner’s knowledge-management review analyzes knowledge creation, storage/retrieval, transfer, and application. These frameworks do not test this desk run.
Interoperability and governance references cover narrower controls: ISO 30401 specifies knowledge-management-system requirements; PROV-O models provenance; SKOS represents concept schemes; DCAT 3 describes data catalogs; and FAIR principles address findability, accessibility, interoperability, and reuse. NIST Privacy Framework, NIST AI RMF, and OWASP GenAI inform privacy and AI risk—not product endorsement.
Analytics platforms can carry portions of memory: dbt Semantic Layer, MetricFlow, OpenMetadata glossary, and DataHub glossary document governed terms and metrics. Warehouses, semantic layers, catalogs, glossaries, wikis, and ticketing systems may each hold part of the record. None evaluated OAM-HUB-20260822. Retrieved 2026-08-29.
An institutional knowledge architecture may combine several of these systems rather than nominate one universal repository.
Author qualifications and accountability
William Zhu is an InfiniSynapse cofounder. GitHub @allwefantasy, auto-coder, byzer-llm, BYZER-RETRIEVAL, and the InfiniSynapse organization verify public project activity—not education, knowledge-management certification, customers, or independent evaluation.
This page is first-party. The authors sell the workflow. It is not an independent review. 2026 WAIC Future Tech OPC Excellence Award (homepage; not a review). 2026-07-29 attestation.
If the missing object is durable context rather than a one-off pack, continue in data knowledge base. If the next failure is a join across modes or engines, use explainable AI data analysis.
What is data management covers the broader discipline. This hub is narrower: how institutional knowledge enters the analysis loop so a data agent can retrieve it and a teammate can replay it.
Chat history is not memory
Threads feel like memory because they are full of sentences. They die with the product, the seat, or the person who knew which thread mattered. A new hire cannot search “the March exception” across private chats and call that a program. Durable knowledge has a name, an owner, and a bind.
Governed chat can contribute to institutional knowledge when retention, access, indexing, ownership, and deletion rules are explicit.
If your only memory is “we told the model last time,” you will tell it again. That is labor, not accumulated context.
Approved definitions are
Write the five words that cause the most arguments. Put the official meaning, the aliases, the grain, and the exclusion list in a short document. That document becomes an organizational asset the moment an owner signs it and you bind it to the source. Until then it is a draft. The semantic layer can hold the compiled form; institutional knowledge still holds the memo the compiler never saw.
An accumulation framework
| Object | What it stores | How it accumulates |
|---|---|---|
| Definition pack | Approved language | Bind to a source; revise on purpose |
| Replay template | Standing goal + window rule | Rerun; do not rewrite from scratch |
| Task artifacts | Evidence from each run | Compare week n to week n+1 |
| Exceptions | Known dirty joins, one-offs | Add to the pack after sign-off |
| Non-memory | Chat, screenshots, hallway fixes | Discard or promote |
Context only moves downward in that table when someone promotes it. Promotion is a decision. Auto-saving every prompt is how you get a junk drawer and call it culture.
A small-pilot heuristic
Five contested terms is this page’s small-pilot heuristic, not a research-proven optimum or program requirement. Select a manageable set, assign owners and approvers, record effective dates and aliases, then expand when governance and replay evidence are working.
The right institutional knowledge pilot size depends on risk, review capacity, domain scope, and existing governance.
Replay templates as assets
A replay template can preserve a standing goal, but replay alone cannot guarantee stable knowledge. Pin definition versions, owners, approvals, effective dates, aliases, grain, lineage, access, retention, supersession, change logs, and task and source snapshots.
The first-party demo binds a definition pack, uses authorized read-only sources, and compares task artifacts without writeback. Binding only makes a document retrievable in this workflow; it does not automatically make the document approved or institutional.
Approval and lifecycle controls—not binding alone—promote content into governed institutional knowledge.
How organizational memory differs from personal chat
Personal chat can become an evidence input when retention, access, ownership, indexing, privacy, and governance are appropriate. Raw private chat usually lacks those controls. Analytics definitions require an owner and approval path. Data governance is the policy wrapper; institutional knowledge is the retrieval object the policy needs.
Do not confuse “the agent remembered my last prompt” with institutional knowledge. Session memory helps one person. Institutional knowledge helps the next person who was on leave.
Tool landscape for accumulating context
Chat products. Governed, retained, indexed threads can contribute evidence; private raw chat generally should not be the authoritative record.
Warehouses, semantic layers, catalogs, glossaries, wikis, and tickets. Each can retain part of the organization’s definitions, decisions, provenance, or evidence when ownership and lifecycle controls are explicit.
Bound packs plus replayable tasks. Upload the definition document, bind it to the live source, run a standing goal, keep Markdown and charts in the workspace, rerun. The educational path is ordinary: Knowledge Base → bind → Chat or CLI → /tasks comparison. Retrieval reads the pack; the planner writes SQL; artifacts stay downloadable.
CLI users can start the same replay from agent_infini. The memory is still the pack and the task, not the terminal.
Knowledge packs versus warehouses
A warehouse can be empty of institutional knowledge. A laptop folder can be full of it. Prefer a bound pack you can retrieve over a migration you cannot staff. If you already have a warehouse, still bind the language. Storage did not settle the argument.
Task replay versus new chats
New chats feel cleaner. They erase last week’s language. Replay the task. If the world changed, change the pack on purpose and record why. That audit trail is the memory.
Implementation steps from lock-in to second run
- Select a manageable pilot set and name owners and approvers. Expected result: scope and accountability are explicit.
- Version definitions, aliases, grain, exclusions, effective dates, and supersession. Expected result: the active meaning is identifiable.
- Record source schema, snapshot, access, lineage, privacy, and retention. Expected result: evidence inputs are governed.
- Run a versioned goal and retain retrieval passages, queries, transforms, status, errors, and artifacts. Expected result: execution is inspectable.
- Have a third person replay and review the pack. Expected result: knowledge is usable beyond the original analyst.
- Log changes, approvals, deletion, and new effective dates before the next run. Expected result: evolution is attributable.
You can do the educational diagnosis with a paper list of five terms and last week’s slide. The web app is how you bind and replay once that list is honest. If the five terms still change in the hallway, fix the owners before you add a sixth page.
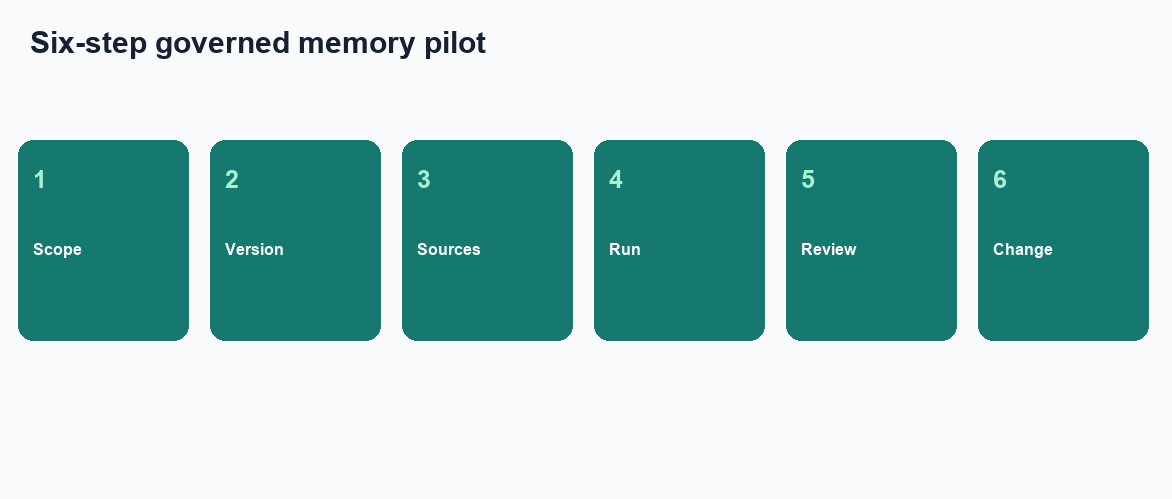
Figure. Educational four-step sequence the desk uses to tell a chat diary from an accumulating pack. Expected result after step 6: week two reuses the same sentence and a third person can open both folders. Not a product screenshot or a customer SLA.
Bind the definition pack
Binding can make a document retrievable to this first-party workflow. Approval, ownership, effective dates, access, retention, and change control determine whether the content is authoritative.
Replay the same goal a week later
The second run is the product. The first run is a prototype. Institutional knowledge that cannot survive a week was never institutional. Compare files, not vibes. Open both task folders, line up the Markdown packs, and mark any number that moved. If the definition language also moved, two owners are still in the pack or someone edited the goal. Fix the pack in the open, then rerun once more so the next person inherits a stable sentence.
Desk sample: two-week KPI pack (InfiniSynapse desk log)
This is a first-party InfiniSynapse desk log of institutional knowledge, not a named-logo customer case and not an uplift claim. Run ID: OAM-HUB-20260822. Date: 2026-08-22 (Saturday). Operator: InfiniSynapse Data Team. Sources: a read-only replica plus a sanitized store-status file. Contrast: chat diary as the system of record versus a five-definition bound pack. Download the same numbers as desk log OAM-HUB-20260822.
The chat path left “active store” in three threads. Week two needed a new explanation. Nobody replayed a standing goal. A third person could not open last week’s language without asking who said it.
The bound path locked five definitions—including one official “active store”—and attached that pack to the replica. Week one produced a Markdown pack. Week two used the same goal. One number moved because a store flipped status. “Active store” did not. A third person opened /tasks and saw both runs. Nobody asked the original analyst to “just send the SQL.”
| Retrieval state | Chat as system of record | Bound pack replayed | Week-2 language held |
|---|---|---|---|
| Chat diary only | 1 | 0 | 0 |
| Bound pack accumulation | 0 | 1 | 1 |
Wall clock for the successful week-two rerun was about sixteen minutes (warehouse time excluded). The clock started when the operator opened the standing goal and ended when both folders sat side by side with the featured queries open. It does not include replica provisioning or a design review. Cite this table as InfiniSynapse desk log OAM-HUB-20260822. Do not cite it as customer ROI, a 40% shorter Monday, a bake-off win, or a Wikipedia / CISA / Gartner experiment. We do not publish named-logo customer cases on this page. The only honest claim is the artifact counts and the wall-clock on this run. The NIST AI Risk Management Framework and OWASP Top 10 for LLM Applications stay in the risk overlay: bind only authorized, sanitized sources. Those publications did not time this Monday.
We are not attaching a percentage. That is institutional knowledge working. The definition did not have to be retaught.
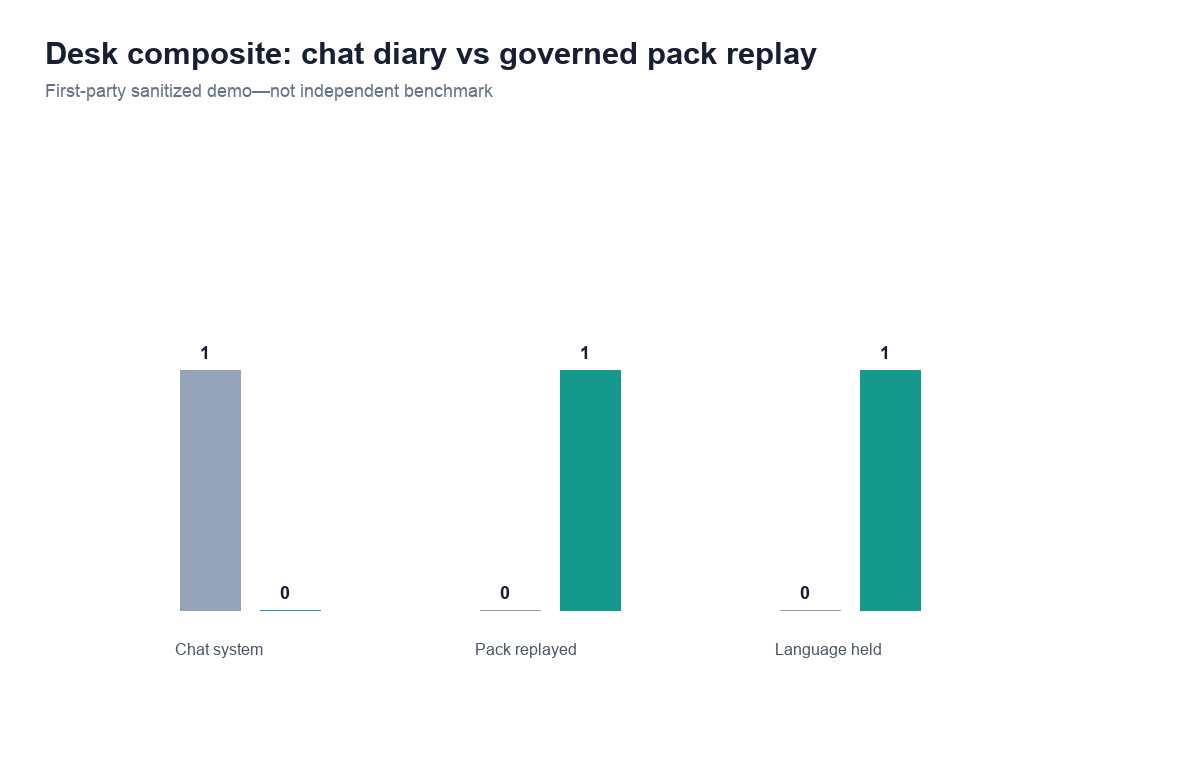
Figure. InfiniSynapse desk log OAM-HUB-20260822: the chat path left 1 / 0 / 0; the bound pack left 0 / 1 / 1. Published context: the independent sources linked in the body. Not a customer experiment, SLA, or official benchmark.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Desk log on this page | Artifact counts 1/0/0 → 0/1/1, ~16 min wall-clock, run ID, downloadable log | Customer uplift %, vendor bake-off win, named-logo case |
| External research and standards | Organizational memory processes, provenance, vocabularies, catalogs, privacy | That those sources ran this desk log |
Evidence boundaries and external validation status
OAM-HUB-20260822 is a first-party sanitized composite/demo—not raw, customer, source, benchmark, or third-party data. As of 2026-08-29, no independent third party, media outlet, or customer had reproduced it. Research supports organizational memory and knowledge processes; it does not validate 1/0/0 → 0/1/1 or 16 minutes.
The institutional knowledge observation is therefore limited to this documented first-party scenario.
Replication should disclose system, tool, model, version, configuration, retrieval settings; definition-pack version, owner, approver, effective date; source schema, snapshot, access; metric, grain, aliases, exclusions, timezone; goal template; retrieved passage IDs; query and transform; run IDs, status, errors, timestamps; artifact hashes; chat baseline; all failures; third-person review; privacy, retention, deletion; wall clock; and conflicts of interest.
Selection scorecard
| Criterion | Weak | Strong |
|---|---|---|
| Locus | Personal chats | Named pack with owner |
| Bind | Files somewhere | Bound to the source |
| Replay | New prompt weekly | Same goal, compared artifacts |
| Scope | Boil the ocean | Five terms, then more |
| Privacy | Raw people data in notes | Minimized, authorized sources |
If a tool promises institutional knowledge but only offers longer context windows, score it as a chat upgrade. If it can bind and replay but encourages dumping HR files into the pack, stop and reread the NIST Privacy Framework.
The scorecard is an educational rubric, not a vendor ranking. Independent docs linked above describe organizational memory and a minimized ingest; they do not score this rubric.
Evaluate institutional knowledge against governance, retrieval, review, privacy, and change-control requirements appropriate to the organization.
Failure modes that erase context
Metric definition drift
Two weeks, two “actives.” The source may be stable. The pack may contain two owners. Promotion failed. Split the term or pick a winner. Do not let the model average them.
Personal notebooks as the system of record
The best analyst keeps a perfect local file. That file is not organizational memory. When they leave, the organization is a beginner again. Promote the file or admit you do not have memory.
Re-prompting instead of replaying
People “improve” the prompt every Monday. They call it craft. It is amnesia. Institutional knowledge wants the boring sentence. Change the pack when the business changes, not when you are bored.
Before you claim the team has memory, check that five definitions have owners, that the pack is bound, that last week’s goal can be rerun without a new essay, and that a third person can open both artifacts. That inspection is the diagnosis.
Broader institutional knowledge also requires attention to routines, roles, norms, repositories, and social transfer beyond analytics definitions.
Cluster guides under this hub: Institutional Knowledge Analytics; Recurring KPI Analysis without Rewriting SQL; Metric Definition Drift: Catch It on the Replay; Analysis Playbook Reuse from Past Cases; Team Memory vs Personal Chat History; How to Start Analysis Memory; Tribal Knowledge: Promote It or Lose Monday; Knowledge Sharing that Survives a Leave Week; What Is Institutional Knowledge in Analytics; Tribal vs Institutional Knowledge; Corporate Knowledge Management for KPI Language.
Related hops: data knowledge base; explainable AI data analysis; self-service data analysis for business; people analytics; embedded AI data analyst.
Replay last week’s pack with the same definitions
Bind the approved definition pack to one authorized source, rerun last week’s goal, and compare the two task folders. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseSourcing and accountability. Research, standards, and product documentation support scoped claims only; none evaluated this page. COI: InfiniSynapse sells the first-party workflow.
How to cite this page
Page: Zhu, W., & InfiniSynapse Data Team. (2026). Institutional Knowledge: inspect, then replay. InfiniSynapse
Run: InfiniSynapse Data Team. (2026). Desk log OAM-HUB-20260822 (sanitized composite)
Neither is an audit. Cite those artifact counts on this first-party desk run. No independent reproduction exists. Send contradictions to zhuhl@infinisynapse.com.
Frequently Asked Questions
Is chat history institutional knowledge?
Bottom line: No. Chat is a diary. Institutional knowledge is an owned, bound pack you can replay. If only one person can find the thread, the organization does not have the memory.
Do I need a warehouse to accumulate context?
Bottom line: No. Institutional knowledge binds to the sources you already have. A warehouse can store facts; it does not automatically store approved language. Bind the pack either way.
How many definitions should we pilot first?
Bottom line: Use a manageable set. Five is this page’s pilot heuristic, not a proven optimum or mandatory threshold.
Does accumulation write into production systems?
Bottom line: No. Binding a pack and replaying a task does not write definitions or rows into production. Institutional knowledge lives in the bound documents and the task artifacts.
How do we show auditors which definition was used?
Bottom line: Keep the pack version with the task artifacts. Institutional knowledge is auditable when the retrieved passages and the goal sit next to the numbers. A fluent paragraph alone is not evidence.
Are the object counts a third-party benchmark?
Bottom line: No. The 1 / 0 / 0 versus 0 / 1 / 1 counts are first-party desk log OAM-HUB-20260822. Institutional knowledge treats those counts as a chat-versus-pack test, not an SLA.
Conclusion
Institutional knowledge is broader than a definition pack. For this analytics pattern, govern definitions, provenance, access, effective dates, snapshots, and review evidence; treat chat as input only when lifecycle controls make that appropriate. When you want to run that check on an authorized source, open InfiniSynapse and compare the two task folders.