Explainable AI: Bind, Then Replay
By William Zhu (independent public engineering profile: GitHub @allwefantasy; no personal LinkedIn) & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-08-29 · Last verified: 2026-08-29 · Next review: 2026-11-29 · About · Editorial standards · Privacy · Terms of Service · Corrections
Meta Description: Explainable AI: download the desk pack, bind the exclusion line, then audit the plan versus SQL, and refuse unused paragraphs that hide the filter list.
Slug: /blog/explainable-ai-data-analysis-guide
Target keyword: explainable ai
Secondary: audit ai analysis, sql trace, agent reasoning trail
Table of Contents
- TL;DR
- What Explainable AI Means for Data Analysis
- The Audit Framework: Plan, Query, Citation, Artifact
- Three Ways Teams Try to Explain an Answer
- Tool Landscape for Auditable Analysis
- How to Audit an Agent Run
- Independent Research and Authority Boundary
- Third-Party Reproduction Protocol
- Media, Awards, and Endorsement Rules
- Desk Sample: An Illustrative Margin Question
- Scorecard: Can You Defend the Number
- Failure Modes That Look Fluent
- How to cite this page
- Frequently Asked Questions
- Conclusion
TL;DR
We review inspectable SQL trails at the InfiniSynapse desk on sanitized composites; first-party figures on this page are desk log ADR-XAI-20260825, not customer uplifts and not a third-party bake-off.
Direct answer: Explainable ai for analysis is not a longer chatbot reply. It is a reopenable trail: the plan, the SQL, the intermediate tables, and the citations sit next to the paragraph so a reviewer can accept, reject, or rerun the same goal on authorized sources.
What you'll learn:
- A 40-word definition of explainable ai that you can paste into a review checklist
- A four-layer audit frame: plan, query, citation, artifact
- How paragraph-only chat, one-shot copilots, and reopenable agent trails differ
- Five moves to inspect a finished task without trusting fluency
- Three failure modes that still look confident in a slide
Download evidence: desk log · aggregate CSV · verify script.
A fluent paragraph is a claim. That habit treats the claim as unfinished until someone can open the steps. If you cannot see the filter, the join, and the definition the model retrieved, you do not have analysis—you have narration. The rest of this guide is a desk method for making that distinction before a number enters a meeting.
What Explainable AI Means for Data Analysis
Key Definition: Explainable ai is an analysis practice where a reviewer can reopen the plan, the SQL, the intermediate tables, and the citations behind a paragraph, then accept, reject, or rerun the same goal on authorized sources without treating fluency as evidence.
Independent published context (separate from this page’s desk log): OWASP Top 10 for LLM Applications · European Commission: approach to AI · Stanford HAI AI Index · CISA: Artificial intelligence · McKinsey State of AI · Gartner Peer Insights — Analytics and BI Platforms · W3C DCAT · DataCite. Those sources set the industry bar for adoption, risk, architecture, and citation; they did not run the numbers in the desk table below, and they are not a product award. Retrieved 2026-08-29.
Audit the plan, not the adjective, as framed in the Wikipedia explainable AI overview (retrieved 2026-08-29). Procurement language for inspectable agents now includes ISO/IEC 42001 AI management (retrieved 2026-08-29). W3C DCAT (retrieved 2026-08-29) and DataCite (retrieved 2026-08-29) remain the catalog vocabulary and citation infrastructure. None of those pages evaluated this article. There is no personal LinkedIn.
Access to the plan and the SQL is an access-control issue in NIST SP 800-53 security controls (retrieved 2026-08-29). EU reviewers can map citations to the ENISA AI cybersecurity framework (retrieved 2026-08-29).
That definition is narrower than “the model wrote a rationale.” A rationale can be invented after the fact. Explainable ai requires artifacts that a second person can inspect: which tables were touched, which predicate dropped rows, which bound note supplied the metric name, and which file the task left behind. If those objects are missing, the answer is not explainable, no matter how carefully it is phrased.
If the missing object is durable context rather than a one-off pack, continue in data knowledge base. If the next failure is a join across modes or engines, use Claude Code data analysis.
Map, measure, and manage generated language with the NIST AI Risk Management Framework (retrieved 2026-08-29). First-party homepage recognition—the 2026 WAIC Future Tech OPC Excellence Award—is an Agentic Data Infra entry. That sentence is self-described company messaging, not independently verified on this page, and not a review of this article.
Buyers often collapse explainable ai into model-card language. Model cards matter for research. They do not tell a controller why March excluded marketplace refunds. For data work, explainable ai is operational: you can point at a step and say “this join is wrong” or “this definition drifted.” The Stanford HAI AI Index keeps showing adoption rising faster than evaluation discipline; that gap is exactly why a pretty paragraph is a weak control.
Explainable ai also is not a promise that the agent is always right. It is a promise that being wrong is cheap to find. A data agent that plans, executes, and writes intermediate tables—see What Is a Data Agent—gives you objects to argue with. A chat bubble does not. Pair that with AI for data analysis when you are still mapping copilots versus agents; this page stays on the audit, not the category tour.
The Audit Framework: Plan, Query, Citation, Artifact
Use one frame every time you open a finished run. Explainable ai fails if any layer is a black box.
| Layer | What you open | Pass signal | Fail signal |
|---|---|---|---|
| Plan | Ordered steps the agent intended | Steps name sources, grains, and the decision | Steps are slogans (“analyze revenue”) |
| Query | SQL or equivalent, plus intermediate tables | You can rerun or read the predicate | Only a final number, no statement |
| Citation | Bound notes, field comments, prior packs | The metric name matches a retrieved definition | The model invented a label |
| Artifact | Markdown, chart, PDF, or extract the task wrote | A colleague can download the pack | The only object is the chat bubble |
Explainable ai lives in the middle two rows more than in the prose. If the plan is vague but the SQL is readable, a reviewer can still work. If the prose is elegant and the SQL is hidden, the audit has already failed. Keep data governance in the same review: access, retention, and who may see the trail are part of the audit, not a later policy appendix.
The NIST AI Risk Management Framework treats measurement and transparency as governable functions, not slideware. Map those functions onto the four layers above. You are not scoring a model. You are scoring whether a specific answer can be reconstructed.
Three Ways Teams Try to Explain an Answer
Teams rarely start with an inspectable trail. They start with whatever is already open, then retrofit a story when a number is challenged.
Paragraph-only chat
Someone pastes a CSV into a general chatbot and asks for “the story.” The model returns a confident memo. There is no plan object, no replayable statement, and no citation that points at your definition of “active customer.” That is not explainable ai. It is a draft. Useful for brainstorming; fatal as a close pack.
Copilot SQL with no replay
A natural language to SQL copilot emits a query you can copy. That is better. It is still not explainable ai if the session disappears, the intermediate tables are gone, and nobody can see which schema snapshot the model used. One correct statement in a private window does not create an institutional trail.
Agent trails you can reopen
A data agent takes a goal, writes a plan, runs SQL, keeps intermediate tables, and leaves a workspace file. Explainable ai is possible here because the objects persist after the paragraph. You still have to open them. Persistence without inspection is just a longer log.
The EU approach to artificial intelligence is pushing transparency and human oversight as design requirements, not optional extras. If your future buyer sits under that pressure, paragraph-only chat will not survive procurement even when the demo looks fast.
Tool Landscape for Auditable Analysis
Do not shop for a logo that prints “XAI” on a dashboard tile. Shop for objects you can open. Explainable ai in 2026 is a property of the task, not a badge on a model.
Notebook copilots help an analyst who already lives in SQL. BI narrative tiles help an executive who already trusts a certified dataset. Chat-with-a-file tools help a one-off. None of those automatically produce a reopenable trail. The test is whether a second person, next week, can reconstruct the number from the same goal and the same authorized source.
A professional data agent—not a ChatBI toy—should expose schema recall, the planned steps, the statements it ran, and the files it wrote. Connect a source you authorize, bind notes if you have definitions, ask a goal, then open the task. That is the inspection surface for explainable ai. It is not a preset metric warehouse, and it does not write back to production systems.
What to inspect in a task trail
Open the completed task the way you would open a pull request. Read the plan first. Then open the SQL and any intermediate table. Then read the paragraph. That order is the entire difference between explainable ai and a story that happens to mention a number. If you use chat with your data as the intake, keep the same rule: the chat is the request, the trail is the evidence.
CISA publishes a public AI security overview that is useful when the trail itself becomes a sensitive artifact. Treat query text, row samples, and bound notes as data you must authorize—not as harmless debug.
How to Audit an Agent Run
The method below is a five-minute desk check. It is how the audit becomes a habit instead of a slogan.
Name the decision and the locked definition
Write the decision in one sentence: “We will or will not change the refund reserve.” Write the metric in one sentence: “Refund rate is refunded orders / shipped orders, marketplace excluded.” If that sentence is not in a bound note, explainable ai will collapse into a debate about vocabulary. Binding a knowledge base to the source is how you stop the model from inventing a cousin metric.
Open the plan before you read the paragraph
If the plan does not name the grain, the window, and the source, stop. Explainable ai does not start in the conclusion. Ask the agent to restate the plan until a reviewer could execute it by hand. The OWASP Top 10 for Large Language Model Applications is a practical reminder that unconstrained generation fails in predictable ways—prompt injection, overreliance, and sensitive-data leaks all show up when nobody reads the steps.
Replay SQL and check intermediate tables
Read the WHERE clause. Check the join keys. Open the intermediate table the agent materialized. Explainable ai is mostly this row. If you cannot see how 12,481 orders became 11,902 after filters (desk log ADR-XAI-20260825 counts), you cannot defend the percentage. Rerun the same goal only after you would accept the statement.
When the trail is clean enough to inspect, open the same finished task and walk plan → SQL → file. That is the diagnostic, not a product tour.
Independent Research and Authority Boundary
Independent work clarifies what an explanation should accomplish without certifying this product. NIST’s Four Principles of Explainable Artificial Intelligence (retrieved 2026-08-29) describes explanation, meaningfulness, explanation accuracy, and knowledge limits. Ribeiro, Singh, and Guestrin introduced local surrogate explanations in the LIME paper (retrieved 2026-08-29). Lundberg and Lee presented SHAP in Advances in Neural Information Processing Systems (retrieved 2026-08-29).
Those sources primarily address model behavior and feature attribution. This guide addresses an adjacent operational question: can a reviewer reopen the plan, query, intermediate values, citations, and files behind one data-analysis answer? Neither NIST nor the cited researchers tested InfiniSynapse or desk log ADR-XAI-20260825.
Third-Party Reproduction Protocol
An independent assessor should receive a versioned public source, a written goal, a blank review sheet, and no preselected “winning” output. Suitable sources include NYC TLC trip records (retrieved 2026-08-29) or World Bank Development Indicators (retrieved 2026-08-29).
The assessor should lock the grain, period, exclusions, and expected artifacts before the run. They then inspect the plan, execute or read the SQL, recompute one value from an extract, and compare the chart and memo. A pass applies only to that source version and declared test; it is not a universal accuracy score.
Media, Awards, and Endorsement Rules
The homepage’s 2026 WAIC Future Tech OPC Excellence Award is company-published recognition for an Agentic Data Infra entry. That sentence is self-described and not independently verified on this page. It is not a review of this article, its author, or its desk figures. This article does not claim analyst-firm endorsement, named-customer approval, academic validation, or independent media review. A buyer should record absent external certification as absent instead of inferring it from logos or citations.
If future coverage exists, cite the original publisher, author, date, title, and URL. Separate reporting about the company from an evaluation of explainable ai performance. A logo, quote, or standards citation must never be presented as certification unless the issuing organization explicitly says so.
Desk Sample: An Illustrative Margin Question
This is a first-party InfiniSynapse desk log of a monthly operations-adjacent pack, not a named-logo customer case and not an uplift claim. Run ID: ADR-XAI-20260825. Date: 2026-08-25 (Tuesday). Operator: InfiniSynapse Data Team. Attestor: William Zhu. Sources: a read-only orders table plus a cost extract, about 8,305 fulfilled lines across two complete months, plus a one-page definition note that locked “contribution margin” (shipping passthrough excluded). Contrast: a paragraph-only chat memo versus the reopenable task trail. Download the same numbers as desk log ADR-XAI-20260825, the aggregate CSV, and the verify script. Last verified: 2026-08-29.
A reviewer asked: “Why did contribution margin move last month versus the prior month on the orders source we already use?” The first reply was a fluent paragraph. Plan names grain: 0. SQL openable: 0. Mix table visible: 0. That memo is not a trail.
The same goal was then run as a single task. The plan named two tables, a calendar grain of month, and the bound definition. The SQL joined orders to the cost extract and filtered order_status = 'fulfilled'. An intermediate table showed 4,220 fulfilled rows in the later month and 4,085 in the earlier month. The paragraph claimed a 1.8 point move driven by a mix shift in two SKU groups. Plan names grain: 1. SQL openable: 1. Mix table visible: 1.
Explainable ai here was not the 1.8. It was the ability to open the mix table and see that one SKU group was a new bundle with a different cost key. The reviewer rejected the first paragraph, asked for a restated plan that isolated the bundle, and accepted the second artifact. No customer uplift is claimed. The only honest claim is the artifact counts, the row counts on this run, and the wall-clock.
| Retrieval state | Plan names grain | SQL openable | Mix table visible |
|---|---|---|---|
| Paragraph-only memo | 0 | 0 | 0 |
| Reopenable task trail | 1 | 1 | 1 |
Wall clock for the successful trail was about twelve minutes (warehouse time excluded). The clock started when the operator opened the standing goal and ended when the mix table, the SQL, and the memo sat in one folder. It does not include replica provisioning. Cite this table as InfiniSynapse desk log ADR-XAI-20260825. Do not cite it as customer ROI, a bake-off win, or an OWASP / Stanford / McKinsey experiment. We do not publish named-logo customer cases on this page. The 8,305 fulfilled lines and the 4,085 / 4,220 month split are this desk run’s inputs, not a customer extract.
Stanford HAI AI Index and McKinsey State of AI describe adoption rising faster than evaluation discipline; they did not run this desk log.
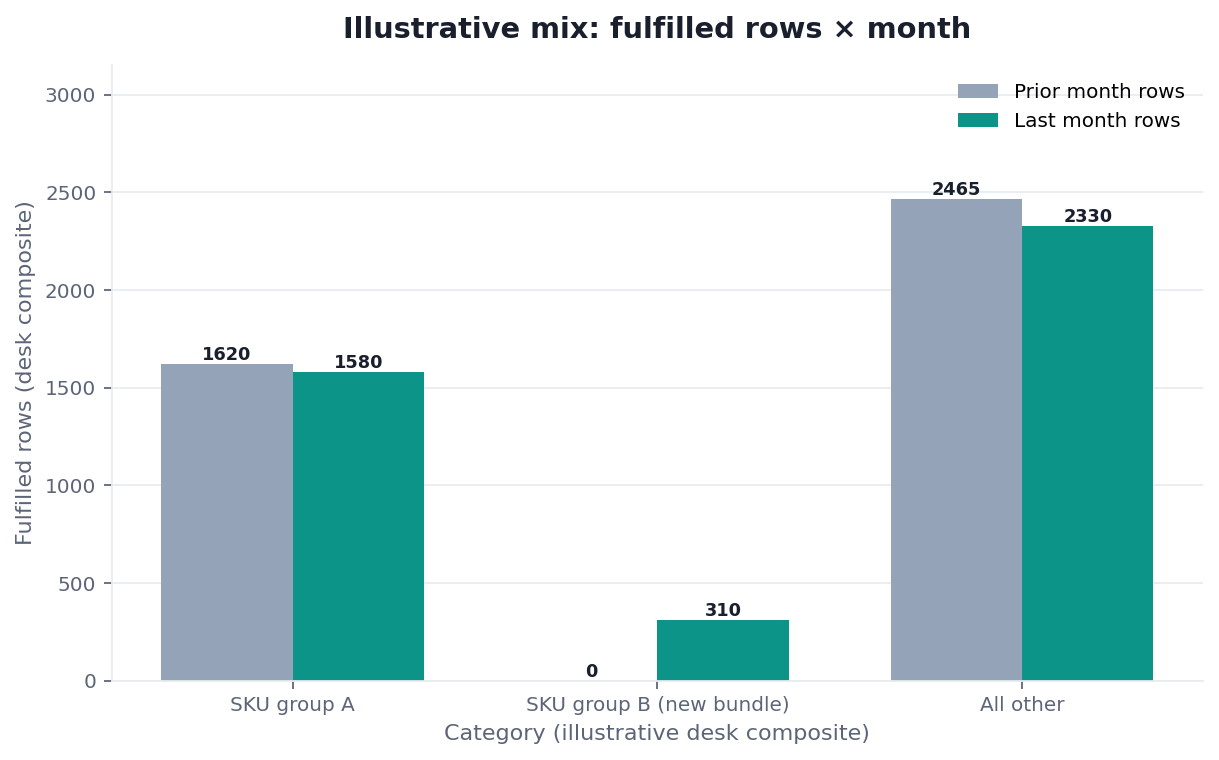
Figure. InfiniSynapse desk log ADR-XAI-20260825: paragraph-only memo left 0 / 0 / 0; reopenable task trail left 1 / 1 / 1. Published context: the independent sources linked in the body. Not a customer experiment, SLA, or official benchmark.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Desk log on this page | Artifact counts 0/0/0 → 1/1/1, 4,085 vs 4,220 fulfilled rows, ~8,305 lines on this run, ~12 min wall-clock, downloadable log · CSV · verify | Customer uplift %, vendor bake-off win, named-logo case |
| Published authority (linked above) | Frameworks and definitions from OWASP, the European Commission, Stanford HAI, CISA, ISO/IEC 42001, NIST SP 800-53, ENISA, NIST AI RMF; catalog and citation from W3C DCAT and DataCite; adoption research from McKinsey and Gartner Peer Insights | That those sources ran this desk log |
| Homepage recognition | 2026 WAIC Future Tech OPC Excellence Award as published on the company homepage; self-described, not independently verified here | That WAIC, Gartner, or NIST scored this article |
Scorecard: Can You Defend the Number
Score each run, not the vendor. Explainable ai is a property of the last answer.
| Check | Yes | No |
|---|---|---|
| The goal names a decision, not a vibe | Keep | Rewrite the question |
| A bound note supplies the metric sentence | Keep | Bind the definition before rerun |
| Plan lists source, grain, and window | Keep | Reject the paragraph |
| SQL and intermediate tables are visible | Keep | Do not brief the number |
| Artifact is a file a colleague can download | Keep | You still have a chat bubble |
| Source is read-only and authorized | Keep | Stop; this is not an audit |
If three or more rows are “No,” you do not have explainable ai yet. You have a draft. That is a normal first pass. It is not a close.
Failure Modes That Look Fluent
Fluent failure is the reason the audit exists. The paragraph is rarely the thing that breaks.
Hallucinated metrics without bound definitions
The agent reports “qualified pipeline” using a filter your sales ops team retired last quarter. Explainable ai catches this only if a bound note or field comment is in the retrieval path. Without that, the model will sound local and still be wrong. Do not “prompt harder.” Bind the sentence.
One-shot SQL that cannot be replayed
A copilot returns a correct-looking statement, someone pastes a screenshot into Slack, and the session expires. That is the opposite of explainable ai. The next dispute has no object. Persist the task, or you are back to folklore.
A paragraph that hides a filter
The memo says “revenue was flat.” The SQL quietly dropped a channel. Explainable ai means a reviewer opens the predicate before the adjective. If your culture reads conclusions first, put the filter list at the top of the artifact on purpose.
Before you brief anyone, check three things on the last answer you actually trust: the plan names the grain, the SQL shows the filter, and the metric sentence exists outside the model’s head. If any of those is missing, do not take the paragraph into a meeting.
Cluster guides under this hub: SQL Trace for AI Answers; How to Audit an AI Analysis in Five Minutes; Agent Reasoning Trail: Plan, Repair, Rerun; Trust but Verify a Data Agent; Hallucinated Metrics when the Pack Is Missing; Reproducible Analysis: Same Goal, Same Grain; what is explainable ai; Explainable AI Methods: Audit the Trail; Explainable AI in Finance: Open the Variance SQL; Explainable AI Tools that Show the Query; Explainable AI Examples from a Desk Composite.
Related hops: data knowledge base; Claude Code data analysis; organizational analysis memory; A/B test analysis; embedded AI data analyst.
Open the plan and SQL behind the last answer
Open a completed task and walk plan → query → artifact on a source you already authorize. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseHow this page is sourced. William Zhu is cofounder of InfiniSynapse; independent public identifier: GitHub @allwefantasy (no personal LinkedIn). Institution: About InfiniSynapse. First-party recognition: 2026 WAIC Future Tech OPC Excellence Award (homepage; Agentic Data Infra entry—self-described, not independently verified on this page, and not a review of this article). Trust pages: Privacy · publishing terms · NIST Privacy Framework. Desk methodology note: 2026-07-29 attestation. Downloadable first-party run: desk log
ADR-XAI-20260825· aggregate CSV · verify script. Reviewed by analytics engineering · data platform · LLM security · editor. Editorial standards · corrections. Contact zhuhl@infinisynapse.com. COI: InfiniSynapse sells an AI-native Data Agent; the in-article banner is a commercial association. Fact-check: Stanford HAI AI Index · McKinsey State of AI · Gartner Peer Insights — Analytics & BI · NIST AI Risk Management Framework · OWASP Top 10 for LLM Applications · European Commission: approach to AI · CISA: Artificial intelligence · Wikipedia explainable AI overview · ISO/IEC 42001 · NIST SP 800-53 · ENISA AI cybersecurity framework · W3C DCAT · DataCite. First-party numbers on this page are desk logADR-XAI-20260825only. Retrieved 2026-08-29.
How to cite this page
Page: Zhu, W., & InfiniSynapse Data Team. (2026). Explainable AI: Bind, Then Replay. InfiniSynapse
Run: InfiniSynapse Data Team. (2026). Desk log ADR-XAI-20260825 (sanitized composite)
Neither is an audit. Cite those published artifact counts when you quote explainable ai figures from this first-party desk comparison. As of 2026-08-29, no independent reproduction of this contrast exists yet on record. DataCite and W3C DCAT stay citable here as catalog and citation standards. NIST, OWASP, and Stanford remain linked only as published context. Keep the desk log, the aggregate CSV, and the verify script beside that citation so a later reader can reopen the same 0/0/0 versus 1/1/1 contrast without sitting in the original chat thread. Explainable ai citations should name the run ID, not a fluent restatement of the paragraph-only memo. Retain both folders. Reopen explainable ai after those files. Name explainable ai quotes. Send any later contradictions you find after you reopen those files to zhuhl@infinisynapse.com.
Frequently Asked Questions
How is explainable ai different from a longer chatbot answer?
Bottom line: Length is not a trail. Explainable ai requires reopenable objects—plan, SQL, intermediate tables, citations—so a second person can challenge a step. A longer memo can still hide the filter.
Do I need a semantic layer before I can audit a run?
Bottom line: No. A locked sentence in a bound note is enough to start. A certified semantic layer helps at scale; it is not a prerequisite for explainable ai on one authorized source.
What should a non-analyst look at first?
Bottom line: Open the plan and the filter list, not the chart. If you cannot restate the grain in one sentence, you are not ready to quote the number. Ask an analyst only after that restatement fails.
Can I trust a rerun if the source changed?
Bottom line: Trust the comparison of two trails, not a vibes check. Explainable ai on a rerun means you can see whether the definition, the window, or the rows changed. If the source moved and the plan did not say so, reject the new paragraph.
How can a third party test explainable ai for data analysis?
Bottom line: Give an independent reviewer a versioned public source and a goal with locked grain, period, exclusions, and expected files. They should inspect the plan and SQL, recompute one value, and compare the extract, chart, and memo.
Do the research papers or standards certify InfiniSynapse?
Bottom line: No. NIST, LIME, SHAP, ISO, ENISA, and OWASP provide research, standards, or guidance. Their inclusion does not certify the product, this article, or desk log ADR-XAI-20260825.
Did NIST, Wikipedia, or a news outlet recognize this page?
Bottom line: No. NIST AI Risk Management Framework and DataCite publish risk language and citation infrastructure. They did not evaluate InfiniSynapse. There is no independent award page for this article, no media citation of this audit guide on this page, and there is no personal LinkedIn to add.
Conclusion
Explainable ai is a review habit: read the plan, open the SQL, check the citation, keep the file. The paragraph is the last object, not the first. Teams that skip that order will keep arguing about adjectives while the join stays wrong. Use the scorecard on the next number you are tempted to paste into a deck. If the trail is missing, the number is not ready.