Generate Dashboard from Natural Language: Inspect, Rerun
By William Zhu (independent public engineering profile: GitHub @allwefantasy; no personal LinkedIn) & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-08-29 · Last verified: 2026-08-29 · Next review: 2026-11-29 · About · Editorial standards · Privacy · Publishing terms · Corrections
Table of Contents
- TL;DR
- What it means to generate dashboard from natural language
- A goal-to-board framework
- How generated language differs from NL2SQL
- Tool landscape for natural-language boards
- Implementation steps for the meeting sentence
- Desk sample: two prompts, two boards (InfiniSynapse desk log)
- Selection scorecard
- Failure modes in the prompt
- Frequently Asked Questions
- Conclusion
TL;DR
We evaluate these patterns at the InfiniSynapse desk on sanitized composites; first-party figures on this page are desk log AIDB-NL-SENTENCE-20260822, not customer uplifts and not a third-party bake-off.
Direct answer: To generate dashboard from natural language, a system may start from chart intent, an analytic question, fields, constraints, or decision context, then produce SQL, semantic queries, DAX, LookML, transforms, filters, or visual specifications. This page uses a decision sentence as an operational rubric, not the only valid method.
Download evidence: desk log · aggregate CSV · verify script. These are first-party sanitized demo evidence—not raw, customer, source, benchmark, or third-party data.
What you'll learn:
- Why natural-language board requests fail when the prompt is a widget list
- How a decision sentence differs from a SELECT you typed in English
- A framework that turns one invite sentence into a pack
- Desk log
AIDB-NL-SENTENCE-20260822, of a shopping-list prompt versus a named-goal prompt - Scorecard rows and three prompt failures that still look like a board
Research supports bounded tasks. NL4DV studies natural-language visualization specification; Data Formulator studies mixed-initiative transformation and visualization; nvBench is an NL-to-visualization benchmark; ChartQA evaluates chart question answering; and Vega-Lite defines a visualization grammar. None validates this desk run.
Product scope varies: Power BI Copilot, Tableau Agent, Looker conversational analytics, Looker semantic modeling, and Snowflake Cortex Analyst document their own capabilities and prerequisites. None endorses InfiniSynapse. Retrieved 2026-08-29.
Teams that generate dashboard from natural language should evaluate the actual query, semantic, and visual specification path.
Author qualifications and accountability
William Zhu is an InfiniSynapse cofounder. GitHub @allwefantasy, auto-coder, byzer-llm, BYZER-RETRIEVAL, and the InfiniSynapse organization verify public project activity—not education, BI certification, customers, or independent evaluation.
This page is first-party. The authors sell the workflow. It is not an independent review. 2026 WAIC Future Tech OPC Excellence Award (homepage; not a review). 2026-07-29 attestation.
Internal terms this page uses: a decision sentence is an invite-quality goal. A shopping list is a mall directory of chart types. A pack is the files you attach. To generate dashboard from natural language is how that pack is commissioned; it is not a SELECT you typed in English.
An AI-native dashboard is the object you keep. The sentence is how you commission it. If you generate dashboard from natural language as “bar, line, pie, and a map,” you asked for a catalog. If you generate dashboard from natural language as “Thursday ops: fill rate versus promise, five SKUs driving the miss, replica we already connected,” you asked for a job.
Chat with your data can start the conversation. It cannot be the archive. When you generate dashboard from natural language, the workspace must hold the pack. The thread is a window.
Decision goal versus shopping list
Weak: “revenue, region, and a funnel.” Strong: “for Friday’s demand review, show promised versus shipped on the last fourteen days, cut by node, and list the five SKUs that created the gap.” The second sentence names audience, metric, window, and cut. A generator can plan that. The first sentence is a mall directory.
Write the goal the way you write a meeting invite. If you would not put the sentence on a calendar, do not generate dashboard from natural language from it. The AI dashboard generator hub uses the same test: the question is the product trigger, not a list of glyphs.
A shopping list produces tiles that look busy and still cannot decide.
Why chart lists fail
Chart lists hide the decision and the source. People generate dashboard from natural language, attach “use the data,” and then argue about which extract the model guessed. Name the connection. If two sources are required, say so. You do not need a warehouse project first.
A goal-to-board framework
| Stage | Input | Output you keep |
|---|---|---|
| Sentence | Audience, decision, window, cut | One invite-quality goal |
| Sources | Existing DBs or files | Named connections |
| Plan | Agent steps | Inspectable timeline |
| Board | Charts + tables | Workspace preview |
| Pack | Markdown, PDF, HTML, extracts | Files you can attach |
A sentence that skips audience will generate a board for nobody. A sentence that skips the cut will generate a board for everyone and satisfy no one.
The sentence the agent can plan
Template, not a script: “[Meeting] on [day] must decide [decision]. Use [source]. Window [dates]. Cut by [dimension]. Show the [N] drivers of the miss.” That is enough to generate dashboard from natural language without becoming a SQL novel.
Do not paste a schema dump into the sentence. Bind a knowledge base if “margin” is contested. People generate dashboard from natural language, then watch the model pick the fluent definition. If the next failure is a join across two engines, use ClickHouse analytics when that engine is the home.
How generated language differs from NL2SQL
Natural language to SQL asks for a statement. To generate dashboard from natural language is to ask for a pack. The SQL may exist inside the task. It is not the deliverable. If the only output is a query in a bubble, you drafted a SELECT.
Natural-language generation may use SQL, a semantic query, DAX, LookML, transforms, filters, or a visual grammar. This first-party demo used read-only access and no writeback. High-reuse metrics may still require a warehouse or semantic layer.
A semantic layer still helps when you have one. Bind it or bind a memo. Then generate dashboard from natural language against the bound source, not against a nickname someone used in Slack.
Goal language is not a SELECT
Known SQL or chart constraints can be valid review inputs. The important distinction is whether the request, definitions, generated operations, and visual output remain inspectable.
Goal language names the decision. SELECT language names the grain. You do not start with the SELECT if the meeting still cannot say what it must decide.
The operational dashboard vs BI split applies here too. Certified tiles can stay in BI. When you use this method, you are usually asking for the weekly ops pack, not a replacement for the close.
Tool landscape for natural-language boards
Chat that only talks. You ask for a board and receive a paragraph plus a picture. Score it as a demo.
BI copilots. They draft tiles inside a model you already paid to build. Good when the question is already in the model. Weak when Tuesday’s exception is not.
Agent-generated packs. Connect existing sources, write the meeting sentence, download the files, rerun next week. The educational path: connect → ask for next week’s board in one sentence → open charts in the task → download. That is how you generate dashboard from natural language without a designer weekend.
Chat that only talks
A fluent paragraph can hide a missing join. If you generate dashboard from natural language and cannot open the query, you have a story. AI for data analysis matured past “talk to the table.” The board still has to leave files.
Agents that leave a pack
This is the path the hub describes. The audience is a recurring meeting. The source is already there. The success test is “we reused the sentence and the definitions matched.” Pretty is optional. Traceable is not.
You can generate dashboard from natural language across two sources in one task. Orders in Postgres, notes in a file. You do not owe a lakehouse to the meeting. Inspect the join. Then download.
Implementation steps for the meeting sentence
- Connect one authorized source—or two, if the meeting truly needs both.
- Bind a knowledge base if a word is contested.
- Write the invite-quality sentence. Do not write a chart list.
- Generate dashboard from natural language with that sentence. Open the plan.
- Download the files. Attach those files, not a screenshot.
- Next cycle, reuse the sentence. Compare artifacts.
These six steps are the whole proof. You can complete the educational diagnosis at step 3: write the invite sentence before you run anything.
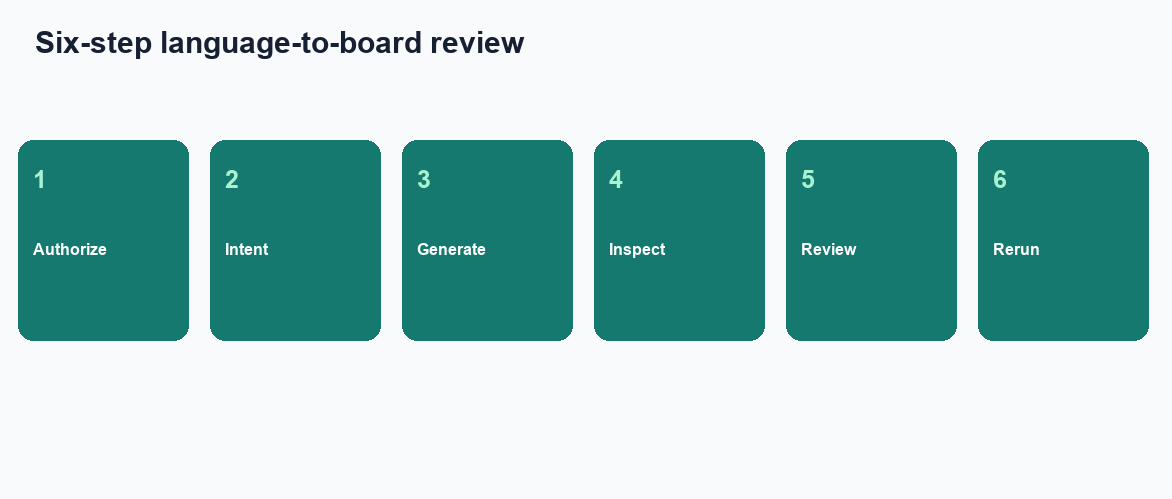
Figure. Educational four-step sequence the desk uses to tell a shopping-list prompt from a named-goal prompt. Expected result after step 6: the same sentence reruns, each featured number opens to a query, and a teammate can attach the files. Not a product screenshot or a customer SLA.
Name audience, window, and cut
Audience tells the agent who must decide. Window tells it what “this week” means. Cut tells it where to split. If you generate dashboard from natural language without those three, the board will be pretty and late. Add the source name so the agent does not guess an extract.
If you cannot write the sentence, you are still in exploratory data analysis. Stay there until the question stabilizes. Then generate dashboard from natural language once, not twelve times with different adjectives.
Freeze the sentence for next week
The second run is the product. People like the preview, then rewrite the prompt because they thought of a new adjective. Definitions drift. Freeze the text. Edit it only when the meeting changes.
If last week’s board is the object you want again, replace the weekly dashboard refresh with a rerun of the same sentence. That is the operating cadence. New adjectives are a new commission.
Desk sample: two prompts, two boards (InfiniSynapse desk log)
This is a first-party InfiniSynapse desk log of a named-goal prompt, not a named-logo customer case and not an uplift claim. Run ID: AIDB-NL-SENTENCE-20260822. Date: 2026-08-22 (Saturday). Operator: InfiniSynapse Data Team. Source: a read-only Postgres replica the desk is authorized to read. Goal contrast: “sales charts” versus a Friday demand-review sentence. Download the same numbers as desk log AIDB-NL-SENTENCE-20260822.
The same sanitized replica received two prompts. Prompt A: “generate dashboard from natural language with sales charts.” The task returned six tiles. Nobody could say which figure the Friday review needed. Prompt B named the Friday demand review, the window, the cut, and the replica. The task returned three charts and a Markdown exception list. Finance opened the filter. The following Friday the same sentence reran.
| Retrieval state | Tiles returned | Named Friday decision | Exception list |
|---|---|---|---|
| Sales-charts prompt | 6 | 0 | 0 |
| Named-goal prompt | 3 | 1 | 1 |
Wall clock for the successful run was about twenty-one minutes (warehouse time excluded). Cite this table as InfiniSynapse desk log AIDB-NL-SENTENCE-20260822. Do not cite it as customer ROI, a 40% shorter meeting, a bake-off win, or an Arrow / ISO / Gartner experiment. We do not publish named-logo customer cases on this page. The only honest claim is the artifact counts and the wall-clock on this run.
We are not claiming Prompt B made the meeting shorter. We are claiming that when you generate dashboard from natural language with a decision sentence, the board and the query live in the same folder.
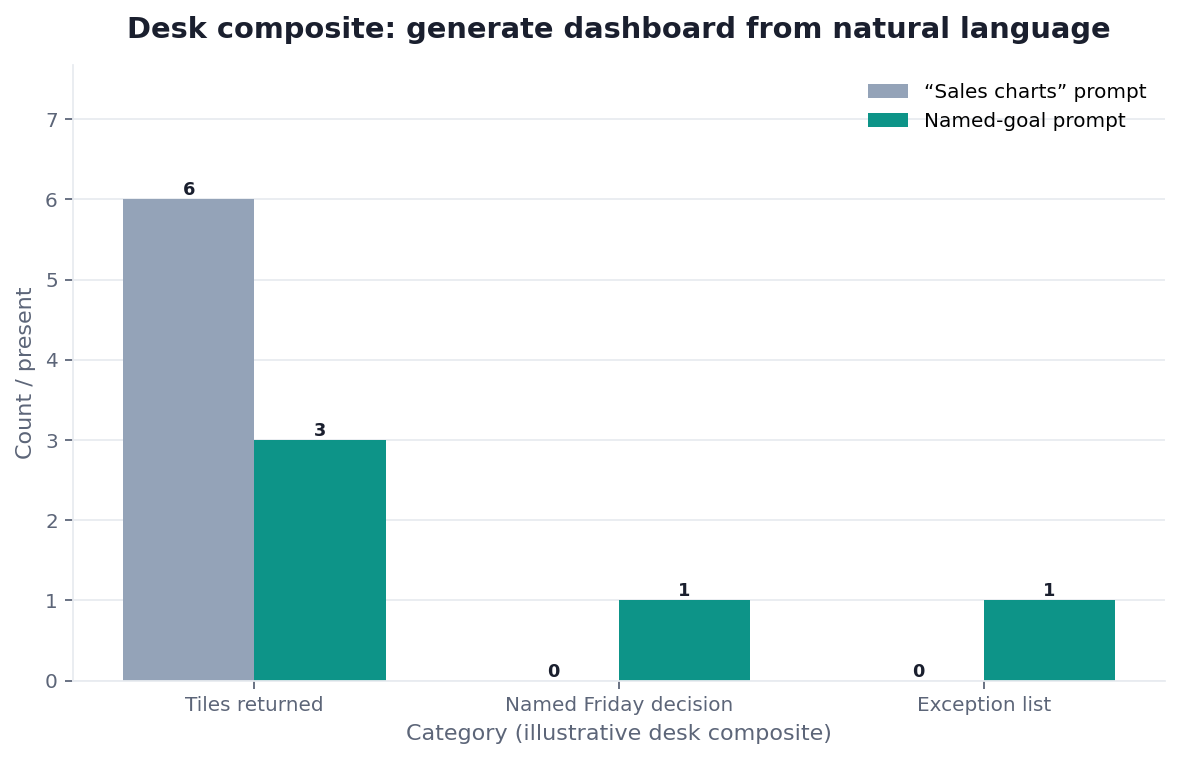
Figure. InfiniSynapse desk log AIDB-NL-SENTENCE-20260822: the shopping-list prompt left 6 / 0 / 0; the named-goal prompt left 3 / 1 / 1. Published context: the independent sources linked in the body. Not a customer experiment, SLA, or official benchmark.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Desk log on this page | Artifact counts 6/0/0 → 3/1/1, ~21 min wall-clock, run ID, downloadable log | Customer uplift %, vendor bake-off win, named-logo case |
| Published authority (linked above) | Arrow, Spark, Kafka, ISO 27001, ISO 9001 | That those sources ran this desk log |
| Homepage recognition | 2026 WAIC Future Tech OPC Excellence Award as published on the company homepage | That WAIC, ISO, or Gartner scored this article |
Evidence boundaries and external validation status
AIDB-NL-SENTENCE-20260822 is a first-party sanitized composite/demo—not raw, customer, source, benchmark, or third-party data. As of 2026-08-29, no independent third party, media outlet, or customer had reproduced it.
Replication should disclose tool, model, version, configuration, prompts; source schema, snapshot, access; metric, grain, join, filter, timezone; decision, audience, window, chart constraints; SQL, semantic query, transform, visual specification; run IDs, status, errors, timestamps; chart, data, artifact hashes; shopping-list baseline; all failures; review and accessibility protocol; wall clock; and conflicts of interest. PROV-O, WCAG 2.2, ACM Artifact Review, NIST AI RMF, and OWASP GenAI guide controls; none tested this run.
Selection scorecard
| Criterion | Weak | Strong |
|---|---|---|
| Sentence | “Make charts” | Named meeting, decision, cut |
| Trace | Image only | Query behind each figure |
| Sources | “Use the data” | Named authorized connections |
| Refresh | New adjectives weekly | Frozen sentence, rerun |
| Pack | Chat bubble | Downloaded artifacts |
| Shape | Chart shopping list | Figures follow the decision |
If a vendor lets you generate dashboard from natural language but will not download, score it as a demo. If it downloads but hides SQL, score it as a poster. If every prompt yields the same six tiles, score it as a catalog.
Failure modes in the prompt
Vague “make a dashboard”
People write five words and then blame the model for twelve tiles. The sentence was the failure. Write the invite. If you cannot, you are not ready to generate dashboard from natural language.
Metric names with no owner
“Show margin” will use whichever fluent definition the model prefers. Bind the memo, or name the owner in the sentence. Unowned metrics become arguments after the meeting, not during the task.
A new sentence every Sunday
Rewriting the prompt feels like improvement. It is drift. Freeze the text you used last week. Rerun it. Change it only when the meeting’s decision changes.
Before you send any board, check that the files are in the workspace, that each featured number opens to a query, and that the sources are ones you authorized. That inspection is the diagnosis.
| Live guide | Open it when |
|---|---|
| AI dashboard generator | you need the question-to-board path |
| AI-native dashboard | the fight is artifact versus tile catalog |
| Operational dashboard vs BI | the board is an ops pack, not a publication |
| self-service analytics | the blocker is still “who is allowed to ask” |
| data visualization | the question is how to show the grain |
| what is a data agent | the missing object is the agent, not the sentence |
| Download an AI Dashboard from the Workspace | The board you can download is the board you can audit |
| Dashboard from Multiple Databases | One question can read more than one authorized source |
Ask for next week’s board in one sentence
Connect one authorized source, type the meeting goal you already use, and download the charts from the task workspace. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseSourcing and accountability. Research and product documents support scoped claims only; none evaluated this page. COI: InfiniSynapse sells the first-party workflow.
How to cite this page
Page: Zhu, W., & InfiniSynapse Data Team. (2026). Decision sentence boards: inspect, then rerun. InfiniSynapse
Run: InfiniSynapse Data Team. (2026). Desk log AIDB-NL-SENTENCE-20260822 (sanitized composite)
Neither is an audit. Cite those artifact counts on this desk run. No independent reproduction exists. Send contradictions to zhuhl@infinisynapse.com.
Frequently Asked Questions
Can I generate dashboard from natural language without SQL skills?
Bottom line: Yes. You still need a decision sentence, authorized sources, and the discipline to open the plan. The agent writes the SQL. You judge whether the figure serves the meeting.
Is a chart shopping list a valid prompt?
Bottom line: No. If you generate dashboard from natural language as a list of chart types, you asked for a catalog. Name the decision, the window, and the cut instead.
Can I generate dashboard from natural language across two databases?
Bottom line: Yes, if both are connected and authorized. You do not need a warehouse first. You do need to inspect the join. A hidden join is not ready for a decision.
What do I freeze for next week?
Bottom line: The sentence and the bound definitions. If you generate dashboard from natural language from a new paragraph every Sunday, you are commissioning a new board, not refreshing one.
Will this write tiles into my BI tool?
Bottom line: No. When you generate dashboard from natural language, the pack lands in the task workspace. It does not publish into Tableau or Power BI and does not write back to production.
Do Arrow, ISO, or Gartner certify this sentence?
Bottom line: No. Apache Arrow documentation, ISO/IEC 27001, and Gartner Peer Insights describe engines and management-system frames. They do not run the desk table on this page.
Are the object counts a third-party benchmark?
Bottom line: No. The 6 / 0 / 0 versus 3 / 1 / 1 counts are first-party desk log AIDB-NL-SENTENCE-20260822. Generate dashboard from natural language treats those counts as a shopping-list-versus-goal test, not an SLA.
Related guides: dashboard tools · dashboard creator · AI dashboard generator · dashboard maker · ai powered dashboards · data knowledge base · knowledge base vs semantic layer
Conclusion
To generate dashboard from natural language, write the meeting invite, not a mall directory of charts. Run that sentence on sources you already have, download the files, and refuse figures that cannot open a query. When you want to run that check, open InfiniSynapse and ask for next week’s board in the same sentence you will put on the calendar.