AI Native Data Platform: 5 Layers to Require
An ai native data platform is software where agents run the analysis: they bind enterprise sources, keep an audit trail, and reuse approved memory. A copilot on an existing dashboard is a different product. Use the five layers below before that copilot enters a shortlist.
By William Zhu & the InfiniSynapse Data Team · Published: 2026-06-09 · Last updated: 2026-09-23 · About: Editorial standards · About / team
Author credentials: William Zhu — InfiniSynapse cofounder; public engineering profile GitHub @allwefantasy. Desk contact: zhuhl@infinisynapse.com. Reviewers: data platform · analytics engineering.
Disclosure: We build InfiniSynapse and sell an ai native data platform. This buyer's guide reflects architecture patterns and evaluation criteria from production deployments—InfiniSynapse appears as one reference implementation, not the only option. Scoring examples are first-party self-assessment; re-run the checklist on your own schema.
Third-party anchors: NIST AI RMF, NIST SP 800-53, ISO/IEC 42001, OWASP Top 10 for LLM Applications, Gartner Peer Insights — Analytics & BI, G2 Business Intelligence, Databricks Genie / data-agent post. Peer-review archive: editorial standards.
Table of Contents
- TL;DR
- Definition
- Platform Architecture: Five Layers
- The Five Pillars — Platform Requirements
- AI-Native vs AI-Enabled vs Traditional BI
- Migration Path: AI-Enabled → AI-Native
- Buying Criteria: 12-Question Checklist
- Market Landscape (Neutral Comparison)
- Reference Implementation: InfiniSynapse
- Deployment Patterns
- FAQ
- Who wrote this
- References
- Conclusion
TL;DR
Canonical answer: An ai native data platform is software architected from day one around autonomous Data Agents—not a BI dashboard with an AI copilot bolted on. It connects to enterprise data sources, runs goal-driven multi-step analysis with full audit trails, distills completed work into reusable memory, and exposes the same agent capability through chat, web, and API. The 2026 buyer's question is not "does it have AI?" but "was the workflow designed for agents, or retrofitted?"
Who this is for: heads of data, analytics platform leads, CTOs, and procurement teams evaluating whether an ai native data platform belongs in their 2026 analytics infrastructure budget.
What you'll learn: the five layers, the pass/fail pillars, a 12-question checklist, and how to tell a copilot add-on from a platform that remembers definitions next month.
Conflict of interest: InfiniSynapse publishes this guide and sells related software. Scoring examples below are first-party self-assessment—re-run the checklist on your own schema.
Related: Data Agent Manifesto · What Is a Data Agent? · Best AI Tools for Data Analysis. The warehouse and pipeline layer those agents query is mapped in the data engineering hub.
Account for prompt-injection and exfiltration risks in the OWASP Top 10 for LLM Applications. Align connector design with the NIST AI Risk Management Framework.
Independent buyer directories (not our scores)
Buyer reviews live on Gartner Peer Insights — Analytics and Business Intelligence Platforms and G2 Business Intelligence. Use them to calibrate claims. This page does not invent star ratings. Run your own POC.
Definition
Key Definition: An ai native data platform is the system where Data Agents are the primary workflow. They connect structured and unstructured sources, run multi-step analysis, keep an audit trail and approved memory, and expose the same capability in chat, web, API, and MCP. Traditional BI optimizes dashboard display and may add a copilot on top.
Three terms to disambiguate:
| Term | What it optimizes for |
|---|---|
| Traditional BI platform | Displaying pre-built dashboards |
| AI-enabled analytics | Copilot accelerates analyst steps inside existing BI |
| AI native data platform | Agent executes analysis; human validates and decides |
Data Agent (definition): a system that takes a goal, plans, runs tools, and returns evidence a human can audit. See What Is a Data Agent?.
For the workflow paradigm, see AI-native data analysis. When evaluating an ai native data platform, ask: was it designed so agents execute analysis, or so humans execute analysis with AI suggestions? That distinction—not connector count—separates native from enabled.
Platform Architecture: Five Layers
Layer 1 — Connector & Asset Fabric
Bind databases (MySQL, Postgres, Snowflake, BigQuery), document stores (MongoDB), files (XLSX, CSV, Parquet), and knowledge sources (docs, dictionaries, prior analyses). An ai native data platform must discover those assets. Do not ask the user to paste the schema every session. Access reviews should map roles and retention to controls such as NIST SP 800-53.
Layer 2 — Agent Runtime (Data Agent)
Orchestration loop: plan → execute tool calls → validate → self-correct → summarize. Not single-turn chat. This is the heart of an ai native data platform—without a runtime, “AI” is only a UI feature.
Layer 3 — Knowledge Layer
Retrieve business definitions, prior analyses, and metric contracts per query, so agents do not depend on pasted schema dumps. Split two stores. A context layer holds metric definitions, join rules, and approved SQL that every agent reads at runtime. Memory cards are the distilled output of a finished task, and they need a human approval step. Session chat is neither store.
Layer 4 — Audit & Governance
Task timeline with every SQL, dataset, and chart inspectable. Policy belongs on the query, not only on the login: row filters and role checks should apply when the agent runs SQL, and the timeline should tie each published number to that query. Approval flows for memory cards (DRAFT → human approved) stay exportable for finance. AI management programs may also map to ISO/IEC 42001.
Layer 5 — Multi-Entry Access
Same agent capability via chat (light queries), web app (deep tasks), and API (embedding in Code Agent workflows, kanban systems, or custom agents). MCP is the entry an external agent uses to reach an ai native data platform. It should inherit the same connector permissions. A token pasted into a prompt is not an entry point. Entry-point parity is a platform requirement.
[Connectors] → [Agent Runtime] ↔ [Knowledge/RAG]
                    ↓
            [Audit Timeline] → [Memory Store]
                    ↓
            [Chat | Web App | API]
The Five Pillars — Platform Requirements
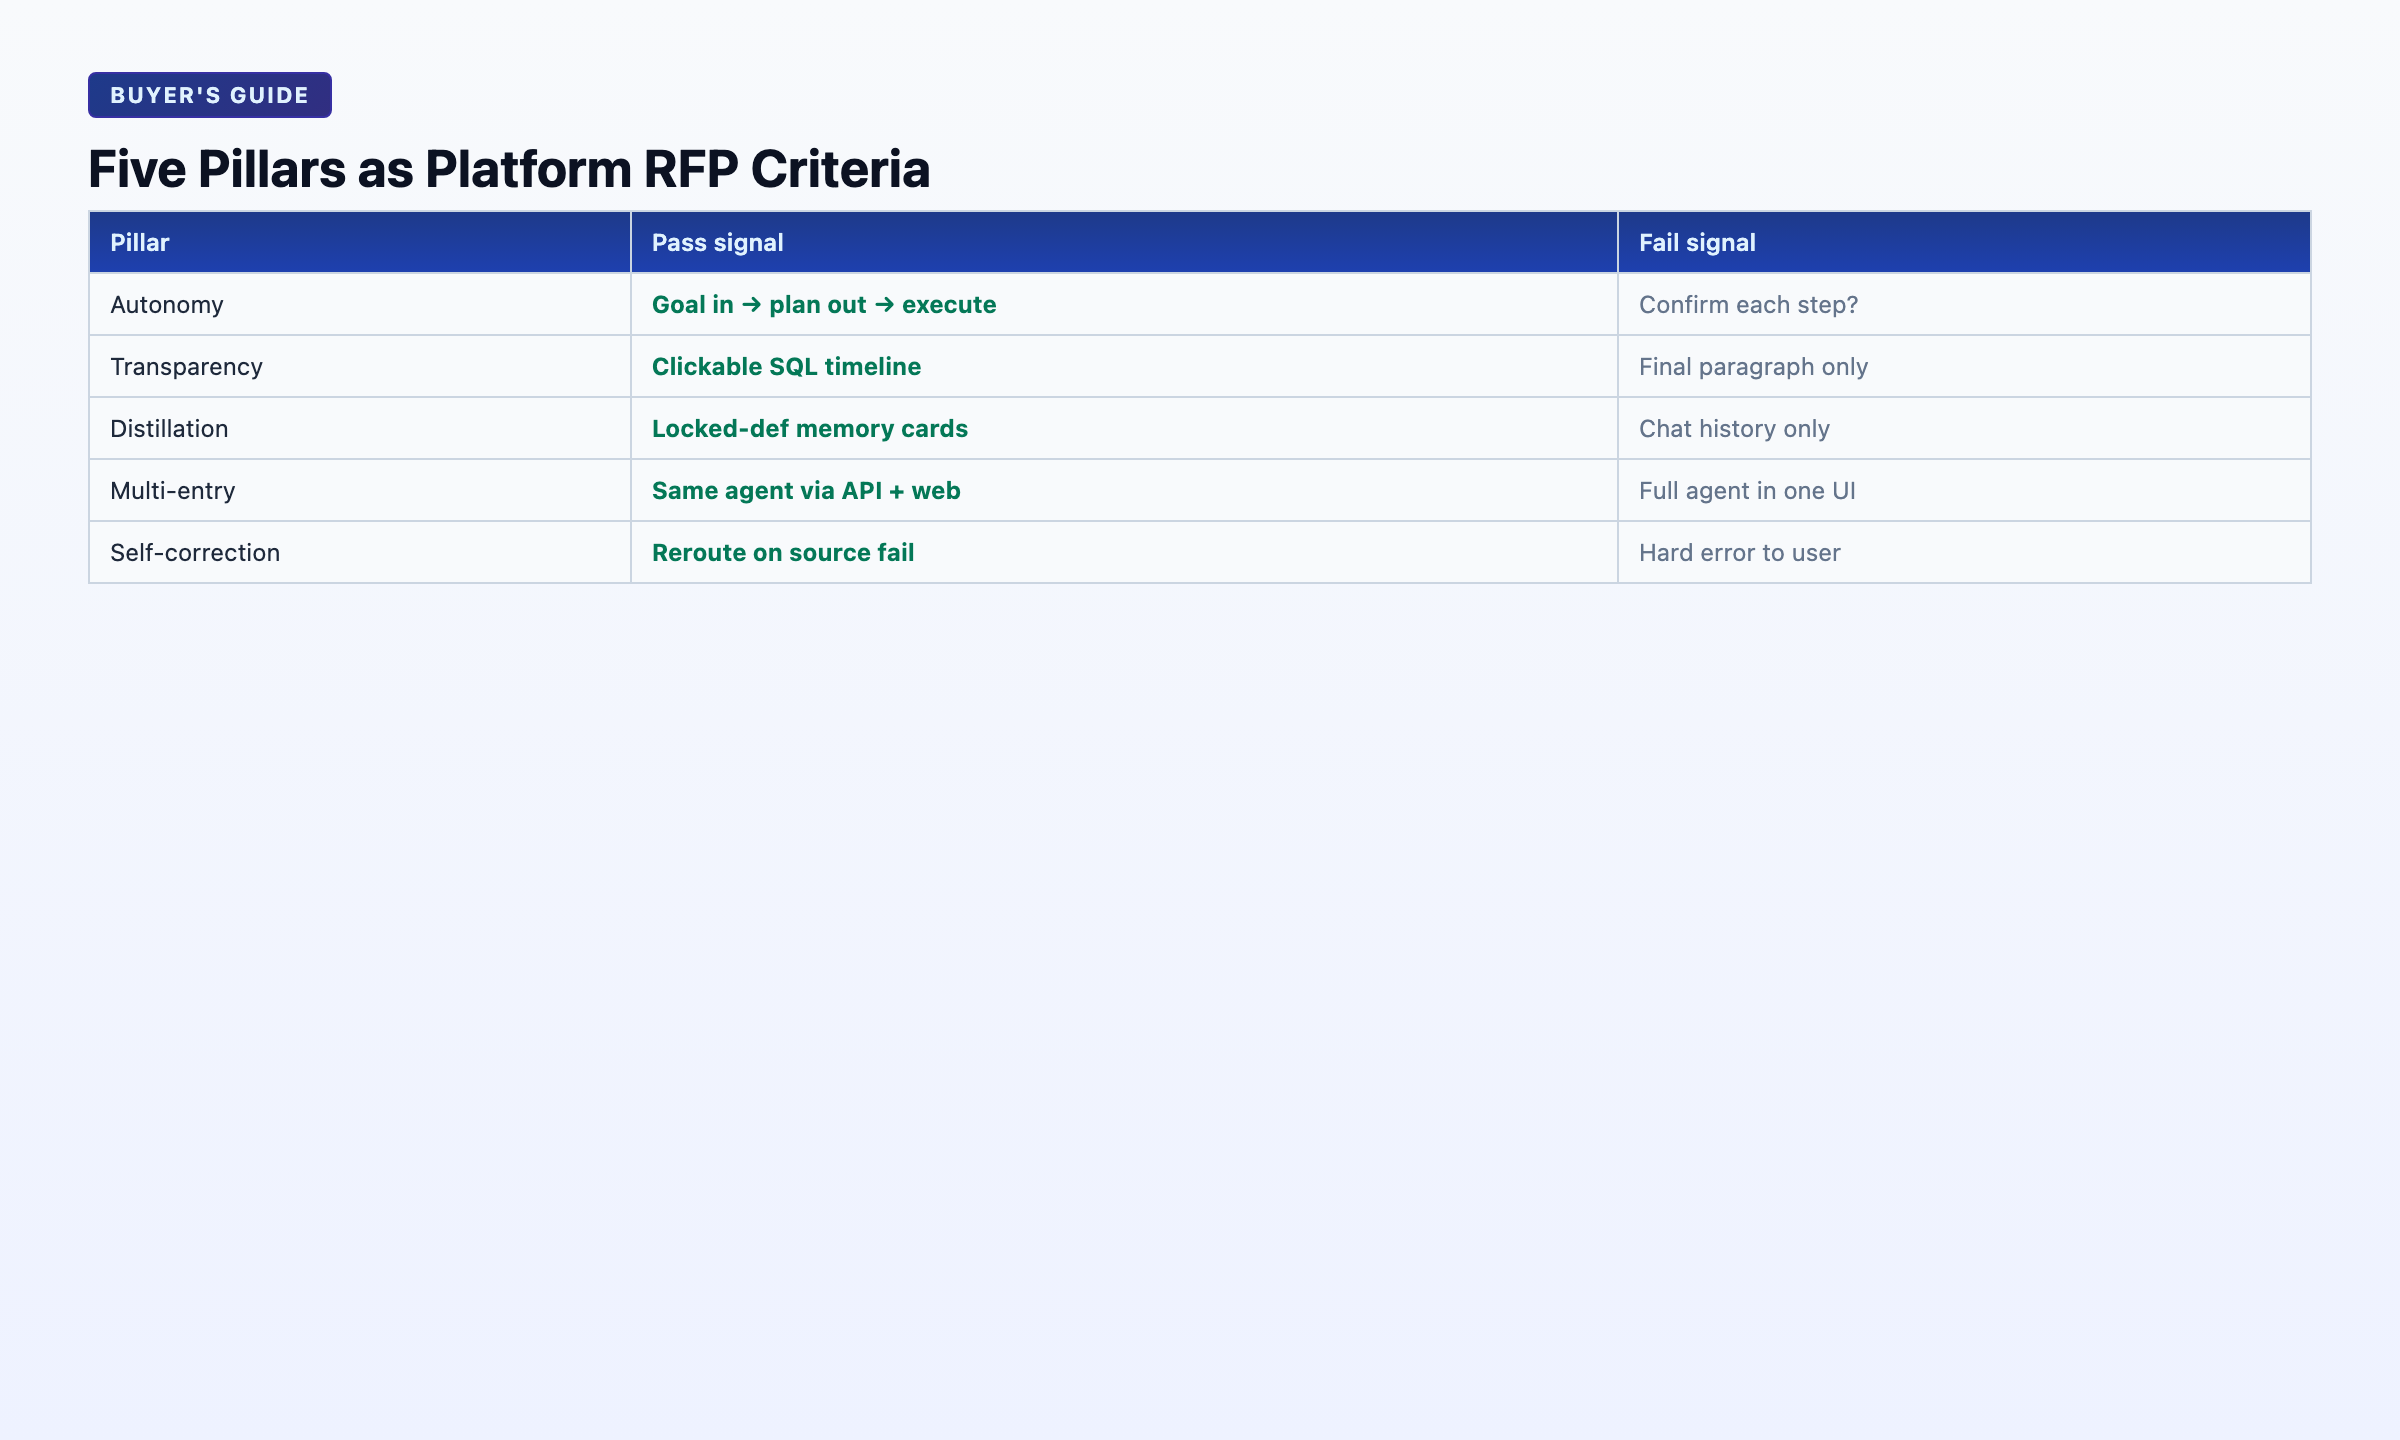
Use these as RFP criteria for any ai native data platform. A product failing more than one pillar is usually AI-enabled with marketing.
| Pillar | Platform requirement | Fail signal |
|---|---|---|
| 1. Autonomy | Goal in → phased plan out → execution without per-step prompting | “Confirm each step?” dialogs |
| 2. Process transparency | Clickable audit timeline for every task | Final answer only |
| 3. Knowledge distillation | Memory cards with locked definitions, human approval | Session-only history |
| 4. Multi-entry parity | Identical agent via chat, web, API | Full agent in one UI only |
| 5. Self-correction | Reroute on source failure, empty join, timeout | Hard fail to user |
These pillars are defined in the Data Agent Manifesto. Grain, dimensions, and conformed metrics still matter when reviewers check generated SQL.
AI-Native vs AI-Enabled vs Traditional BI
| Dimension | Traditional BI | AI-enabled | AI-native platform |
|---|---|---|---|
| Primary artifact | Dashboard | Copilot suggestion | Completed analysis + audit |
| User mode | Click filters | Prompt per step | Submit goal |
| Memory | Saved dashboards | Chat history | Distilled memory cards |
| Failure handling | Broken chart | Error to user | Agent reroutes |
| Best for | Known KPIs | Analyst acceleration | Recurring + multi-source analysis |
| 2026 budget line | Maintenance | Pilot copilot | Agent infrastructure |
When traditional BI wins: Fixed executive dashboards, governed semantic layers, known metrics displayed daily.
When a vendor says AI-ready: they usually mean governed retrieval for agents on an ai native data platform shortlist. Score that claim with the five pillars. The adjective does not decide. The longer comparison stays on AI-native vs augmented analytics.
When an ai native data platform wins: Ad-hoc and recurring questions across mixed sources, analyst unavailable, audit required, method must compound month over month.
An ai native data platform is not a replacement for every BI seat. It is the layer that handles work between dashboard refreshes—discovery, ad-hoc cuts, recurring KPI packages—while governed dashboards remain the executive consumption surface. For the human-in-the-loop middle path, see Augmented analytics.
Migration Path: AI-Enabled → AI-Native
Most enterprises are not greenfield. They already run ThoughtSpot, Power BI, Hex, or Databricks with copilot features enabled. Adopting an ai native data platform follows a predictable HowTo sequence:

- Shadow mode (2–4 weeks) — Run the same recurring question through your existing copilot and through a candidate ai native data platform. Compare audit depth and rerun time—not just answer text.
- Recurring workloads (1–2 months) — Route weekly KPIs and monthly cohorts to the native stack. Keep BI for fixed dashboards. Bind RAG to existing semantic definitions where possible to avoid duplicate metric layers.
- Embedded access (ongoing) — Enable chat, API, or kanban triggers so PMs and engineers request analysis without ticket queues. Multi-entry parity is a platform requirement once adoption scales.
- Governance hardening — Approve memory cards, export the audit trail, and enforce connector roles. Budget is earned when compliance can replay the evidence.
Teams that skip Phase 1 and buy on demo SQL often discover their copilot and native stack produce identical answers—but only a true ai native data platform remembers definitions next month.
Buying Criteria: 12-Question Checklist
Score each Yes / Partial / No when you POC an ai native data platform. Any No on questions 1–5 is a disqualifier for the AI-native label. This checklist is an evaluation framework—not a product star rating.

- Does the user submit a goal, not steps?
- Does the system produce a reviewable plan before executing?
- Can stakeholders inspect every SQL and intermediate dataset?
- Does completed work distill into reusable memory with approval flow?
- Does the agent self-correct when a source fails?
- Are relational DBs + files + docs queryable in one task?
- Is business knowledge retrieved per query (RAG), not pasted?
- Is the same agent available via API without feature gaps?
- Does the platform support human-in-the-loop approval for memory?
- Can tasks run while the user is away (async completion)?
- Is there a free tier or POC path under two weeks?
- Does the vendor publish first-party case evidence with inspectable metrics?
Treat questions 1–5 as veto criteria for any vendor claiming to sell an ai native data platform. Partial scores on 6–8 often indicate a strong warehouse-native agent that still struggles with files or API parity—acceptable for some teams, disqualifying for mixed-source estates.
Market Landscape (Neutral Comparison)
Buyers comparing an ai native data platform compete across several neighboring categories. Fit depends on where your data lives and how much multi-source orchestration you need:
| Category | Typical products | Strength | Common gap vs full AI-native |
|---|---|---|---|
| Warehouse-native NL | Snowflake Cortex Analyst, Databricks Genie | Strong when data gravity is one platform | Weaker multi-cloud + file + API parity |
| Governed search BI | ThoughtSpot, Power BI Copilot | Business self-serve on semantic models | Less multi-step agent planning |
| Notebook / IDE AI | Hex Magic, Mode | Analyst craft + transparency | Exec self-serve and memory cards |
| Lakehouse / warehouse | Snowflake, Databricks, Iceberg stacks | Storage, table format, SQL compute | Does not host agent memory or multi-entry parity |
| Real-time context engines | Streaming platforms with an MCP serve path | Fresh events for agents | Thin on file, document, and recurring analytics |
| Multi-source Data Agent platforms | InfiniSynapse and peers | Goal → plan → evidence across sources | Requires metric contracts to shine |
A data lakehouse or warehouse remains the store. An ai native data platform sits above it: context, orchestration, and memory. It does not replace the table format or the pipeline. For a vertical implementation, the AI data platform for SaaS product analytics guide connects events, billing, CRM, support, tenant controls, and embedded delivery. Warehouse vendors describe governed NL agents in Databricks’ Genie / data-agent post. Compare memory and audit depth on your requirements. Tool rankings: Best AI Tools for Data Analysis. Lakehouse fork: Databricks Genie vs Data Agent. The vendor stack review is databricks data analytics platform. Shortlist only products that pass pillars 1–5.
Reference Implementation: InfiniSynapse
Optional product note (commercial): InfiniSynapse is one ai native data platform used as a reference architecture—not a claim that it is the only compliant product. Map every component below to the five layers and pillars, then re-score competitors the same way. Skip this section if you only need the educational framework.
| Component | Role |
|---|---|
| InfiniAgent | Orchestration and phased planning |
| InfiniSQL | Federated agentic query across connectors |
| InfiniRAG | Business knowledge bound to sources |
| Memory cards | Distillation with DRAFT → approved workflow |
| Task timeline | Full audit trail per analysis |
| Multi-entry | Chat, web, agent_infini API |
Illustrative first-party cases (not third-party audited) — use them as a demo script for any candidate, not as independent benchmarks:
- Lobster Moonlight (2026-05-14): 7,444×22 Excel; chat request → five autonomous phases in ~6 minutes; 12 charts; ~90 seconds user input.
- April → May rerun (2026-05-12): Growth analysis distilled to a memory card; May rerun in one sentence (compounding vs session chat).
For methods context: AI for Data Analysis. The Yes scores on checklist items 1–12 are a vendor claim. Rerun them on your schema.
Deployment Patterns
| Pattern | How teams use an ai native data platform |
|---|---|
| A — Analyst primary | Web for deep tasks; memory cards for weekly/monthly reruns; API for scheduling |
| B — Business self-serve | Chat for light questions; escalate when complexity exceeds one SQL |
| C — Embedded engineering | Agent API from Code Agent / kanban when tickets need data evidence |
| D — Hybrid with BI | Native platform for discovery/ad-hoc/recurring; Tableau/Power BI for fixed dashboards |
Frequently Asked Questions
What is an AI native data platform?
An ai native data platform is software designed from the ground up for autonomous Data Agents—connecting to enterprise sources, running goal-driven multi-step analysis with audit trails, distilling reusable memory, and exposing agents through multiple entry points. It is not a traditional BI tool with an AI chatbot added.
How is it different from an AI-enabled BI tool?
AI-enabled BI adds copilots to dashboard workflows—the user still drives each step and the primary artifact is a chart. An ai native data platform treats the agent as the workflow: goal in, audited analysis + memory out.
Do I still need a data warehouse?
Often yes. An ai native data platform connects to your warehouse, databases, and files—it does not replace storage. It replaces the manual loop of discovery → query → chart → forget → repeat.
What connectors should I require in an RFP?
For an ai native data platform, minimum: one relational DB, one file type (XLSX/CSV), and one knowledge source (docs or dictionary). Ideal: MySQL/Postgres + MongoDB + warehouse + file upload + RAG on business definitions. Confirm connector depth in a POC, not a slide.
How do I evaluate AI-native claims in vendor demos?
Run the same recurring question twice on any candidate ai native data platform. First session: full analysis. Second session: ask to rerun with new data and the same definitions. If the vendor re-explains schema from scratch, it is not AI-native.
Is InfiniSynapse the platform or just a Data Agent?
Both. InfiniSynapse is an ai native data platform that hosts Data Agents (orchestration + SQL tools + RAG + audit + memory). “Data Agent” names the actor; “AI-native platform” names the system it runs in. See What Is a Data Agent?.
Who is accountable for this article?
William Zhu and the InfiniSynapse Data Team, under editorial standards. First-party cases are labeled—not third-party audits.
Educational vs commercial content?
Teaching sections (definition, layers, pillars, migration HowTo, checklist, FAQ) stand alone. The InfiniSynapse reference-implementation note is optional and marked commercial.
Who wrote this
Named author. William Zhu — InfiniSynapse cofounder (GitHub @allwefantasy). Team: InfiniSynapse Data Team. About: editorial standards. Corrections: zhuhl@infinisynapse.com.
References
- [Framework] NIST. AI Risk Management Framework. nist.gov/itl/ai-risk-management-framework.
- [Framework] NIST. SP 800-53 Rev. 5. csrc.nist.gov/pubs/sp/800/53/r5/final.
- [Standard] ISO. ISO/IEC 42001:2023. iso.org/standard/81230.html.
- [Security] OWASP. Top 10 for Large Language Model Applications. owasp.org/www-project-top-10-for-large-language-model-applications/.
- [Vendor] Databricks. Pushing the frontier of data agents with Genie. databricks.com/blog/pushing-frontier-data-agents-genie.
- [Independent] Gartner. Peer Insights — Analytics and Business Intelligence Platforms. gartner.com/reviews/market/analytics-business-intelligence-platforms7. [Independent] G2. Business Intelligence category. g2.com/categories/business-intelligence.
- [Internal hub] InfiniSynapse. Data Agent Manifesto. infinisynapse.com/en/blog/data-agent-manifesto.
- [Internal hub] InfiniSynapse. What Is a Data Agent? infinisynapse.com/en/blog/what-is-a-data-agent.
- [Internal hub] InfiniSynapse. AI-native data analysis. infinisynapse.com/en/blog/ai-native-data-analysis.
- [Internal hub] InfiniSynapse. Augmented analytics. infinisynapse.com/en/blog/augmented-analytics.
- [Internal hub] InfiniSynapse. AI for Data Analysis. infinisynapse.com/en/blog/ai-for-data-analysis.
- [Internal hub] InfiniSynapse. Databricks Genie vs Data Agent. infinisynapse.com/en/blog/databricks-genie-vs-data-agent.
- [Use case] InfiniSynapse. Best AI Tools for Data Analysis. infinisynapse.com/use-cases/best-ai-tools-for-data-analysis.
- [Person] William Zhu. Cofounder, InfiniSynapse. github.com/allwefantasy.
Conclusion
The 2026 buyer's question for analytics infrastructure: was this platform built for agents, or did AI arrive as an add-on?
An ai native data platform connects sources, runs autonomous agents, retrieves business knowledge, logs auditable evidence, distills memory, and delivers the same agent in chat, web, API, and MCP. Evaluate with the five pillars and the twelve-question checklist, then rerun one recurring question. Skipping shadow mode is the common procurement mistake.
Start with AI-native data analysis for the paradigm, What Is a Data Agent? for the actor, what an AI data analyst does for the analysis-specialized software, the unstructured data platform in the content plane for documents and multimodal files, and AI for Data Analysis for the methods landscape.
Optional product note (commercial): To try a multi-source agent path, begin at https://app.infinisynapse.com/.