IDE vs Web Data Analysis: Start, Then Audit
By William Zhu (independent public engineering profile: GitHub @allwefantasy; no personal LinkedIn) & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-08-28 · Last verified: 2026-08-28 · Next review: 2026-11-28 · About · Editorial standards · Privacy · Publishing terms · Corrections
Table of Contents
- TL;DR
- What the split actually is
- A start-here, share-there framework
- How the two surfaces split the job
- Tool landscape on both sides
- Implementation steps for a split definition of done
- Desk sample: terminal sentence vs task files (InfiniSynapse desk log)
- How to cite this page
- Selection scorecard
- Failure modes that leak or stall
- Frequently Asked Questions
- Conclusion
TL;DR
We evaluate start-here, share-there splits at the InfiniSynapse desk on sanitized composites; first-party figures on this page are desk log IDE-WEB-TRAIL-20260822, not customer uplifts and not a third-party bake-off.
Direct answer: ide vs web data analysis separates a configured IDE or CLI client from server-side web review. The optional agent_infini interface, instructions, and /tasks workspace are InfiniSynapse components—not native Cursor, Claude Code, Codex, or Gemini features.
Download evidence: desk log · aggregate CSV · verify script. These files record this desk run as a first-party sanitized composite.
What you'll learn:
- Why the two surfaces split duties instead of competing
- When to start in the editor versus in Chat
- What “done” means: files a teammate can open
- Desk log
IDE-WEB-TRAIL-20260822, of a terminal sentence that hid a failed task - Failure modes that make one side look finished while the other is empty
Cursor’s Agent documentation and privacy documentation describe that client’s native surface and data controls. Anthropic’s Claude Code security guidance documents permissions and security. These sources did not evaluate this workflow. Retrieved 2026-08-28.
What the split actually is
Key Definition: ide vs web data analysis is an operating split where separately configured clients start authorized work and a server-side task workspace acts as this workflow’s system of record for reviewable steps, SQL, and artifacts.
OpenAI Codex security documentation and Gemini CLI sandboxing support client-control claims only. They do not imply shared configuration, compatibility, or vendor endorsement.
Author qualifications and accountability
William Zhu is an InfiniSynapse cofounder. His public GitHub profile, InfiniSynapse organization, and repositories auto-coder, byzer-llm, and BYZER-RETRIEVAL verify identity and engineering work. They do not validate this workflow. No degree, customer case, media review, certification, vendor recognition, or external assessment is claimed. 2026 WAIC Future Tech OPC Excellence Award (homepage; not a review). 2026-07-29 attestation.
Internal terms this page uses: a start surface is an independently configured client or server-side web session. The web trail is the first-party /tasks record. Each client requires separate instructions, config, permissions, and scoped credentials.
The question is not “which UI is smarter.” ide vs web data analysis asks who starts and who audits. Engineers start in the repo. Reviewers audit in the browser. Non-engineers may start in Chat. All three should land on the same task object.
ACM Artifact Review and Badging supports recording artifacts and reproducibility status. The FAIR principles paper supports reusable metadata and provenance. Neither assessed InfiniSynapse or this desk log.
For ide vs web data analysis, these sources justify disclosure and artifact discipline—not a product-quality claim.
AI for data analysis already split copilots from agents. The IDE is a copilot-shaped surface until it calls the agent. The web trail is where the agent leaves evidence.
The IDE starts work
Cursor, Claude Code, Codex, and Gemini are good at stating a goal next to the repo. ide vs web data analysis uses that habit. It does not use the IDE as a warehouse, a key store, or an archive.
The web trail is what you share
Steps, SQL, Markdown, charts, downloads. A teammate without your laptop can open them. That is the definition of done for ide vs web data analysis. A green terminal is not.
A start-here, share-there framework
| Surface | Starts the goal | Holds the record | Typical user |
|---|---|---|---|
| IDE + Skill | Yes | No | Engineer in a repo |
| Terminal CLI | Yes | No | Engineer without an IDE |
| Web Chat | Yes | Partial (until you open the task) | Non-engineer |
| Task workspace | No | Yes | Anyone who must audit |
ide vs web data analysis is the table, not a winner. Share policy, source authorization, and task schema—not a secret.
Separate credentials, one policy
Each person, device, environment, and CLI client should receive an independently scoped, revocable credential where feasible. Web access uses a server-side login session and server-side secrets; no API key belongs in browser code.
One source list
db ls from the IDE and the source picker on the web should match. If they do not, fix the product connection. ide vs web data analysis does not get a shadow schema for the editor.
How the two surfaces split the job
The IDE is fast at “same pack as last week” because the repo and the question share a calendar. The web is fast at “show me the SQL” because the trail is a page. ide vs web data analysis assigns those jobs on purpose.
Self-service analytics lives on the web side. Engineers who refuse to screenshot a BI tile live on the IDE side. Exploratory data analysis can start on either side of ide vs web data analysis and must finish in the folder.
If you force everyone into the IDE, you lock out reviewers. If you forbid the IDE, you lock out people who already live in a repo. ide vs web data analysis refuses both purges.
Tool landscape on both sides
ide vs web data analysis can span clients only after each configuration, instruction set, and permission boundary is reviewed.
Cursor / Claude Code. IDE start. Web audit.
Codex / Gemini CLI. Separate clients that may follow the same policy; compatibility is not automatic.
Web Chat. Start for people who will never install an editor.
Task workspace. This workflow’s system of record, not the organization’s only archive.
The product connects the database you already have. The split does not migrate it. Private deployment and desktop exist; this page’s check still starts on the web console so the trail is visible to someone who does not have your IDE.
Zero-config against a replica you already run is enough. The product is a professional data analyst, not a ChatBI box that only emits SELECT. Multimodal inputs and 100+ file formats still land as task artifacts when you attach files the product already accepts. Neither surface becomes a new ingestion bus, and neither writes definitions back into production.
If the IDE already bound a knowledge pack to the replica, web Chat should retrieve the same pack. If it does not, the bind is wrong—not “the web thinks differently.” Organization memory is the bound pack plus the task folder. Composer history is not memory. AI-native boards, if a goal produces one, are files in that folder, not a tile catalog you must pre-build for one surface.
Do not keep two records
A Markdown file in the repo plus a different memo in the task is how definitions fork. Pick the task as the record. The repo can link to the task. ide vs web data analysis that keeps both “just in case” will drift by Friday.
Implementation steps for a split definition of done
- Review each client. Record IDE/client, version, model, config, instructions, and permissions. Expected result: Every start surface has explicit boundaries.
- Issue separate credentials. Scope each person, device, and environment without publishing values. Expected result: Each credential can be revoked independently.
- Start a disclosed goal. Record goal, SQL constraints, task ID, timestamps, status, and errors. Expected result: The run is identifiable.
- Review and hash artifacts. Preserve successful and failed runs, SQL, files, and wall-clock definition. Expected result: Evidence can be compared.
- Run the reviewer protocol. Have a teammate download artifacts and record conflicts of interest. Expected result: Review does not require the originating IDE.
Those six steps are the whole of ide vs web data analysis on a new team. You can complete the educational diagnosis without installing an IDE: write the definition of done as “teammate opens /tasks.” The install is optional until that sentence is the one you will defend.
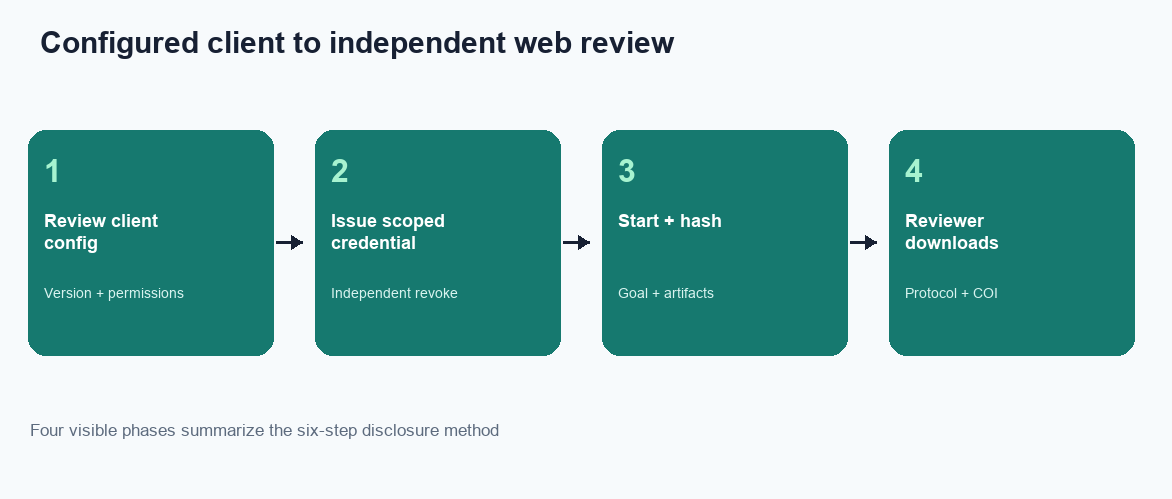
Figure. Educational four-step sequence the desk uses to tell a terminal sentence from a shared trail. Expected result after step 6: both starts land on one folder, and a teammate without the IDE can download the memo, charts, and CSV. Not a product screenshot or a customer SLA.
Write the standing goals on one page and use them on both surfaces of ide vs web data analysis: weekly ops pack, experiment readout, finance exception list. If the IDE invents a new name for “active store” and Chat uses the bound name, the bind is only half-used. Fix the Skill or the prompt. Do not keep two glossaries.
Confirm agent_infini is present only on machines that start from an editor. Web Chat does not need the binary for ide vs web data analysis. The educational diagnosis does not require every reviewer to install Cursor. It requires every reviewer to open the folder.
Write “done” as three clicks
Click the task. Read the plan. Download a file. If a surface cannot produce those clicks, it is not finished. ide vs web data analysis uses the same three clicks whether the start was Composer or Chat.
Teach both starts the same goal language
“Weekly revenue pack on the replica we already connected,” not “write me the join.” The IDE will try to be helpful and emit SQL. The web will try to be helpful and emit SQL. ide vs web data analysis wants the pack. SQL is the audit.
Desk sample: terminal sentence vs task files (InfiniSynapse desk log)
This is a first-party InfiniSynapse desk log of ide vs web data analysis, not a customer case or uplift claim. Run ID: IDE-WEB-TRAIL-20260822. Date: 2026-08-22 (Saturday). Source: an authorized read-only sanitized replica. Download the desk log and aggregate CSV.
Saturday, an IDE run printed “pack ready.” Nobody opened /tasks; the task had failed on a missing bind.
| Retrieval state | Confident sentence | Bind present | Memo + charts + CSV |
|---|---|---|---|
| IDE “pack ready” only | 1 | 0 | 0 |
Open /tasks before done | 0 | 1 | 3 |
After the team added “open the trail” to done, the same goal produced a Markdown memo, two charts, and a CSV a reviewer could check (three objects in that last column). Wall clock on the successful run was about twenty minutes (warehouse time excluded). Cite this table as InfiniSynapse desk log IDE-WEB-TRAIL-20260822. Do not cite it as customer ROI, a 60% speedup, a bake-off win, or a NIST / ISO / W3C / Cursor / Anthropic experiment. We do not publish named-logo customer cases on this page. The only honest claim is the artifact counts and the wall-clock on this run.
The useful comparison in ide vs web data analysis is not IDE versus web quality. It is sentence versus files. A split that stops at the sentence is a hallway conversation.
Reliable ide vs web data analysis keeps the originating client visible while making review independent of it.
The second run produced objects a reviewer could name: retrieved passage, SQL, memo, charts. The first run produced a vibe. Wall clock on the failed run was short because nobody waited for files. That speed is not a feature. It is how unread tasks hide.
The extract in ide vs web data analysis was a CSV, not a write-back. Nobody asked either surface to update production rows. Read-only or sanitized sources stay the rule whether the start was Composer or Chat. A write-capable URI “because the IDE can handle it” is a process failure.
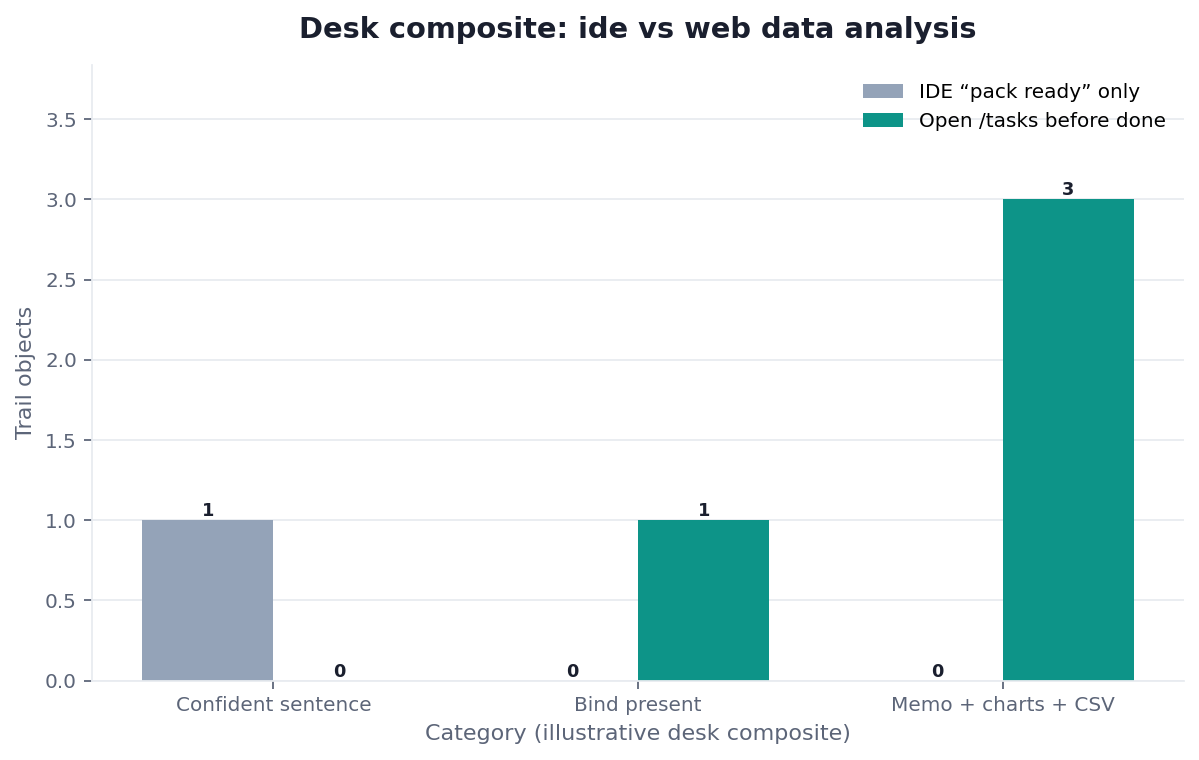
Figure. InfiniSynapse desk log IDE-WEB-TRAIL-20260822: Saturday IDE print left 1 / 0 / 0; first-party task review left 0 / 1 / 3. First-party sanitized demo—not an independent benchmark.
Evidence boundaries and external validation status
IDE-WEB-TRAIL-20260822, its Markdown file, and aggregate CSV are first-party sanitized demo evidence. They are not a customer case, benchmark, third-party evaluation, vendor test, certification, or media review. No independent third party or media outlet had reproduced or evaluated this workflow as of 2026-08-28.
Replication should disclose IDE/client, version, model, config, and permissions; first-party interface, CLI, and instruction hash; separate credential scope without its value; source authorization and snapshot; goal and SQL constraints; task IDs, timestamps, status, and errors; SQL and artifact hashes; failed and successful runs; reviewer protocol; wall-clock definition; and conflicts of interest.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Desk log on this page | Sentence-vs-files collision, artifact counts 1/0/0 → 0/1/3, ~20 min wall-clock, run ID, downloadable log | Customer uplift %, vendor bake-off win, named-logo case |
| Markdown and aggregate CSV | Two observations, method, counts, reviewer flag | Raw, source, customer, or third-party data |
| Vendor documentation | Native client controls and limitations | Native agent_infini, shared configuration, or endorsement |
| ACM and FAIR guidance | Artifact and metadata practices | Independent validation of this workflow |
How to cite this page
Page: Zhu, W., & InfiniSynapse Data Team. (2026). IDE vs Web Data Analysis: start, then audit. InfiniSynapse
Run: InfiniSynapse Data Team. (2026). Desk log IDE-WEB-TRAIL-20260822 (sanitized composite)
Neither form is an audit. Cite only the artifact counts. No independent reproduction exists. Send contradictions to zhuhl@infinisynapse.com.
Selection scorecard
| Criterion | Weak split | Strong split |
|---|---|---|
| Start | One surface mandatory | IDE, CLI, or Chat as needed |
| Record | Terminal or chat prose | Task steps and downloads |
| Identity | Shared or browser secret | Separate scoped credentials and server-side web session |
| Sources | Different lists per surface | One authorized list |
| Done | “The model said done” | Teammate opened /tasks |
If a vendor pitch answers ide vs web data analysis by making you pick a winner, score it as a bake-off. If it can show one trail from either start, keep listening. If it wants the key in application code, stop. A bake-off that never opens /tasks is a theme contest. A single folder from two starts is the analyst object.
Score ide vs web data analysis the same way on both surfaces. Three clicks: task, plan, file. If the IDE cannot produce them, it is a copilot. If Chat cannot produce them, it is a thread. Keep the clicks.
Failure modes that leak or stall
These three failures make ide vs web data analysis look finished on one side only. A browser token that starts tasks is the same class of secret exposure the OWASP Top 10 for LLM Applications flags; keep the console key instead.
Terminal called “done”
The IDE returned a sentence. The task died. ide vs web data analysis that treats stdout as done will ship empty reviews. Open the trail.
Web-only people blocked
The only copy of the memo lives in someone’s Composer history. Reviewers cannot see it. ide vs web data analysis failed the share side. Move the record to /tasks.
Two records
Repo wiki says one definition. Task memo says another. ide vs web data analysis that keeps both will lose the argument in the next meeting. Pick the task.
Before you call ide vs web data analysis production-ready, check four things: a teammate without your IDE can open the last task, the key is not in a frontend, db ls matches the web picker, and “done” means files. That inspection is the diagnosis.
W3C PROV-O supports provenance modeling, while OpenTelemetry traces supports invocation chains. NIST SSDF SP 800-218, the NIST AI RMF, UK NCSC secure AI guidance, OWASP GenAI/LLM Top 10, and GitHub secret scanning support control design. None tested this demo.
Related guides: Codex Data Analysis, Gemini CLI Data Analysis, API Key for a Data Agent, What Is a Data Agent, Data Knowledge Base, Knowledge Base vs Semantic Layer, Natural Language to SQL, Claude Code Features, Claude Code Install, How Claude Code Works, and MCP for Data Analysis.
For adjacent controls, see Codex Data Analysis, Gemini CLI Data Analysis, and API Key for a Data Agent.
Compare the IDE prompt and the web artifacts
Start the same standing goal from the editor and from Chat, then confirm both land on one task folder with steps and files. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseSourcing and accountability. William Zhu’s editorial profile and public GitHub work verify identity and engineering activity, not this workflow’s results. Vendor docs define native client controls; independent guidance supports limited reproducibility and artifact-recording claims. None evaluated InfiniSynapse. 2026 WAIC Future Tech OPC Excellence Award (homepage; not a review). COI: InfiniSynapse sells the first-party interface and workspace evaluated here.
Frequently Asked Questions
Is the IDE better than the web for analysis?
Bottom line: No. ide vs web data analysis is not a bake-off. The IDE is a start surface. The web trail is the shared record. Quality lives in the task, not in the editor chrome.
Can I skip the web workspace if I use Cursor?
Bottom line: No. Without the trail, there is no teammate interface. Composer is not an archive. Opening /tasks is the second surface the split requires.
Do non-engineers need an IDE?
Bottom line: No. They start in web Chat with the same sources and the same goal. The split still ends in /tasks.
Where does the API key live in this split?
Bottom line: IDE and CLI clients use separately scoped, revocable credentials. Web access uses a server-side session and server-side secrets; no API key is exposed to browser code.
Do Cursor or Anthropic docs pick a winner between IDE and web?
Bottom line: No. Cursor’s docs and Anthropic’s Claude Code docs describe editors. They do not decide whether a teammate can open the same /tasks folder.
Is a confident terminal sentence third-party proof?
Bottom line: No. A sentence is a local story. ide vs web data analysis treats proof as files a reviewer can download.
Conclusion
ide vs web data analysis is useful when each client is independently configured and the first-party task is this workflow’s system of record. The operational test is whether a reviewer can inspect authorized, hashed artifacts without the originating IDE.