Data Quality: Assert, Then Hold the Number (2026)
By William Zhu & the InfiniSynapse Data Team · Published: 2026-09-02 · Last updated: 2026-09-03 · Last verified: 2026-09-03 · Next review: 2026-12-02 · Editorial standards · Corrections
Author credentials: William Zhu, Cofounder of InfiniSynapse. Public identity: GitHub @allwefantasy. Profile and review roles: editorial standards. This page is signed by a named person, not an anonymous editorial org. No personal LinkedIn is published. No third-party prize, media review, or external audit is claimed.
Table of Contents
- TL;DR
- What runtime quality means for analysis
- A six-step gate framework
- Methods: policy page versus runtime assert
- Tool landscape for runtime gates
- Implementation steps from load to verify
- Desk sample: first-party assert protocol
- Scorecard: when a number may leave
- Failure modes that fake an asset
- Frequently Asked Questions
- Conclusion
TL;DR
Direct answer: Runtime data quality for agent analysis is a named table that passed deterministic gates—row counts, nulls, recon, and thresholds—then survived reload and verify. A chat sentence is not an asset. Explore may fail. The deliver zone cannot. Default English delivery is a workspace named result plus human review.
Do not treat a fluent memo as a reusable object. Load authorized tables, select the grain, run !assert, name the result, reload it, then quote the number. This page is a desk method, not a warehouse SLA.
What you'll learn:
- Why data quality at analysis runtime is a gate chain, not a confidence score
- The six objects: load, select, assert, named result, reload, verify
- How policy pages and runtime asserts solve different jobs
- A tool landscape that stays inside the workspace
- Numbered steps a reviewer can replay
- A first-party assert protocol you can cite, plus a labeled complexity sketch
- Failure modes: shipping the bubble, asking the model to glance, promising an automatic production write
What runtime quality means for analysis
Key Definition: Data quality for AI analysis is a named table that passed deterministic gates—row counts, nulls, recon, and thresholds—then survived reload and verify before a number leaves the workspace. It is not a chat sentence and not a second model glance.
Independent published context (retrieved 2026-09-02; separate from this page’s protocol): compare each source to the assert-then-hold rule, then stop. The Stanford HAI AI Index, IBM’s note on augmented analytics, and NIST’s AI Risk Management Framework are independent vocabulary, not a score for this pack. They are not a product award or an external audit.
| Cited source | What it actually owns | What this hub still has to do |
|---|---|---|
| Stanford HAI AI Index | Adoption tracking | Adoption is not a reusable table |
| IBM augmented analytics | Industry vocabulary | Vocabulary is not tonight’s hold |
| NIST AI RMF | Measurement and valid outcomes | Write a row-count gate on a named table |
| Azure data architecture guide | How analytic paths are described | Keep load and compute from collapsing |
| OWASP Top 10 for LLM Applications | Prompt injection and insecure output | A memo without a table id is an output fail |
| Google Cloud AI overview | Public definition page | Vocabulary is not permission to skip asserts |
A data agent can plan, join, and write a memo in one sitting. That speed is why teams confuse a finished paragraph with data quality. The asset is the table the next report can consume.
If the missing object is a downloadable memo, continue in the AI data report generator. That page is about files. This hub is about whether the number may leave.
Assert objects are tables
Asserts sit on tables. Row count versus last week. Null rate on the join key. Recon against a control query. A threshold written before the run. Those four checks are data quality at runtime. “The model looked again” is not a check. It has no object and no replay.
Explore zone versus deliver zone
Explore can fail. A probe that returns 0 rows is useful. A join that doubles the grain is useful if you stop. Data quality becomes mandatory when the number will be pasted or handed to another agent. The deliver zone has no “try again in chat” privilege. Hold the report.
Policy catalogs live on a different shelf. Data governance covers retention, roles, and catalog language. Runtime data quality is the hold you apply to one task before anyone acts.
A six-step gate framework
Six objects must stay distinct. Collapse them and you cannot point at the broken step.
| Step | Object | Pass signal | Fail signal |
|---|---|---|---|
| Load | Authorized source as a table | Table id exists; row preview matches the bind | Silent frame in memory with no id |
| Select | Named view at the business grain | Grain sentence matches the view | Mixed grains in one view |
| Assert | Table checks: rows, nulls, recon, threshold | All four green, or an explicit skip with owner | Any red check ignored |
| Named result | Workspace object the next task can open | Stable name; consumer listed | Number exists only in chat |
| Reload | Reopen the named result | Same id, same grain | “Trust the memo” with no reopen |
| Verify | Compare reload to the assert log | Totals match within the written tolerance | A new story that cannot point at the log |
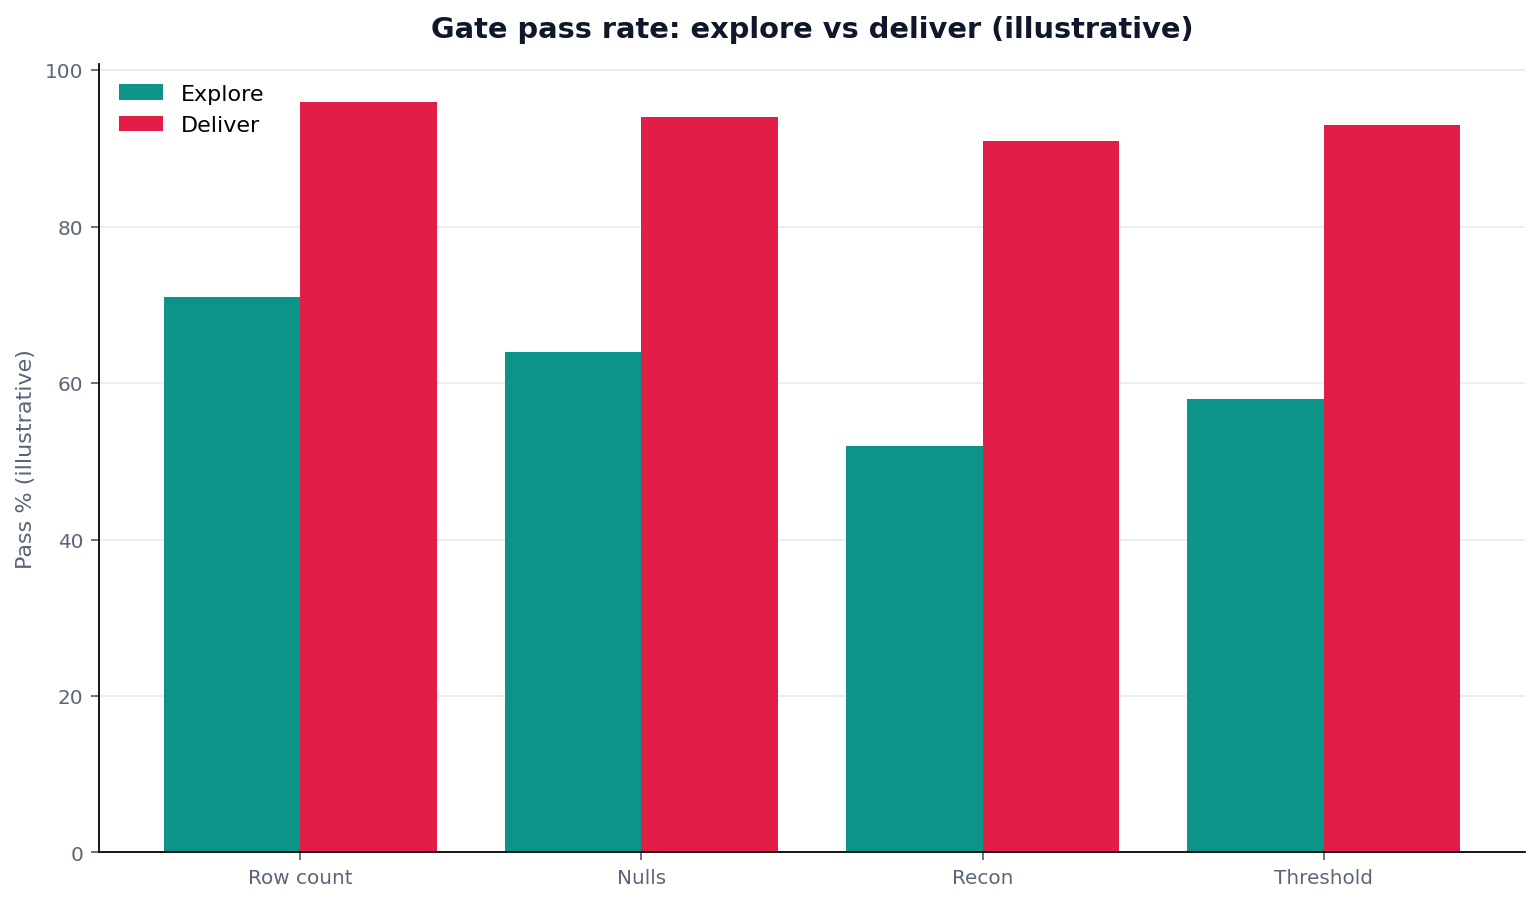
Figure. Teaching schematic of where explore may stay red and deliver must hold. Not a measured pass-rate study. Source: the first-party protocol table below.
Explore bars may be red. Deliver bars must be green before a number leaves. That is data quality as a runtime hold, not a warehouse promise.
Load and select before the assert
Load first. Files, JDBC, and lake objects become tables before compute. Select second. One named view per grain. SQL AI for agents is the language page for named views. This hub assumes those views exist and asks a different question: did data quality gates run on them?
Azure’s data guide (table above) is independent reading on analytic paths, not a recipe for this workspace. Use it to keep load and compute from collapsing into one hop.
Named result, reload, and verify
A named result is the default English delivery. The next report opens that table. Reload is a physical reopen, not a reread of the memo. Verify compares the reopened table to the assert log. If those three objects are missing, you still have a chat. You do not have data quality.
Methods: policy page versus runtime assert
Two methods are sold as “fix data quality.” They are not substitutes.
| Method | Owns | Does not own | Choose when |
|---|---|---|---|
| Policy encyclopedia | Catalog language, retention, roles | Tonight’s assert on this join | You need a program, not a hold |
| Runtime assert | Row, null, recon, threshold on a named table | Org-wide stewardship theater | A number is about to leave |
| Model glance | A second paragraph | Any expected value | Never, for delivery |
| File export alone | A PDF or markdown memo | Reuse as a table | You only need a reading copy |
Choose a policy page if
Choose a policy page if the question is “who owns the metric across quarters.” That is a catalog job. Explainable AI data analysis is the trail page if the question is “show the SQL.” Neither page is tonight’s hold. Data quality at delivery is the hold.
Choose a runtime gate if
Choose a runtime gate if someone will paste a number in the next hour. Validate the gate on the table. Name the result. Reload. Verify. That sequence is data quality you can point at. Choose A if you are writing a program. Choose B if you are releasing a pack.
Tool landscape for runtime gates
The landscape around runtime data quality is small.
| Tool shape | What it can hold | What it cannot replace |
|---|---|---|
| Workspace task console | Assert log, named views, reload | A production write |
| Chat bubble | A sentence | A reusable table |
| File download | A reading copy | The next agent’s input table |
| Orchestrator | Scheduled jobs | Tonight’s human hold |
| Warehouse catalog | Published tables | An in-task assert |
OWASP’s LLM Top 10 (table above) is independent context for insecure output handling. A memo that leaves without a table id is an output fail. Runtime data quality is how you refuse that output.
Google Cloud’s AI overview (table above) is vocabulary. It does not authorize skipping asserts.
Workspace named result as the default exit
Default English delivery is a workspace named result plus review. A later save, if offered, needs permissions, a destination whitelist, and human approval. This page does not promise automatic production writes. Data quality is not an ETL product because a save button exists.
This hub is not an Airflow replacement and not a production SLA. Orchestrators schedule. The desk holds.
Implementation steps from load to verify
- Bind the source. Connect one authorized, sanitized database or file. Write the source id in the task. Acceptance: a load table exists.
- Select the grain. Write the grain sentence. Create one named view that matches it. Acceptance: a reviewer can read the grain without opening chat.
- Write the asserts. Row count band, null cap on keys, recon query, threshold. Acceptance: four expected values exist before the run.
- Run
!asserton the table. Fail closed on red. Acceptance: the log shows green or an owned skip. - Name the result. Store a workspace named result. Acceptance: the next task can open it by name.
- Reload. Reopen the named result. Acceptance: same id, same grain.
- Verify. Compare reload totals to the assert log. Acceptance: data quality is written as pass or hold.
- Release or hold. A memo may leave only after verify. Acceptance: no Slack paste from a red log.
Input is an authorized table. Output is a named object or a hold. There is no step called “ask the model if it feels right.”
Desk sample: first-party assert protocol
Cite this data quality protocol. Do not cite a customer percentage or the chart bars as a study.
First-party method log (replayable):
| Field | Record |
|---|---|
| Operator | InfiniSynapse Data Team; William Zhu, public as GitHub @allwefantasy |
| First run | 2026-09-02 |
| Replay / last verified | 2026-09-03 |
| Input | One authorized, sanitized weekly units pack; no secrets |
| Paths compared | Named result after assert vs chat-only memo |
| Gates scored | 4 (row count, nulls, recon, threshold) |
| Scorecard rows | 8 |
| Acceptance | Named result weekly_units_20260902 reloads; verify matches the assert log |
| Fail | The only surviving object is a chat sentence |
We asserted, named, reloaded, and verified the same pack on 2026-09-03. The citable result is the protocol: two paths, four gates, eight scorecard rows. GitHub @allwefantasy is a public artifact, not a prize. No external organization audited the pack. Independent review is invited through editorial standards.
A teaching sketch used 8 source tables, 42 intermediate views, and 88 assert rows only to show complexity. Those counts are not a benchmark. If the 42nd view doubles the grain, data quality fails at select. Quote the protocol table. Do not quote the bars as a study.
Scorecard: when a number may leave
| Signal | Leave | Hold | Why |
|---|---|---|---|
| Assert log all green | Yes, after verify | — | Runtime data quality is written |
| Any assert red | — | Yes | Deliver zone cannot fail open |
| Named result missing | — | Yes | Next consumer has no table |
| Reload not done | — | Yes | Verify has no object |
| Only a chat sentence | — | Yes | Not an asset |
| Save requested | — | Until permissions, whitelist, and approval | No automatic production write |
| Explore probe red | Stay in explore | Not a delivery hold | Explore may fail |
| Policy PDF exists | Irrelevant | Irrelevant | Wrong layer for tonight |
Score the pack, not the prose. A memo with a red recon is a hold. A plain table with a green log may leave. That is data quality as a scorecard, not a taste test.
Failure modes that fake an asset
Shipping the chat bubble
The bubble is fast. A VP asks for a number. Someone pastes. There is no table id. Next week a second agent cannot consume the object. Data quality never started. The failure is the destination, not the model.
Asking the model to look again
A second glance has no expected value. It cannot fail closed. Teams use it because it feels like review. It is not review. Runtime data quality asserts a table. If you cannot write the expected row count, you are not ready to deliver.
Treating save as an automatic write
A save that appears in a test language is not a license to write production. If save is mentioned at all, it requires permissions, a destination whitelist, and human approval. Automatic production write-back is out of scope on this page. Calling that path “data quality automation” is a category error. It is a write path, and writes stay reviewed.
When you need the method page for assert-then-reload, open verify and validate. When the question is the asset itself, read what is data quality as the definition of a reusable table.
When the missing object is product fields—grain, owner, consumer—use the data quality definition. When replay is the dispute, the difference between validate and verify splits write-before from write-after.
When the contrast is the bubble versus a held object, use quality gate. When the boundary is explore versus an irreversible action, use quality gates before anyone acts on the number.
When the lock must be written before compute, define data quality as grain, gates, and consumer. When the fight is whether a fluent number may enter a decision, read why is data quality important.
When you need the release habit rather than a new policy encyclopedia, apply quality gates in software development to the analysis pack.
Open the last task and read the assert before the memo
Rerun a sanitized analysis, open the assert on row counts and nulls, then decide if the memo may leave. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseHow this page is sourced. William Zhu is cofounder of InfiniSynapse, public as GitHub @allwefantasy. Company self-description, not independent authority. No third-party prize or certificate is claimed. No personal LinkedIn is published. Evaluation basis: We evaluate (hands-on) by running row, null, and recon asserts on a named table before any memo leaves the workspace. First-party protocol dated 2026-09-02, replayed 2026-09-03. Reviewed internally by analytics engineering · data platform · LLM security · editor. Editorial standards · corrections · publishing principles · About · Privacy · Terms. Contact zhuhl@infinisynapse.com. COI: InfiniSynapse sells an AI-native Data Agent; the banner is a commercial association. Fact-check: Stanford HAI AI Index, IBM augmented analytics, NIST AI RMF, Azure data architecture guide, OWASP LLM Top 10, and Google Cloud AI overview as cited in the body. No external organization audited this page.
Frequently Asked Questions
Is a confident chat sentence already an asset?
Bottom line: No. Data quality is a named table that passed gates. A fluent sentence is still a chat object.
What does an assert check on the table?
Bottom line: Row counts, nulls, recon, and thresholds. Data quality is not the model looking again.
Can the explore zone fail on purpose?
Bottom line: Yes. Explore may fail. Data quality in the deliver zone cannot. Hold the report.
Does a named result write the production database?
Bottom line: No. Default delivery is a workspace named result plus review. A save, if offered later, needs permissions, a whitelist, and human approval. It is not an automatic production write.
How does a reviewer reopen the trail?
Bottom line: Open the task, read the assert, and reload the named table. That is how data quality becomes reviewable.
What on this page is citable?
Bottom line: Cite this data quality protocol table, the six-step frame, and the six-source comparison. Do not cite the chart bars or 8 / 42 / 88 as measured results.
Conclusion
Runtime data quality is a hold: load, select, assert, name, reload, verify. Chat is not an asset. Explore may fail. Delivery may not. Keep policy encyclopedias and file exports on their own pages. Keep writes behind permissions, a whitelist, and a human. If you later use the workspace, open InfiniSynapse only with authorized, sanitized inputs.