What Is Data Quality: Name the Table, Then Reuse (2026)
By William Zhu & the InfiniSynapse Data Team · Published: 2026-09-02 · Last updated: 2026-09-03 · Last verified: 2026-09-03 · Next review: 2026-12-02 · Editorial standards · Corrections
Author credentials: William Zhu, Cofounder of InfiniSynapse. Public identity: GitHub @allwefantasy. Profile and review roles: editorial standards. This page is signed by a named person, not an anonymous editorial org. No personal LinkedIn is published. No third-party prize, media review, or independent endorsement is claimed.
Table of Contents
- TL;DR
- The asset test, not a confidence score
- A four-object asset framework
- Methods: confidence versus a named table
- Tool landscape for a reusable asset
- Implementation steps to name the asset
- Desk sample: first-party reuse protocol
- Scorecard: can the next report consume it
- Failure modes that fake an asset
- Frequently Asked Questions
- Conclusion
TL;DR
Direct answer: The working answer to what is data quality for agent analysis is a named table that passed deterministic gates and can be consumed by the next report. Confidence in chat is not the asset. A file without a table id is still a transcript. Explore may fail. Delivery may not. Default English delivery is a workspace named result plus review.
This page is the asset definition under the data quality hub. It does not rewrite a warehouse catalog. It asks whether next week’s report can open the same object.
What you'll learn:
- Why teams that ask what is data quality and then paste a bubble never created an asset
- The four objects: chat, file, named table, next consumer
- When a probe stays in explore and when a table must be named
- A landscape that keeps the handle inside the workspace
- Numbered steps a reviewer can replay
- A first-party reuse protocol you can cite, plus a labeled teaching sketch
- Failure modes: quoting the bubble, filing a transcript, treating name as a write
The asset test, not a confidence score
Key Definition: The working answer to what is data quality for agent analysis is a named table that passed deterministic gates—row counts, nulls, recon, and thresholds—and can be consumed by the next report without asking the same question again. Confidence in chat is not the asset. A file that cannot name its table is still only a transcript.
Independent published context (retrieved 2026-09-02). Compare each source to the asset test, then stop. The Stanford HAI AI Index is independent context for AI adoption without a shared reuse bar. The European Commission’s approach to artificial intelligence is independent policy vocabulary. CISA’s artificial intelligence page treats AI outputs as objects that need controls. Those sources did not run this fixture.
| Cited source | What it actually owns | What this pack still has to do |
|---|---|---|
| Stanford HAI AI Index | Adoption tracking | Adoption is not a named table |
| European Commission AI approach | Policy vocabulary | Policy is not tonight’s id |
| CISA AI | Outputs that need controls | A sentence leaving the desk is an output |
| Google BigQuery docs | Querying stored tables | Consumers query tables, not paragraphs |
| AWS Redshift docs | Stored analytic tables | A warehouse contract is not tonight’s in-task id |
| PostgreSQL docs | The same idea in another engine | Consumers open tables |
Teams treat a fluent sentence as finished work. The sentence is a presentation. The asset is the table the next report can open. If you cannot point at an id, you have not answered what is data quality. You have a chat object.
If the missing object is product fields—grain, owner, consumer—continue in the data quality definition. That page assetizes the pack. This page answers what is data quality as the reusable table itself.
A named table, not a confident sentence
A confident model is not a gate. The model can sound sure while the grain is doubled. The working answer to what is data quality is not “the agent was confident.” It is “the table passed row, null, recon, and threshold checks, and it has a name.”
CISA AI (table above) treats AI outputs as objects that need controls. A sentence leaving the desk is an output. It does not replace a named table. It does not answer what is data quality for tonight’s pack.
Next-week consumption is the test
Ask one question: can next week’s report consume this without asking again? If the answer is “reread the chat,” you failed the asset test. If the answer is “open weekly_units_desk,” you have a candidate. That is how you decide what is data quality after the memo looks fine.
Data management is the catalog layer for stores and stewardship. This page stays on tonight’s named result. Catalog language does not answer what is data quality for a number that leaves in an hour.
A four-object asset framework
Four objects get confused. Only one is an asset.
| Object | Reusable next week? | Pass signal | Fail signal |
|---|---|---|---|
| Chat sentence | No | — | Number exists only in prose |
| Downloaded file | Only as a reading copy | Someone can reread | Next agent cannot query it |
| Named table | Yes, if gates passed | Stable id; green assert | Missing id or red log |
| Next consumer | Proves the asset | Second task opens the id | “Ask the first chat again” |
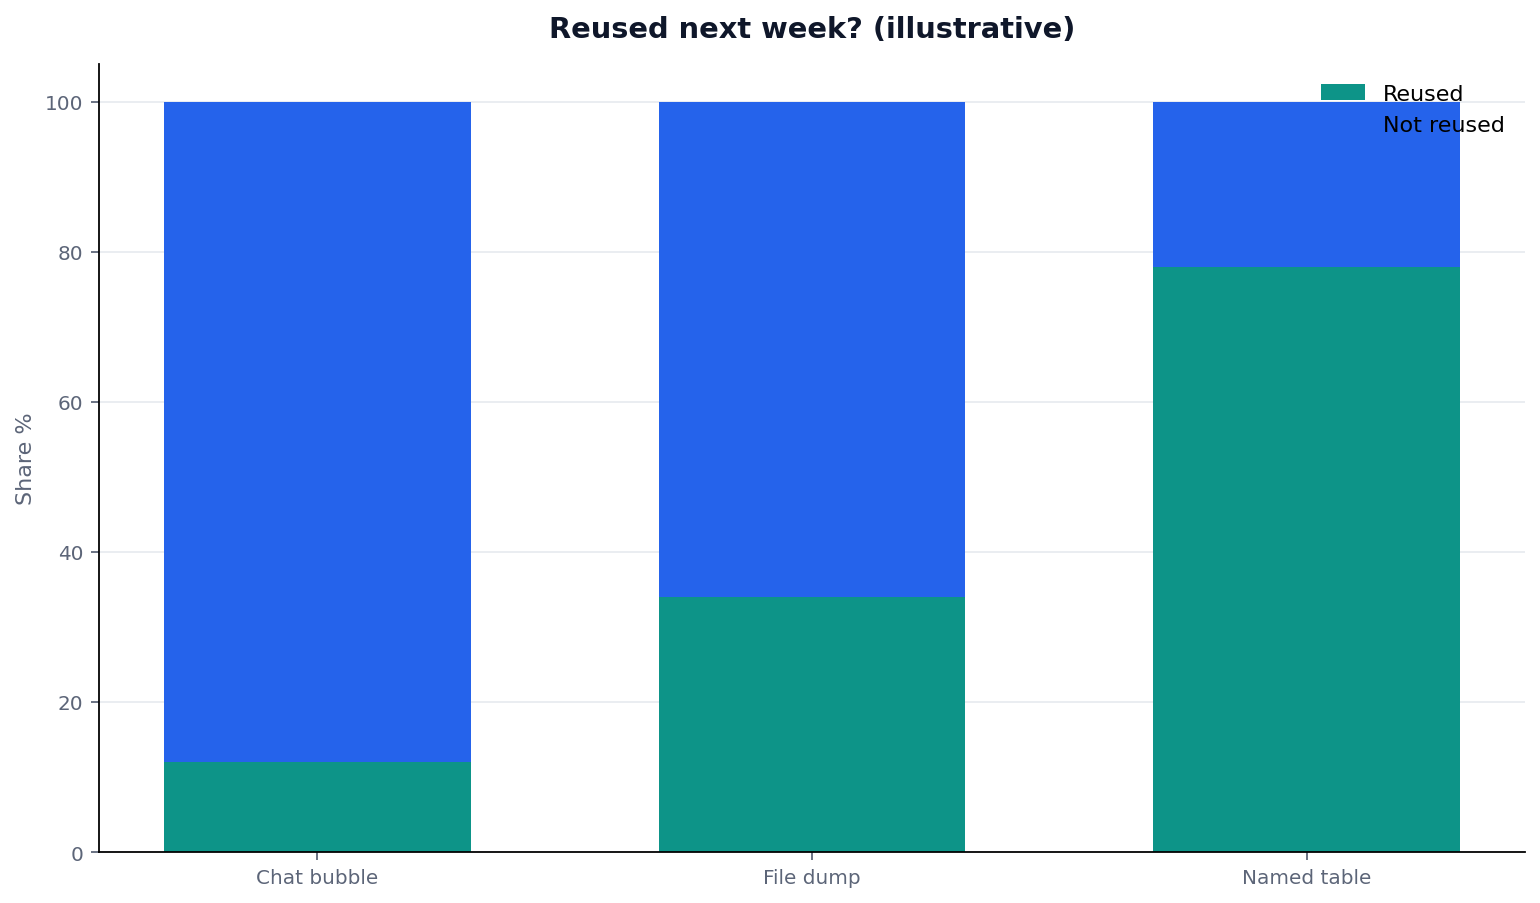
Figure. Teaching schematic. Not a measured study. Source: the protocol table below.
Chat and files fail reuse. Named tables pass when gates are green. That split is what is data quality as a reuse test, not a taste test.
Chat and files fail reuse
A chat file is a transcript. It can be attached. It cannot be joined. Teams that ask what is data quality and then point at a markdown export are pointing at a reading copy. The next report still has to rebuild the grain.
Google BigQuery docs (table above) remind you that consumers query tables, not paragraphs. They do not endorse this desk. They do not replace the name you must write to answer what is data quality.
The named table is the reusable object
Name the result after the assert is green. The next report opens that id. The next agent binds it as a source. That is the only object that answers what is data quality without a second interview. A pretty memo with no id is still chat.
If you need a reading copy after the name exists, use the AI data report generator. The file is not the asset. The named table is the asset.
Methods: confidence versus a named table
Two methods are sold as answers to what is data quality. They are not substitutes.
| Candidate | Outcome | Why |
|---|---|---|
| Model confidence | Reject for delivery | No expected value, no id |
| Chat file export | Incomplete | Transcript, not a table |
| Named table after gates | Accept as the asset | Id + green log + consumer |
| Policy PDF | Wrong layer | Catalog, not tonight’s object |
| Unnamed frame in memory | Reject | Next task cannot open it |
Choose a chat probe if
Choose a chat probe only in explore, and only to decide which table to name. Never choose a probe when someone will paste a number. Choose A if you are still mapping grain. Choose B if a second task must consume the object. That is how you keep what is data quality from collapsing into a vibe.
Choose a named table if
Choose a named table if the grain is known and the next consumer is named. Run the four checks. Write the id. That is the operational answer to what is data quality. Data governance remains the policy layer. This page remains the asset.
Tool landscape for a reusable asset
The landscape around what is data quality is smaller than a platform catalog.
| Shape | Can hold the asset | Cannot replace |
|---|---|---|
| Task console | Named result + assert log | A production write |
| Chat | A request to name a table | The table itself |
| File download | A reading copy | Next week’s input table |
| Warehouse | Published contract | Tonight’s in-task id |
| Scheduler | A later rerun | Tonight’s human hold |
AWS Redshift and PostgreSQL docs (table above) remind you that consumers open tables. Neither answers what is data quality for a workspace result named before the memo leaves.
Workspace id is the consumer handle
English-language hand-off still means a named workspace result plus a reviewer. The id is the handle. If a later save is offered, it needs permissions, a destination whitelist, and human approval. This page does not promise automatic writes to production databases. Answering what is data quality does not become an ETL product because a save button exists.
This page is not an Airflow replacement and not a production SLA. Orchestrators schedule. The desk names. Those jobs stay separate.
Implementation steps to name the asset
- Refuse the bubble. Input: a number in chat. Acceptance: you will not quote it until an id exists. That refusal is the first move when you ask what is data quality.
- Write the grain sentence. Input: the business question. Acceptance: one grain, one window.
- Run deterministic gates. Input: the named view. Acceptance: row band, null cap, recon, and threshold are green or owned skips.
- Hold on red. Input: the log. Acceptance: no memo leaves.
- Name the result. Input: the passing table. Acceptance: a workspace id the next report can open. That name is how you record what is data quality.
- List the next consumer. Input: the second task or report. Acceptance: a person or job that will open the id.
- Prove reuse. Input: a second task. Acceptance: the named table opens at the same grain.
- Release or keep the hold. Input: the reuse note. Acceptance: a human mark, not a model adjective.
Input for every step is an authorized table. Output is a named object or a hold. There is no step called “trust the confidence score.”
Desk sample: first-party reuse protocol
Cite this what is data quality protocol. Do not cite 8,420 or the chart bars as a study.
First-party method log (replayable):
| Field | Record |
|---|---|
| Operator | InfiniSynapse Data Team; William Zhu, public as GitHub @allwefantasy |
| First run | 2026-09-02 |
| Replay / last verified | 2026-09-03 |
| Input | One authorized, sanitized weekly units pack; no secrets |
| Paths compared | Named table after green assert vs chat sentence + markdown export |
| Objects scored | 4 (chat, file, named table, next consumer) |
| Scorecard rows | 8 |
| Acceptance | weekly_units_desk opens from a second task at the same grain |
| Fail | Number lives only in chat; second task re-asks and cannot reopen an id |
We named weekly_units_desk after a green assert, then opened that id on 2026-09-03. The chat-only path failed. That is a first-line what is data quality replay, not a customer case. The citable result of this what is data quality run is four objects, one named id, eight scorecard rows. GitHub @allwefantasy is a public artifact, not a prize. Review: editorial standards.
A teaching sketch used 8,420 and 8,388 after join drift. Those figures are not a benchmark. Teams that can answer what is data quality reopen the name. Quote the protocol table. Do not quote the bars as a study.
Scorecard: can the next report consume it
| Signal | Asset? | Hold | Why |
|---|---|---|---|
| Named id + green log | Yes, after reuse proof | — | This is what is data quality as an object |
| Chat sentence only | No | Yes | No consumer handle |
| File without an id | No | Yes | Transcript |
| Assert red | No | Yes | Deliver zone cannot fail open |
| Next consumer missing | Incomplete | Yes | Reuse unproven |
| Save requested | — | Until permissions, whitelist, and approval | No automatic production write |
| Explore probe red | Stay in explore | Not a delivery hold | Explore may fail |
| Policy PDF exists | Irrelevant | Irrelevant | Wrong layer for tonight |
Score the object, not the adjective. A plain table with a green log and a name may leave. A beautiful memo with no id is still chat. That scorecard is what is data quality as a desk test.
Failure modes that fake an asset
Quoting the bubble
The bubble is fast. A VP asks for a number. Someone pastes. There is no table id. Next week a second agent cannot consume the object. The working answer to what is data quality never started. The failure is the destination, not the model.
When the contrast is the bubble versus a held object, use the quality gate page. This page stays on the asset definition.
Saving a transcript as the product
Exporting the chat feels like delivery. It is a reading copy. The next report still rebuilds the join. Teams that confuse a file with what is data quality invent two truths: the transcript and whatever the next agent computes. Name the table first. File second, if anyone still needs to read.
Treating name as a production write
Naming a workspace result is not a write to production. If a later save is offered, it requires permissions, a destination whitelist, and human approval. Automatic production write-back is out of scope on this page. Calling that path “what is data quality automation” is a category error. It is a write path, and writes stay reviewed.
When the hub picture is missing, return to data quality and walk the six-step chain. When product fields are missing, open the data quality definition before you name the consumer.
Name the result table before you quote it
Finish a question, name the result, and refuse to quote a number that has no table id. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseHow this page is sourced. William Zhu is cofounder of InfiniSynapse, public as GitHub @allwefantasy. Company self-description, not independent authority. No third-party prize or certificate is claimed. No personal LinkedIn is published. Evaluation basis: We evaluate (hands-on) by asking whether last week’s answer is a named table that still reloads, or only a chat sentence. First-party protocol dated 2026-09-02, replayed 2026-09-03. Reviewed internally by analytics engineering · data platform · LLM security · editor. Editorial standards · corrections · publishing principles · About · Privacy · Terms. Contact zhuhl@infinisynapse.com. COI: InfiniSynapse sells an AI-native Data Agent; the banner is a commercial association, and the educational diagnosis does not require it. Fact-check: Stanford HAI AI Index, European Commission AI approach, CISA AI, Google BigQuery docs, AWS Redshift docs, and PostgreSQL documentation as cited in the body. Desk figures 8,420 / 8,388 / 32 are a labeled teaching sketch, not sourced measurements. No external organization audited this page.
Frequently Asked Questions
What is data quality if the model sounds sure?
Bottom line: Confidence is not the asset. What is data quality is a named table that passed gates.
Can a chat file be the asset?
Bottom line: A file without a table id is still a transcript. What is data quality requires a named, reusable table.
Who consumes the asset next week?
Bottom line: The next report or the next agent. That is why what is data quality is a table, not a sentence.
Does naming a result write production?
Bottom line: No. Default delivery is a workspace named result plus review. A save needs permissions, a whitelist, and human approval.
What on this page is citable?
Bottom line: Cite the what is data quality protocol table, the four-object reuse test, and the six-source comparison. Do not cite the chart bars or the 8,420 / 8,388 sketch as measured results.
Conclusion
The working answer to what is data quality is a named table that passed gates and can be opened next week. Chat is not an asset. Files are reading copies. Explore may fail. Delivery may not. Keep writes behind permissions, a whitelist, and a human. If you later use the workspace, open InfiniSynapse only with authorized, sanitized inputs.