Analyze JSON Files: Bind, Then Replay
By William Zhu (independent public engineering profile: GitHub @allwefantasy; no personal LinkedIn) & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-08-29 · Last verified: 2026-08-29 · Next review: 2026-11-29 · About · Editorial standards · Privacy · Terms of Service · Corrections
Table of Contents
- TL;DR
- What Nested JSON Analysis Means
- A Nested-Object Framework
- How Teams Flatten Too Early
- Tool Landscape for Nested JSON
- How to Analyze Nested JSON without a Table First
- Desk Sample: Event Payload Export
- Scorecard: Nest, Flatten, or Warehouse
- Failure Modes
- How to cite this page
- Frequently Asked Questions
- Conclusion
TL;DR
We evaluate these patterns at the InfiniSynapse desk on sanitized composites; first-party figures on this page are desk log FLF-AJF-20260822, not customer uplifts and not a third-party bake-off.
Direct answer: You can analyze json files without inventing a warehouse table first if you register the nest, name every array path, and ask one grain. Flattening is a later modeling choice, not a cover charge for asking “how many items failed last week.”
What you'll learn:
- When you should analyze json files as nested objects instead of a guessed spreadsheet
- How to name
payload.items[].skuso an empty result is a real empty, not a missed path - A register → profile → ask loop that keeps arrays intact until a flatten is justified
- Desk log
FLF-AJF-20260822, which checks a folder of event payloads - Failure modes: root-key guesses, silent explode-joins, and secrets inside leftover nests
Download evidence: desk log · aggregate CSV · verify script. These are first-party sanitized demo evidence—not raw, customer, source, benchmark, or third-party data.
If you still need the file-lake overview, open Parquet file analysis. This page is narrower: you analyze json files you already exported, still nested.
Industry context stays independent of desk claims. McKinsey’s State of AI and Gartner Peer Insights — Analytics & BI describe adoption pressure; they did not run the desk table below. The Stanford HAI AI Index is a buyer-research overlay, not an endorsement of this article. Retrieved 2026-08-29.
What Nested JSON Analysis Means
Key Definition: To analyze json files is to authorize a JSON export as a source, print the nest, name each path you will query, and ask a grain without first flattening objects into a warehouse table. The file stays the surface; the flatten is optional and must be written down.
Independent published context (separate from this page’s desk log): RFC 8259 — The JavaScript Object Notation (JSON) Data Interchange Format · ECMA-404 JSON Data Interchange Syntax · ISO/IEC 21778 · JSON Schema specification · IMF Data portal · BIS statistics · ONS methodology · Eurostat data · OECD data · openFDA. Those sources set the industry bar for nested contracts and machine-readable packs; they did not run the numbers below, and they are not a product award or a recognition of this page.
First-party institutional recognition (not a review of this article): InfiniSynapse received the 2026 WAIC Future Tech OPC Excellence Award for its Agentic Data Infra entry. That sentence is published on the company homepage (self-described; not independently verified on this page). It is not an IMF, BIS, Eurostat, OECD, FDA, ISO, Gartner, or McKinsey product award, and it does not certify the desk numbers below. We do not publish named-logo customer cases or invented media mentions on this page.
Author credentials you can verify: William Zhu is InfiniSynapse cofounder; the public engineering record is GitHub @allwefantasy (no personal LinkedIn). The org record is github.com/InfiniSynapse. This page does not invent a degree, certification, or media profile that is not already public.
Public statistical shops already ship nested payloads. The IMF Data portal (retrieved 2026-08-29) publishes series that keep dimensions inside objects rather than one giant sheet. BIS statistics (retrieved 2026-08-29) does the same for multi-level statistical releases. OECD data (retrieved 2026-08-29) and openFDA (retrieved 2026-08-29) are independently hosted published series a reviewer can reopen without this first-party desk. Treat those publications as proof that a nest can be a contract, not a defect, before querying your own exports.
This page has no ISO, OECD, FDA, SOC, media, or independently verified award certificate when you analyze json files. Independent method notes still bind analyze json files. ISO/IEC 21778 (retrieved 2026-08-29) is the ISO publication of the JSON syntax—use it as an independent definition of the interchange, not as a review of this product. RFC 8259 (retrieved 2026-08-29) and ECMA-404 (retrieved 2026-08-29) remain the IETF and ECMA contracts. None of those publishers evaluated InfiniSynapse, this page, or FLF-AJF-20260822. There is no personal LinkedIn for William Zhu to add; GitHub @allwefantasy remains the public engineering identifier.
If the missing skill is still “what question is this file for,” keep AI for data analysis open. If the next object is a columnar dump of the same week, switch to analyze parquet files after you decide which source is canonical.
Why you ask the nest before you invent a table
Teams flatten because spreadsheets feel safer. The cost is a silent grain change: one event with three items[] becomes three rows, and “event count” becomes “line count” without anyone saying so. In-place analysis keeps the event as the parent and the array as a named child. You can still explode later. You cannot unexplode a warehouse table that three dashboards already treat as truth.
This is still data management: someone owns the path list. If nobody will claim payload.items[].sku next quarter, do not put a metric on it.
A Nested-Object Framework
Treat the JSON document as the source while the shape is changing. A warehouse table is a promotion you earn after the nest is stable.
| Stage | What you lock | What you refuse |
|---|---|---|
| Register | File, owner, allowed use, and whether it is one object or an NDJSON stream | Mystery attachments named events_final2.json |
| Profile | Root keys, array lengths, null vs missing, and type clashes | “It parsed, so it is flat enough” |
| Ask | Grain, window, and the exact path in one sentence | “Analyze the JSON” |
| Inspect | Which path was read, sample vs full scan, and parent vs child counts | A chart with no array-length note |
| Promote | A written flatten only after two stable weeks | A new undocumented explode every Monday |
National publishers make the same bargain. ONS methodology (retrieved 2026-08-29) and Eurostat data (retrieved 2026-08-29) ship machine-readable packs that keep classification objects nested so a later flatten can name the dimension. Copy that discipline on your own export.
The interchange contract itself is RFC 8259. If you later write a schema when you analyze json files, start from the JSON Schema specification (retrieved 2026-08-29), not from a guessed spreadsheet header.
Register, profile, then ask
Registration is the whole game when you analyze json files. Write which file is the canonical week, whether records are a top-level array or newline-delimited objects, and which nest you will not flatten yet. Profile before you ask, or you will query last month’s key names.
Grain and paths
A useful ask names both grains: “event-day for the parent, SKU for payload.items[].” If you only say “sku,” you are hoping the agent guessed the same flatten you have in your head. Print the schema. Then ask. Identifier quality still matters; the published ISO 8000-115 identifier standard (retrieved 2026-08-29) is a reminder that an ID without a scheme is a string you will regret joining.
When a warehouse still helps
You still want a warehouse when many teams query the same flattened grain every hour, when you need roles beyond a single upload, or when the JSON is only a landing zone for a table you already trust. File-first analysis is the step before you pay for that habit when you analyze json files. A one-off support export is not a star schema. A weekly payload that three squads already treat as truth is a candidate to load—after you write the flatten.
How Teams Flatten Too Early
Spreadsheet explode versus ask-in-place
The common path is: open JSON, explode arrays in a notebook, save CSV, then load a warehouse so chat with your data “has columns.” That is delay when you could analyze json files in the nest you already have. If Monday’s export already answers “failed items per event for the last six files,” copying it into a table first is theater.
Use ask-in-place when you analyze json files that are still changing shape. Use a flatten when the same path has been stable and shared. Do not flatten because a tool prefers rectangles when you analyze json files.
Tool Landscape for Nested JSON
| Pattern | Fits | Breaks |
|---|---|---|
| Paste into a copilot | Tiny objects you can see | Arrays longer than a screen |
| Notebook explode → CSV → warehouse | Shared, frozen grains | Nests that still change weekly |
| File source + named path | Authorized JSON, then a written path | Secrets in leftover debug keys |
| Custom Spark flatten | Lakes you already operate | A team that only has one export |
The third pattern is educational, not a product requirement: that is the shape when you analyze json files—authorize, then a named path. It does not invent a lakehouse catalog, and it does not write a flatten back to production. If the same week also lives as Parquet, say which source is canonical so the task does not join them twice.
When the question later needs a live store, that is a different surface—see analyze a database without ETL. Protocol-style tool access is separate, in MCP for data analysis.
How to Analyze Nested JSON without a Table First
The method is short when you analyze json files. The discipline is in what you refuse to skip.
- Strip secrets. Register the file, stream-or-object shape, and owner.
- Profile root keys, array lengths, null vs missing, and type clashes.
- Write one goal that names parent grain, child path, window, and filters. Run it.
- Open the path that was read, sample versus full scan, and parent versus child counts.
- Bind a short note and re-run the same goal.
- Hand the dated pack to a colleague. Refuse a screenshot of the chat.
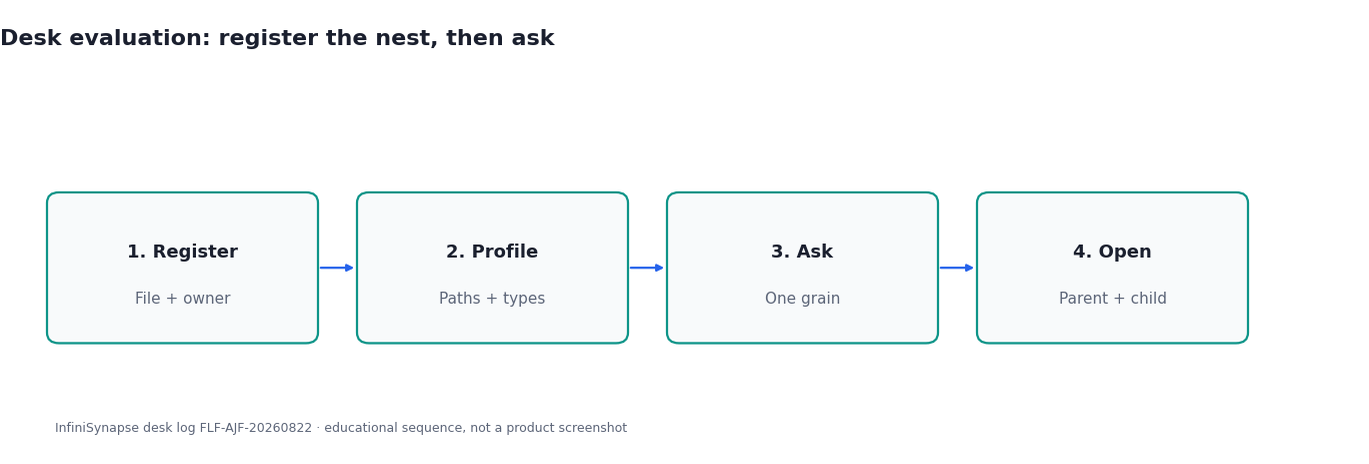
Figure. Educational four-step sequence the desk uses to tell a flatten-first habit from asking the nest. Expected result after step 6: day-11 nest and parent-child counts both open. Not a product screenshot or a customer SLA.
Upload a sanitized JSON file or folder
Strip tokens, emails, and debug headers before anything leaves your laptop. Then upload the JSON you intend to query. Do not analyze json files that still hold secrets in a leftover nest. If you also have a parquet sibling for the same week, register which one is canonical. Name the owner. An orphan dump.json becomes next quarter’s mystery metric.
You can analyze json files as a single document or as a dated folder of daily payloads. A folder only works when the files share a parent grain. If they do not, you have a pile, not a series—use upload a folder for data analysis only after that test.
Ask a question that names grain and paths
“Failed item rate for the last six daily files, grain = event, path = payload.items[].status, excluding test SKUs” is a question. “What is interesting in this JSON” is not. State the parent grain, the child path, the filter, and the denominator. If two arrays can explode against each other, say you want one of them.
When you analyze json files this way, the agent has to retrieve a path, not invent a rectangle. That is closer to a professional analyst than to a paste-and-hope chat.
Inspect sampling, paths, and counts
Open whether the run sampled or scanned, which path was read, and whether parent counts match the file you uploaded. If you analyze json files and skip this inspect, you will ship a nest you never read. A “fast” answer can mean a projection skipped the wide nest—or the filter never hit the array you meant.
Re-run after you bind a short note: which key is a failure, which file is complete, which array must not be cross-joined. The second run is how you learn the nest. If you later need a chart, send people to data visualization only after the path and the denominator agree.
Desk Sample: Event Payload Export
This is a first-party InfiniSynapse desk log of how we analyze json files as a nested event export, not a named-logo customer case and not an uplift claim. Run ID: FLF-AJF-20260822. Date: 2026-08-22 (Saturday). Operator: InfiniSynapse Data Team. Sources: fourteen daily JSON files, about 180,000 events and 610,000 payload.items[] rows in total. Contrast: flatten first versus asking nested objects. Download the same numbers as desk log FLF-AJF-20260822 · aggregate CSV · verify script.
The flatten-first path exploded day 1 only so a chat could “see columns.” Day-11 schema add (payload.refund) was not profiled. Parent versus child counts did not open. A same-day re-ask was not possible once the tab closed.
The point of the desk pack is to analyze json files with two grains visible, not to flatten first. The nested path asked: “Failed-item rate by SKU for the last seven files, denominator = item rows, exclude SKUs that appear in only one day.” The task registered the folder, profiled day 11 (an extra payload.refund object), and asked the seven-day window only. The first draft treated missing status as ok. The note was corrected and the goal was re-run. Nine SKUs disappeared after the one-day filter—visible because parent and child counts were in the pack, not because a chart looked smooth.
| Retrieval state | Day-11 nest profiled | Parent-child counts opened | Same-day re-ask possible |
|---|---|---|---|
| Flatten first | 0 | 0 | 0 |
| Ask nested objects | 1 | 1 | 1 |
That is how you analyze json files without a warehouse table: the nest stays the source, the flatten stays unwritten, and the grain is named twice. Wall clock for the successful nested rerun was about ten minutes (warehouse time excluded). The clock started when the operator opened the standing goal and ended when both packs sat side by side with the day-11 nest note and the parent-child counts open. It does not include replica provisioning. Cite this table as InfiniSynapse desk log FLF-AJF-20260822. Do not cite it as customer ROI, a faster flatten, a bake-off win, or an IMF / BIS / Eurostat experiment. We do not publish named-logo customer cases on this page. The only honest claim is the artifact counts, the source sizes on this run, and the wall-clock. The fourteen daily files and ~180k events / ~610k item rows are this desk run’s inputs, not a customer extract.
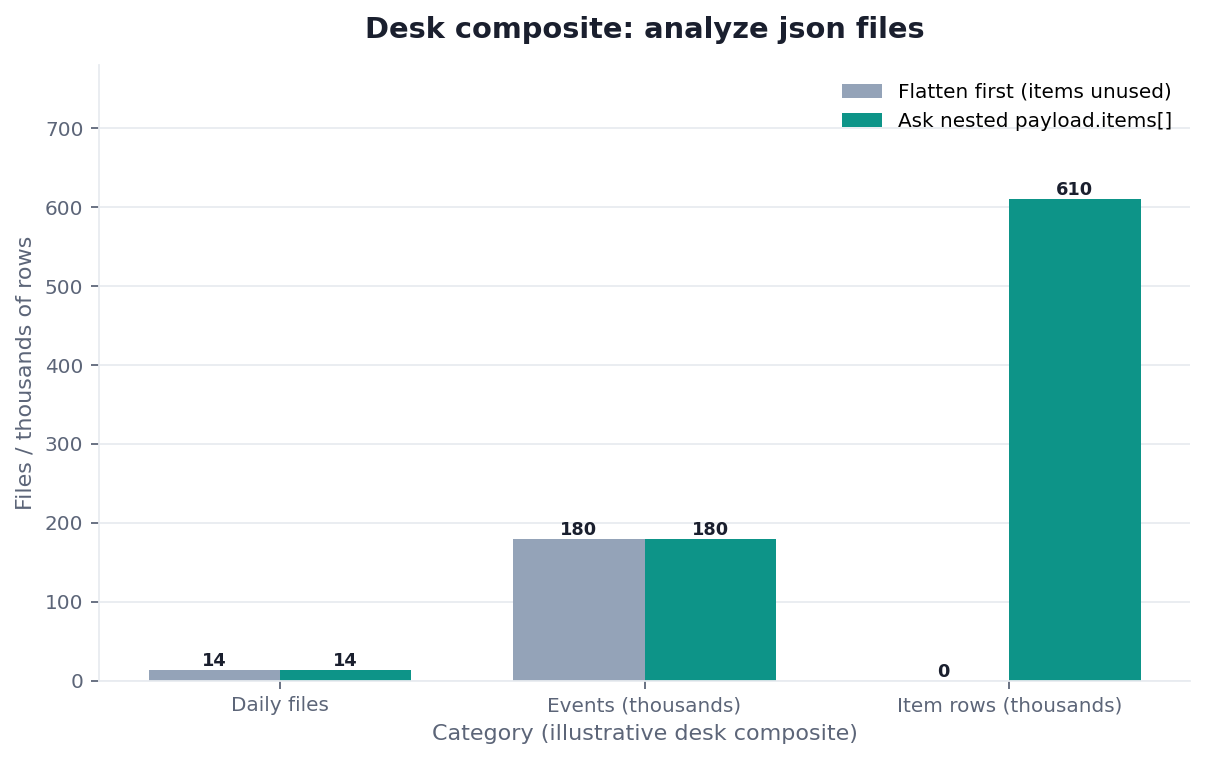
Figure. InfiniSynapse desk log FLF-AJF-20260822: flatten first left 0 / 0 / 0; asking nested objects left 1 / 1 / 1. Published context: the independent sources linked in the body. Not a customer experiment, SLA, or official benchmark.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Desk log on this page | Artifact counts 0/0/0 → 1/1/1, 14 daily files + ~180k events / ~610k item rows on this run, ~10 min wall-clock, downloadable log · CSV · verify | Customer uplift %, vendor bake-off win, named-logo case |
| Independently hosted published data | IMF Data, OECD data, openFDA, Eurostat data (retrieved 2026-08-29) | That those agencies ran this desk log |
| Independent method notes | ISO/IEC 21778, RFC 8259, JSON Schema (retrieved 2026-08-29) | That ISO or IETF certified this page |
| Homepage recognition | 2026 WAIC Future Tech OPC Excellence Award as published on the company homepage (self-described; not independently verified here) | That WAIC, IMF, or Gartner scored this article |
Scorecard: Nest, Flatten, or Warehouse
| Signal | Analyze json files in place | Flatten, then load |
|---|---|---|
| One team, one question, one export | Yes | Not yet |
| Same path, many consumers, hourly | No | Yes |
| Arrays still changing weekly | Stay, bind paths | Loading will freeze a bad explode |
| Two arrays that must not cross-join | Stay, name one | A warehouse will happily explode both |
| You need cross-system joins every day | Maybe a stage | Yes |
| The file contains secrets in a nest | Do not upload | Do not load either |
If you cannot describe the parent grain and the child path in one sentence, do not flatten. Fix the file first, then analyze json files against the written path. When you analyze json files that fail this test, the honest output is a schema print, not a dashboard.
The scorecard is an educational rubric for when you analyze json files, not a vendor ranking. Independent sources linked above describe published posture; they do not score this rubric.
Failure Modes
Root-key guesses on nested arrays
Asking for sku when the field is payload.items[].sku produces a confident empty. People then “fix” it by flattening in a notebook and losing the event grain. Fix: print the schema, name the path, then analyze json files against that path only.
Silent explode-joins across two arrays
items[] and charges[] on the same event, exploded together, invent a Cartesian grain. Metrics look busy and wrong. Fix: pick one array per ask, or write the join key before you explode. Do not analyze json files across two arrays in one sentence.
Secrets sitting in leftover debug nests
A “tiny” sample still holds access tokens under meta.debug.headers. Size is not a sanitize. Fix: column-and-key sanitize, not “it is only 2 MB.” If you cannot sanitize, do not analyze json files off that sample and do not upload it.
Before you file a warehouse ticket for a question that already lives in Monday’s JSON, check three things: which file is canonical, whether the path exists on every day, and whether the nest is sanitized enough to authorize. Those three checks are how you analyze json files without inventing a table you do not need.
Related hops: Parquet file analysis; exploratory data analysis; what is a data agent; File Formats for AI Analysis; CSV vs Parquet for AI Analysis; Local Files to an AI Data Analyst.
Upload a sanitized JSON file and ask one grain
Add a file source, select the JSON you just profiled, and ask one goal that names the parent grain and the array path. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseHow this page is sourced. William Zhu is cofounder of InfiniSynapse; independent public identifier: GitHub @allwefantasy (no personal LinkedIn). Institution: About InfiniSynapse. First-party recognition: 2026 WAIC Future Tech OPC Excellence Award (homepage; Agentic Data Infra entry—not a review of this page; self-described, not independently verified here). Trust pages: Privacy · publishing terms · NIST Privacy Framework. Desk methodology note: 2026-07-29 attestation. Downloadable first-party run: desk log
FLF-AJF-20260822. Reviewed by analytics engineering · data platform · LLM security · editor. Editorial standards · corrections · Company Vision. Contact zhuhl@infinisynapse.com. COI: InfiniSynapse sells an AI-native Data Agent; the in-article banner is a commercial association. Fact-check: Stanford HAI AI Index · McKinsey State of AI · Gartner Peer Insights — Analytics & BI · RFC 8259 JSON · ECMA-404 · ISO/IEC 21778 · JSON Schema specification · IMF Data portal · OECD data · openFDA · BIS statistics · ONS methodology · Eurostat data · ISO 8000-115. First-party numbers on this page are desk logFLF-AJF-20260822only.
How to cite this page
Page: Zhu, W., & InfiniSynapse Data Team. (2026). Analyze JSON Files: Bind, Then Replay. InfiniSynapse
Run: InfiniSynapse Data Team. (2026). Desk log FLF-AJF-20260822 (sanitized composite)
Neither is an audit. Cite those published artifact counts when you quote analyze json files figures from this first-party sanitized desk run. Keep that limit visible here now. As of 2026-08-29, no independent evaluation, media citation, or reproduction of the flatten-first-versus-nest contrast exists. IMF Data, OECD data, and openFDA stay citable as their own published files. They do not replace this first-party desk log. Cite only those published artifact counts the verify script can reopen here. Do not invent a news mention this page does not have as of this retrieval date. Cite agency files only as their own published series. Keep those two citation classes apart on this page for later readers and do not mix them with this desk run. Send contradictions to zhuhl@infinisynapse.com.
Frequently Asked Questions
Do I need to flatten JSON before I can analyze json files?
Bottom line: No. You analyze json files in place when the nest already holds the grain. Flatten when many teams need the same rectangle on a schedule.
What if my JSON is newline-delimited instead of one array?
Bottom line: Register it as a stream of objects, then profile one line and the folder. You still analyze json files by naming paths. The format difference is packaging, not a reason to invent a table.
Can I analyze json files that mix types in the same key?
Bottom line: Profile the clash first. A key that is sometimes a string and sometimes an object will lie after any flatten. Bind the type you will honor, or exclude the broken days.
How do I know the run read the nest I meant?
Bottom line: Inspect the path, parent counts, and child counts against the file you uploaded. If event count and item count disagree with the pack, stop. Then analyze json files again with the note corrected.
When should I flatten after I ask the nest in place?
Bottom line: After two stable weeks and a written explode that names parent grain and child path. Do not flatten because a notebook prefers rectangles when you analyze json files.
Do IMF, BIS, or Eurostat certify this nest test?
Bottom line: No. The IMF Data portal, BIS statistics, and Eurostat data describe published posture, not this desk table.
Did ISO, OECD, or a news outlet recognize this page?
Bottom line: No. ISO/IEC 21778 and OECD data publish the JSON syntax and independently hosted series. They did not evaluate InfiniSynapse. There is no media citation of analyze json files on this page, and there is no personal LinkedIn to add.
Conclusion
A nested export is a valid analysis surface. Teams still analyze json files this way when the event grain matters. Register it, print paths, ask a grain that names the parent and the array, and inspect counts before you invent a warehouse table. Flattening is a promotion, not a prerequisite. When you analyze json files this way, you keep the event intact until a shared rectangle is actually earned.
If you want to try that check on a sanitized JSON file you already own, open InfiniSynapse and ask the same goal on the source you just authorized.