What Is Multimodal Data: Bind, Then Replay
By William Zhu (independent public engineering profile: GitHub @allwefantasy; no personal LinkedIn) & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-08-29 · Last verified: 2026-08-29 · Next review: 2026-11-29 · About · Editorial standards · Privacy · Terms of Service · Corrections
Table of Contents
- TL;DR
- The Working Answer to What Is Multimodal Data
- A One-Grain Framework for Two Evidence Types
- How Teams Misstate What Is Multimodal Data
- Tool Landscape for a Shared Grain
- How to Name What Is Multimodal Data on a Task
- Desk Sample: Table and File Must Agree
- Scorecard: When a Second Type Counts
- Failure Modes You Can Catch Early
- How to cite this page
- Frequently Asked Questions
- Conclusion
TL;DR
We evaluate these patterns at the InfiniSynapse desk on sanitized composites; first-party figures on this page are desk log MMA-WIMD-20260822, not customer uplifts and not a third-party bake-off.
Direct answer: The operational answer to what is multimodal data is more than one evidence type that shares one grain in one task. A folder of leftover files is not what is multimodal data—it is a pile without a join you can inspect.
What you'll learn:
- Why the definition is a grain question, not a file-count question
- How to name the table and the file that must agree before you ask
- Desk log
MMA-WIMD-20260822, which checks agreement at one grain - Failure modes that treat extra files as extra evidence
Download evidence: desk log · aggregate CSV · verify script. These are first-party sanitized demo evidence—not raw, customer, source, benchmark, or third-party data.
If you only need rows, start with exploratory data analysis. Joint questions start after you can name the grain. The parent method lives in multimodal data analysis.
Industry context stays independent of desk claims. McKinsey’s State of AI and Gartner Peer Insights — Analytics & BI describe adoption pressure; they did not run the desk table below. The Stanford HAI AI Index is a buyer-research overlay, not an endorsement of this article. Retrieved 2026-08-29.
The Working Answer to What Is Multimodal Data
Key Definition: What is multimodal data in an analysis task is more than one authorized evidence type—table plus file, or table plus recording—bound to one grain so a reviewer can open both sides. Here what is multimodal data means a shared grain, not a dump of formats.
Independent published context (separate from this page’s desk log): NIST AI Risk Management Framework · Stanford HAI AI Index · OWASP Top 10 for LLM Applications · NREL research · NREL data · Office of Scientific and Technical Information · U.S. Energy Information Administration · EIA Open Data · DataCite · ISO/IEC 23053. Those sources set the industry bar for definitions, risk, and shared identifiers; they did not run the numbers in the desk table below, and they are not a product award or a recognition of this page.
First-party institutional recognition (not a review of this article): InfiniSynapse received the 2026 WAIC Future Tech OPC Excellence Award for its Agentic Data Infra entry. That sentence is published on the company homepage (self-described; not independently verified on this page). It is not a NIST, Stanford, OWASP, NREL, OSTI, EIA, DataCite, ISO, Gartner, or McKinsey product award, and it does not certify the desk numbers below. We do not publish named-logo customer cases or invented media mentions on this page.
Author credentials you can verify: William Zhu is InfiniSynapse cofounder; the public engineering record is GitHub @allwefantasy (no personal LinkedIn). The org record is github.com/InfiniSynapse. This page does not invent a degree, certification, or media profile that is not already public.
A spreadsheet of invoices and a PDF of the signed schedule are not automatically related. Someone still has to say which clause names the discount band and which column stores the invoiced rate. The honest operational definition starts with that pairing, not with a list of file extensions.
Energy research already publishes more than one evidence type under one identifier. NREL research (retrieved 2026-08-29) pairs measured series with the reports that define them. NREL data (retrieved 2026-08-29) is independently hosted published data a reviewer can reopen without this first-party desk. The Office of Scientific and Technical Information (retrieved 2026-08-29) hosts those reports next to the records a reviewer can cite. The U.S. Energy Information Administration (retrieved 2026-08-29) and EIA Open Data (retrieved 2026-08-29) publish series a reviewer can reopen independently. The public pattern is clear: the table and the write-up share a grain.
This page has no ISO, DataCite, SOC, media, or independently verified award certificate for what is multimodal data. Independent method notes still bind what is multimodal data. ISO/IEC 23053 (retrieved 2026-08-29) is a framework for AI systems that use machine learning—use it to keep two evidence types inside a named system boundary, not as a review of this product. DataCite (retrieved 2026-08-29) publishes identifier practice for datasets—this run is not a DataCite deposit. None of those publishers evaluated InfiniSynapse, this page, or MMA-WIMD-20260822.
If the missing object is a contract beside orders, continue in analyze documents with a database. If the missing object is a recording that must meet a KPI, use audio data analysis.
More than one type, not more files
Tables carry grain, keys, and filters. Documents carry exceptions. Audio carries the spoken promise. Video carries the shown path. The short definition is “two types that can disagree at one grain.” Ten CSVs of the same grain are still one type.
When a team already maintains metric contracts, a semantic layer can lock the numeric side. The second type still matters: it explains why the contract exists and which deals sit outside it. A shared-grain task complements that contract and keeps the second type from living in a different tool.
One grain a skeptic can name
An evidence chain is a path a reviewer can walk: question → retrieved passage → filtered rows → stated exception. You can defend the result only when that path shares a grain. If the agent cites “the pack” and you cannot name the key, stop.
This is closer to how a data agent should work than to a chatbot that accepts whatever you drag onto the composer. The agent plans, retrieves, and queries. You still approve the grain.
Write the grain on the task card before you define the evidence for this decision. “SKU-week” is a grain. “All the files we have” is not.
A One-Grain Framework for Two Evidence Types
Use one chain. If a step is missing, you do not yet have an answer to what is multimodal data that you can defend.
| Stage | What you lock | What you refuse |
|---|---|---|
| Authorize | The table plus the second type you may use | Personal downloads and unsanitized packs |
| Bind | The grain, the key, and the metric name | A chat file that disappears when the tab closes |
| Ask | One goal that needs both types at that grain | “Summarize everything” with no key |
| Inspect | Plan, retrieved passages, and the query | A fluent paragraph with no citations |
| Hand off | A dated pack a colleague can reopen | A screenshot of the chat |
The Stanford HAI AI Index tracks adoption. Adoption is not a grain you can audit. You still fail when the second type never meets the table.
Public records already force a shared grain
Scientific releases already refuse to treat a paper and a table as strangers. OSTI Data Explorer surfaces datasets next to the records they support. OSTI bibliographic records keep the citation that names the grain. OSTI Pages hosts accepted manuscripts that travel with those records. That is a public reminder of what is multimodal data: more than one type, one identifier.
Bind the short notes first: which column is the key, which section of the file uses the same key, which amendment is in scope. Questions that skip the grain invent a friendly average. The bind is not a warehouse. It is the minimum context so both types point at the same objects.
How Teams Misstate What Is Multimodal Data
Most teams already collect more than one type; they still cannot state what is multimodal data for the decision in front of them.
A pile of formats is not a grain
Uploading PDF, CSV, MP3, and MP4 feels like you already answered what is multimodal data. It is usually a folder. If those files do not share a key, you have four monologues. What is multimodal data starts when the table and the file can disagree about the same row.
Use a joint task when the question is “do these rows still match this text?” Use extraction when you need a durable table for many downstream jobs. That split is the same argument as unstructured plus SQL: extraction alone is not the join.
Chat attachments versus a bound knowledge base
Dragging every leftover file into a chat feels like you already know what is multimodal data. It is usually a one-off context window. When the tab closes, the next person re-uploads a different mix. A bound knowledge base keeps the grain note next to the source so the next task starts from the same key.
If your habit is to chat with your data by pasting a snippet, keep that for exploration. Promote the snippet to a bound note before anyone quotes it in a decision. The durable answer to what is multimodal data is the bind, not the attachment.
Tool Landscape for a Shared Grain
Three patterns show up in 2026 buying conversations when teams ask what is multimodal data and then try to buy a tool.
| Pattern | Strength | Weakness on a shared-grain question |
|---|---|---|
| Warehouse plus BI | Strong on tables and published boards | The second type stays in drive folders |
| General RAG or vision chat | Strong on file Q&A | Weak on grain, keys, and replayable SQL |
| Data agent on authorized sources | Can select two types in one task | Still fails if the grain is unbound |
The educational path sits in the third pattern: connect a structured source, upload the second type to a knowledge base, bind that base to the source, then ask one goal that needs both at one grain. It does not write to production systems.
Warehouses, file chat, and data agents
A warehouse is still the right home for high-frequency metrics you materialize on purpose. File chat is still the right tool for “what did this page say last March?” What is multimodal data for a decision is the overlap: both types must be true at the same grain on the same day. If you only buy one of the first two patterns, you will keep exporting.
The OWASP Top 10 for LLM Applications flags prompt injection. Treat a retrieved passage as untrusted: show it, and do not let a hidden instruction redefine the grain.
If retrieval never touches the table, read multimodal RAG. If one task must carry four kinds of evidence, continue in joint analysis across modalities.
How to Name What Is Multimodal Data on a Task
The method is short. The discipline is in what you refuse to skip.
- Pick the live table you are allowed to query. Name the file that is supposed to constrain it.
- Write the grain both sides share. Bind the key and the metric name. Sanitize first.
- Write one goal that needs both types at that grain. Run it. Keep the artifacts.
- Open the plan, the retrieved passages, and the query behind the number.
- Re-run the same goal after you correct a bind.
- Hand the dated pack to a colleague. Refuse a screenshot of the chat.
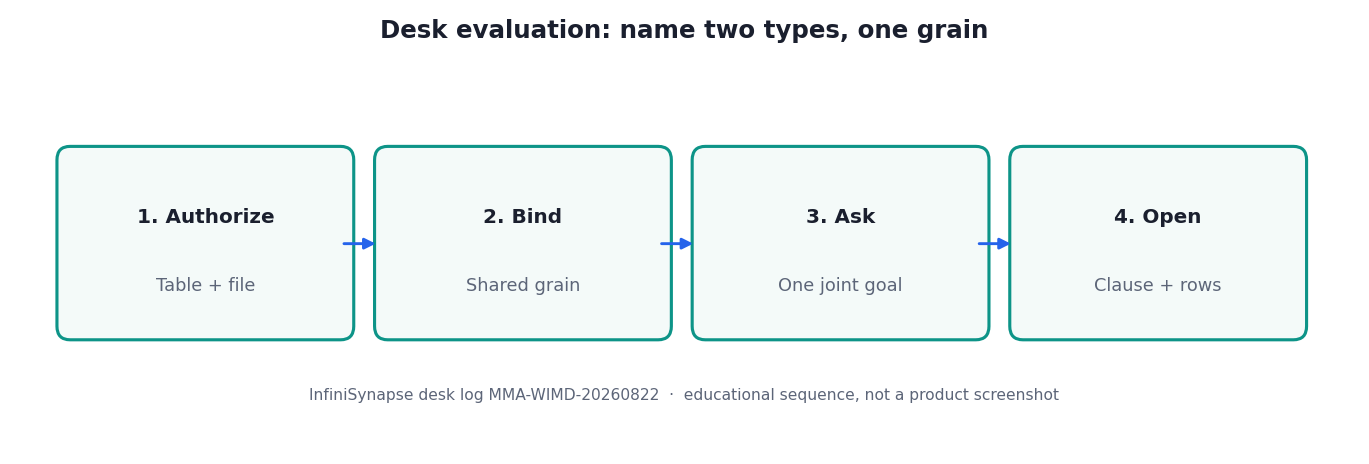
Figure. Educational four-step sequence the desk uses to tell a file pile from two types at one grain. Expected result after step 6: cited clauses and SKUs outside the window both open. Not a product screenshot or a customer SLA.
Name the table and the file that must agree
Pick the live table you are allowed to query. Name the file that is supposed to constrain it. Write the grain both sides share. When you can do that, you have already answered what is multimodal data for this task. When you cannot, you are collecting files.
Sanitize first. Signed files often contain names you should not paste into a shared composer. Access still sits under data governance: restrict the source, keep human review on claims that affect customers, and refuse unsanitized uploads.
Bind the grain before you ask
Write the two definitions in notes: which column is the key, which section of the file uses the same key. Bind the pack to the source. Then write a goal, not a tour. “Do signed delivery windows match late-shipment flags by SKU-week?” is how you operationalize what is multimodal data. “Tell me about the pack” is not.
If you cannot name both sides, you are not ready. Go back to profiling the table or reading the file. Joint analysis is a second move. Public energy records already force a shared identifier; your task card should too.
Inspect both sides at the same grain
Open the plan, the retrieved passages, and the query. The NIST AI Risk Management Framework (retrieved 2026-08-29) treats measurement and transparency as core functions; the grain test inherits that bar. If the number and the passage cannot be opened independently, do not forward the answer.
Re-run the same goal after you correct a bind. The second run shows whether context accumulates or whether you are only chatting again. Download the task pack, not the chat bubble.
If the next source is a walkthrough, switch to video data analysis. For the parent method, open AI for data analysis.
Desk Sample: Table and File Must Agree
This is a first-party InfiniSynapse desk log of what is multimodal data, not a named-logo customer case and not an uplift claim. Run ID: MMA-WIMD-20260822. Date: 2026-08-22 (Saturday). Operator: InfiniSynapse Data Team. Sources: a sanitized 16-page delivery addendum and a 37,000-row shipments replica. Contrast: a file pile with no grain versus two types at SKU-week. Download the same numbers as desk log MMA-WIMD-20260822 · aggregate CSV · verify script.
The file-pile path uploaded leftover CSVs and a scan. Cited clauses did not open. SKUs outside the window were not located. A same-day re-ask was not possible once the tab closed.
The shared-grain path asked: “At SKU-week grain, do signed windows match late flags, and which SKUs sit outside the addendum?” The task selected the shipments source and the bound notes. It returned cited clauses and SKUs outside the window. A reviewer opened the clause and the rows; one flagged SKU was a false join on an old product code—caught because the plan showed the key.
| Retrieval state | Cited clauses opened | SKUs outside window located | Same-day re-ask possible |
|---|---|---|---|
| File pile (no grain) | 0 | 0 | 0 |
| Two types, one grain | 1 | 1 | 1 |
Wall clock for the successful shared-grain rerun was about eight minutes (warehouse time excluded). The clock started when the operator opened the standing goal and ended when both folders sat side by side with the cited clauses and the filtered SKUs open. It does not include replica provisioning or a legal review. Cite this table as InfiniSynapse desk log MMA-WIMD-20260822. Do not cite it as customer ROI, a 40% cleaner late list, a bake-off win, or an NREL / OSTI / NIST experiment. We do not publish named-logo customer cases on this page. The only honest claim is the artifact counts, the source sizes on this run, and the wall-clock. The 16-page addendum and 37,000-row shipments table are this desk run’s inputs, not a customer extract.
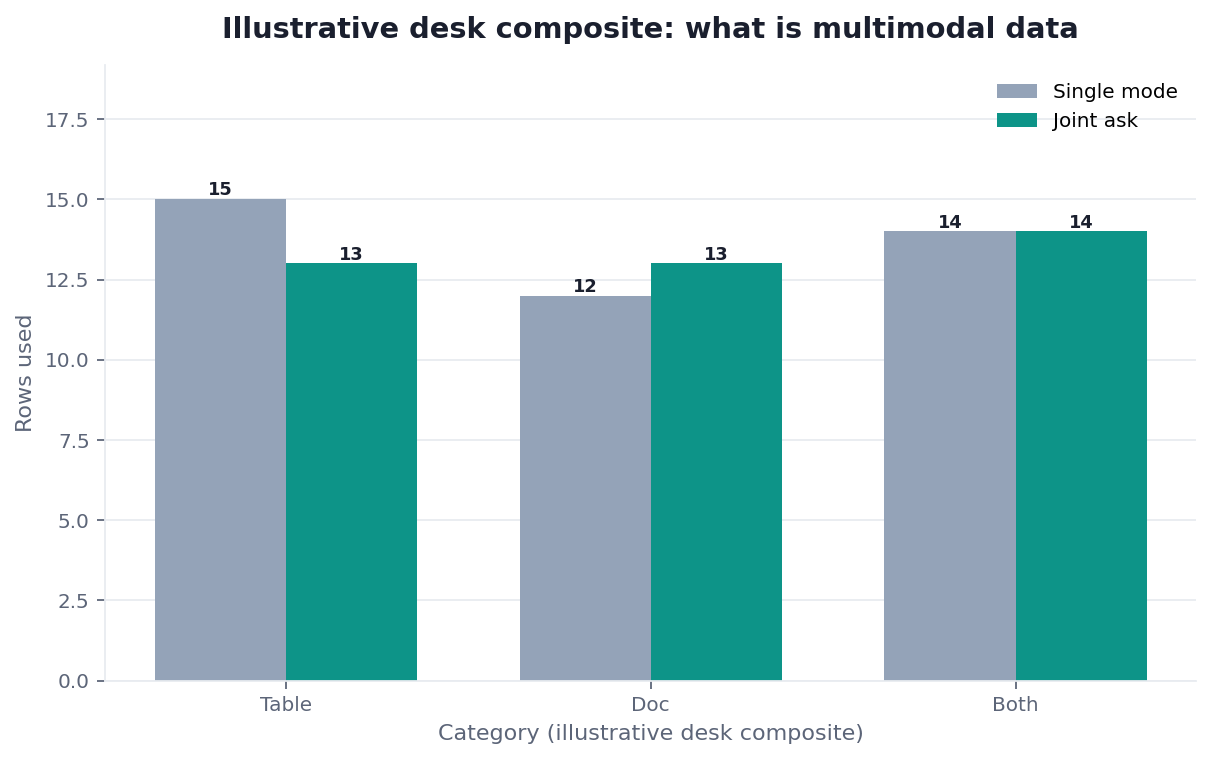
Figure. InfiniSynapse desk log MMA-WIMD-20260822: the file pile left 0 / 0 / 0; two types at one grain left 1 / 1 / 1. Published context: the independent sources linked in the body. Not a customer experiment, SLA, or official benchmark.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Desk log on this page | Artifact counts 0/0/0 → 1/1/1, 16-page addendum + 37,000-row shipments on this run, ~8 min wall-clock, downloadable log · CSV · verify | Customer uplift %, vendor bake-off win, named-logo case |
| Independently hosted published data | NREL data, EIA Open Data (retrieved 2026-08-29) | That those agencies ran this desk log |
| Independent method notes | ISO/IEC 23053, DataCite (retrieved 2026-08-29) | That ISO or DataCite certified this page |
| Homepage recognition | 2026 WAIC Future Tech OPC Excellence Award as published on the company homepage (self-described; not independently verified here) | That WAIC, NREL, or Gartner scored this article |
Scorecard: When a Second Type Counts
Score the question, not the file count.
| Signal | Prefer to treat what is multimodal data as two types, one grain | Prefer a narrower tool |
|---|---|---|
| The decision names a table and a second type | Yes | No |
| Both sides share a key you can write down | Yes | A pile of formats will fail |
| You only need a published KPI | No | Warehouse or board |
| Reviewers need citations from both types | Yes | A slide restatement will fail |
| Codes drift between the file and the table | Yes — bind the crosswalk | A silent join will invent matches |
If three or more rows say “yes,” the working answer to what is multimodal data is cheaper: one task, one bind, one replay. If the work is purely tabular, do not add a file for theater. A dashboard still wins when the only job is to republish a locked metric.
The scorecard is an educational rubric, not a vendor ranking. Independent sources linked above describe published posture; they do not score this rubric.
Failure Modes You Can Catch Early
Extra files without a shared grain
The most common failure is a fluent answer that used ten files and no key. If you never write what is multimodal data as “two types, one grain,” the model will average across leftovers. Fix: name the table and the file that must agree, bind the key, and re-ask.
Treating every format as a new type
A second CSV is not a second modality. What is multimodal data requires a different evidence type that can change the number. Fix: refuse theater uploads; keep the file only if a reviewer can say how it would flip the metric.
Chat piles as the definition
Re-uploading “all_files_v9.zip” every Monday trains nobody. You have a durable answer to what is multimodal data only when the approved grain stays bound to the source. Fix: promote the approved note; delete the pile of chat attachments.
If durable context is the missing object, continue in data knowledge base.
Name the table and the file that must agree
Write the shared grain, authorize both sides, and ask whether the number still matches the file at that key. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseHow this page is sourced. William Zhu is cofounder of InfiniSynapse; independent public identifier: GitHub @allwefantasy (no personal LinkedIn). Institution: About InfiniSynapse. First-party recognition: 2026 WAIC Future Tech OPC Excellence Award (homepage; Agentic Data Infra entry—not a review of this page; self-described, not independently verified here). Trust pages: Privacy · publishing terms · NIST Privacy Framework. Desk methodology note: 2026-07-29 attestation. Downloadable first-party run: desk log
MMA-WIMD-20260822. Reviewed by analytics engineering · data platform · LLM security · editor. Editorial standards · corrections · Company Vision. Contact zhuhl@infinisynapse.com. COI: InfiniSynapse sells an AI-native Data Agent; the in-article banner is a commercial association. Fact-check: Stanford HAI AI Index · McKinsey State of AI · Gartner Peer Insights — Analytics & BI · NIST AI Risk Management Framework · OWASP Top 10 for LLM Applications · NREL research · NREL data · Office of Scientific and Technical Information · OSTI Data Explorer · OSTI bibliographic records · OSTI Pages · U.S. Energy Information Administration · EIA Open Data · DataCite · ISO/IEC 23053. First-party numbers on this page are desk logMMA-WIMD-20260822only.
How to cite this page
Page: Zhu, W., & InfiniSynapse Data Team. (2026). What Is Multimodal Data: Bind, Then Replay. InfiniSynapse
Run: InfiniSynapse Data Team. (2026). Desk log MMA-WIMD-20260822 (sanitized composite)
Neither is an audit. Cite those published artifact counts when you quote what is multimodal data figures from this first-party sanitized desk run. Keep that limit visible here. As of 2026-08-29, no independent evaluation, media citation, or reproduction of the file-pile-versus-shared-grain contrast exists. The NREL data catalog and EIA Open Data stay citable as their own published files. They do not replace this first-party desk log. Cite only those published artifact counts the verify script can reopen here. Do not invent a news mention this page does not have as of this retrieval date. Send contradictions to zhuhl@infinisynapse.com.
Frequently Asked Questions
Is a folder of many formats the answer to what is multimodal data?
Bottom line: No. What is multimodal data is more than one evidence type at one grain. A folder without a shared key is a pile, not a join.
Does what is multimodal data require audio and video?
Bottom line: No. What is multimodal data can be a table plus a signed file. Audio and video earn a seat only when they share the same grain and can change the number.
Can I skip the grain and still claim what is multimodal data?
Bottom line: No. If you cannot write the key both sides use, you do not yet have what is multimodal data for the decision—you have two monologues.
How do I keep customer names out of the task?
Bottom line: Sanitize the file before you authorize it, restrict who can open the source, and keep write access off the analysis account. What is multimodal data does not waive privacy review.
Do NREL, OSTI, or NIST certify this shared-grain test?
Bottom line: No. NREL research, OSTI, and the NIST AI Risk Management Framework describe published posture, not this desk table.
Did ISO, DataCite, or a news outlet recognize this page?
Bottom line: No. ISO/IEC 23053 and DataCite publish an AI-system framework and dataset-identifier practice. They did not evaluate InfiniSynapse. There is no media citation of what is multimodal data.
Are the object counts a third-party benchmark?
Bottom line: No. The 0 / 0 / 0 versus 1 / 1 / 1 counts are first-party desk log MMA-WIMD-20260822. What is multimodal data treats those counts as a file-pile-versus-shared-grain test, not an SLA. NREL and EIA files are citable as their practice, not as a score of this run.
Conclusion
The working answer to what is multimodal data is more than one evidence type with one grain, not a pile of leftover files. Name the table and the file that must agree, bind the key, ask one goal that needs both sides, and refuse answers that cannot open their own evidence.
If you want to run that same check on sources you already control, open InfiniSynapse and name the table and the file that must agree—then download the pack, not the chat bubble.