A/B Test: Guardrails, CUPED, and a Human Call
By William Zhu & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-08-31 · Last verified: 2026-08-31 · Next review: 2026-11-30 · About · Privacy policy · Editorial standards · Corrections
Table of Contents
- TL;DR
- What an A/B Test Must End With
- A Ship-Hold-Iterate Framework
- How Teams Stop Short of the Call
- Tool Landscape for a Signed Memo
- Implementation Steps to the Human Line
- Accuracy and Experience Record: Illustrative Hold after a Primary Win
- Evidence Boundaries and Independent Validation
- How to Cite This Page
- Selection Scorecard for the Last Line
- Failure Modes that Skip the Human Call
- Frequently Asked Questions
- Conclusion
TL;DR
We evaluate these patterns at the InfiniSynapse desk on sanitized composites; sample figures on this page are illustrative, not customer uplifts.
Direct answer: An a/b test is not finished when the interval is green. It ends in ship, hold, or iterate, signed by a named human, after guardrails and optional CUPED are written on the same memo as the SQL.
What you'll learn: why an a/b test is a three-way call; a six-row decision contract; when CUPED is a line and not a rescue; how to keep the design from being patched after freeze; an illustrative checkout hold; and the breaks that treat a chat as approval.
Download evidence: desk log · decision CSV · verification script · source check · reproduction protocol. This package is first-party and illustrative—not customer, production, randomized-trial, benchmark, or third-party evidence.
The hub method is A/B test analysis. This page is narrower: the last line of the comparison, not the first hypothesis.
What an A/B Test Must End With
Key Definition: An a/b test is a frozen randomized comparison that produces a ship, hold, or iterate memo a human signs, with named primary, guardrails, and inspectable SQL. The interval is a line in that memo. It is not the decision.
RFC 8259 (retrieved 2026-09-04) defines JSON. It supports a structured-object analogy but does not define or validate experiments.
For direct statistical guidance, see the ASA Statement on Statistical Significance and P-Values and NIST/SEMATECH e-Handbook of Statistical Methods (retrieved 2026-09-04). Neither source reviewed this run.
The comparison sits next to experiment analysis. That sibling starts with assignment. This page starts at the call you still owe after assignment is clean.
Ship, hold, or iterate is the product
Ship means the primary moved the right way, guardrails did not fail, and the owner accepts residual risk. Hold means you do not launch; the comparison may still be valid. Iterate means you keep the freeze, change a named thing, and run again with the same unit and the same kill metrics.
Natural language to SQL can be the execution path for the join. It is not a replacement for the last line. A memo that “recommends ship” in a bubble has skipped the product.
Do not patch the design after you see the number
JSON Patch (retrieved 2026-09-04) defines document changes. Here it is an analogy for recording design amendments, not statistical authority.
If variance reduction is the next object, continue in CUPED explained. CUPED can tighten an interval. It cannot choose ship.
A Ship-Hold-Iterate Framework
Every decision read should fill this table before anyone sends a launch email.
| Decision row | What you lock | Typical source | Failure if skipped |
|---|---|---|---|
| Action | Ship, hold, or iterate | Memo last line | Chat as approval |
| Owner | Named human | Same memo | Model as policy |
| Primary | One metric, one window | Outcome + note | Metric shopping |
| Guardrails | Named kills, joined or “not measured” | Adjacent tables | Silent harm |
| CUPED | Covariate name or off | Pre-period | Leaking tightness |
| SQL | Downloadable query | /tasks artifact | Slide-only lift |
Decision quality is the filled last line. “Looks good” is not an action. “Iterate on payment retry copy” is an action.
Web Linking (retrieved 2026-09-04) defines web link relations. It is a join analogy only.
How Teams Stop Short of the Call
Teams celebrate the badge. A comparison that stops at the badge still needs the call.
| Stopping place | Looks like progress | Why it is incomplete |
|---|---|---|
| Green interval | “We won” | Guardrail unread |
| CUPED-tight interval | “More confident” | Covariate unnamed |
| Exposed-only lift | “Users who saw it convert” | ITT missing |
| Agent paragraph | “The model says ship” | No owner |
Guardrails that veto a primary win
The comparison can win on checkout completion and still be a hold if refunds or latency move the wrong way. Pre-register those kills. If the join is missing, write “not measured” and consider a hold. Continue in guardrail metrics when the kill object is the gap.
Self-service analytics does not mean a PM ships from a sparkline. The memo still needs a reviewer who can open SQL.
CUPED as a line, not a rescue
Use CUPED on the comparison when a pre-period covariate is correlated with the outcome and the variant cannot change it. New users often have no such history; leave it off. Never apply CUPED to rescue a run you already stopped early. Name the covariate or do not use the method.
Tool Landscape for a Signed Memo
You do not need a new warehouse to finish the call. You need assignment, outcomes, a bound metric note, and a place to keep the memo. A dated CSV is valid if it includes assignment time.
InfiniSynapse can draft the memo on a source you authorize. It is not ChatBI. It does not invent a prebuilt experiment warehouse, and it does not write ship back into production. A data agent owns the trail in /tasks. The human owns the call.
Locale-stable metric names
CLDR (retrieved 2026-09-04) standardizes locale data. It supports a naming analogy but does not validate metric definitions.
Unit grain that does not drift
H3 (retrieved 2026-09-04) is a geospatial index. It is a grain analogy, not experimental evidence.
Data visualization of lift is fine after the call is drafted. Charts are not the signature.
If the artifact shape is the gap, use the experiment decision memo. If horizon math is the gap, use A/B test sample size.
Implementation Steps to the Human Line
Start from the frozen note. An a/b test that starts from “can we ship today” will shop for a metric.
Freeze, then join assignment to outcomes
Write unit, primary, window, and peeking rule. Confirm uniqueness and SRM. An a/b test on a join that uses first-event time instead of assigned_at will manufacture lift. Keep the randomizer’s IDs.
Bind kills and CUPED state before lift
List two or three guardrails. Set CUPED on or off with a named covariate. An a/b test that toggles CUPED after seeing the interval is a peek. Then ask for the memo: primary, interval, guardrails, balance, recommended action, SQL.
Write the call and the owner
The last sentence is ship, hold, or iterate plus a name. An a/b test does not ship itself. For public claims, review FTC Advertising Substantiation (retrieved 2026-09-04); it is legal context, not approval.
Open the query. An a/b test without attached SQL is a slide. If the join is the missing file, continue in analyze experiment results in SQL.
Accuracy and Experience Record: Illustrative Hold after a Primary Win
The following numbers are an illustrative desk composite, not a customer result or uplift claim. Run ID: AB-CALL-20260823. Run date: 2026-08-23. Operator: InfiniSynapse Data Team. Objects inspected: assignment split, primary, refund guardrail, declared CUPED covariate, five aggregates, and Hold decision.
| Item | Desk composite (illustrative) |
|---|---|
| Window | 42 days, assignment-stable |
| Units | 88,100 users; 50.0% / 50.0% |
| Primary | Checkout completion +1.9 pp (illustrative) |
| CUPED | Prior 28-day orders; named in note |
| Guardrail | Refund rate +0.4 pp (illustrative) |
| Recommended action | Hold |
| Owner | Checkout lead, named on memo |
This a/b test is useful because the call is Hold. A primary-only dashboard would have looked like Ship. The refund join is the finding. Iterate means rewrite retry copy, keep the same unit, and run again.
A second a/b test that reuses the refund definition is how the desk accumulates memory. A new CMS experiment with a new “conversion” string is how memory resets.
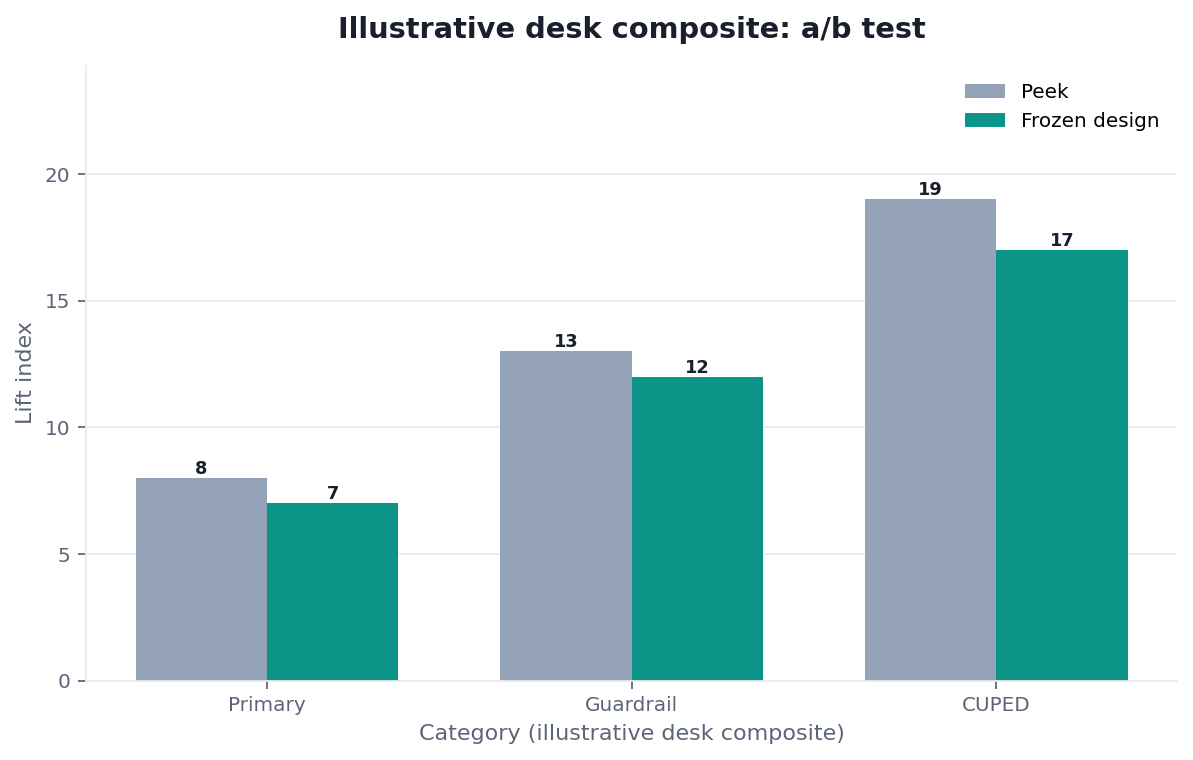
Figure. Illustrative desk composite (category × method). Not a customer experiment, SLA, or official benchmark.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Desk composite on this page | Action, owner, inspectable SQL | Customer uplift or vendor bake-off |
| Published public sources above | Structured objects, links, indexes | That those RFCs ran this desk pack |
Desk composite: +1.9 pp primary, +0.4 pp refund → hold. Context: JSON objects, JSON Patch, Web Linking, CLDR, H3.
The operator held the decision because the refund guardrail moved adversely. The desk log records that call. The CSV exposes five illustrative aggregates and two held items.
Evidence Boundaries and Independent Validation
This is not customer, production, randomized-trial, peer-reviewed, benchmark, representative, or causal evidence. Assignment/outcome rows, intervals, variances, code, SRM test, stopping rule, look history, and covariate diagnostics are unavailable.
The 88,100 users are not a disclosed sampling frame. The 50%/50% split, 1.9-point primary delta, and 0.4-point guardrail delta cannot be independently recomputed. No p-value, interval, power, multiplicity correction, or CUPED-adjusted estimate is published.
The source check marks RFC, CLDR, and H3 references as analogies. The open protocol specifies an external test. As of 2026-08-31, no qualifying independent report, statistical peer review, customer validation, or media investigation exists.
The output checker confirms displayed labels and values only. It does not establish randomization integrity, statistical significance, CUPED validity, causation, compliance, or commercial impact.
An a/b test fixes unit and eligibility. An a/b test freezes primary and window. An a/b test records planned looks. An a/b test checks balance and SRM. An a/b test names CUPED inputs. An a/b test publishes guardrails and intervals. An a/b test leaves humans accountable.
How to Cite This Page
Page: Zhu, W., & InfiniSynapse Data Team. (2026). A/B test: Guardrails, CUPED, and a human call. InfiniSynapse. https://infinisynapse.com/en/blog/a-b-test
Run: InfiniSynapse Data Team. (2026). Desk log AB-CALL-20260823 (illustrative assignment composite). https://infinisynapse.com/blog-media/a-b-test/downloads/desk-log-AB-CALL-20260823.md
Neither is an independent audit, customer experiment, randomized trial, peer review, benchmark, or proof of lift. Cite unavailable rows, missing inferential outputs, Hold decision, and first-party limitations.
Selection Scorecard for the Last Line
Score from 1 to 5. An a/b test that cannot name an owner should not win on a prettier interval.
| Criterion | What “5” looks like | Disqualifier |
|---|---|---|
| Three-way call | Ship / hold / iterate written | “Looks good” |
| Owner | Named human | Model as policy |
| Guardrails | Joined or “not measured” | Primary-only ship |
| CUPED honesty | Named or off | Post-treatment feature |
| Audit | Memo + SQL | Chat-only winner |
| Freeze | No silent patch | Primary rewritten after peek |
An a/b test scores well when finance can replay the hold. It scores poorly when the stack implies a prebuilt warehouse you do not operate.
Failure Modes that Skip the Human Call
Write the break on the memo. Reviews go faster when the skip is explicit.
Treating a green badge as ship
A significant primary is not a launch. An a/b test still needs guardrails and an owner. Shipping from the badge is how refunds show up in the weekly ops pack.
Silent design patches
Changing the primary, the window, or the inclusion rule after a look is a new a/b test. Attach the exploratory chart. Do not treat the new metric as the frozen contract.
Model paragraph as approval
The draft can recommend. The owner signs. An a/b test that files the bubble and deletes the SQL has no replay. A fourth pattern is CUPED on a leaking covariate used to “make the hold go away.”
Before you open a workspace, check four things: a written three-way action, a named owner, at least one guardrail join or an explicit gap, and SQL you can open. If those four are missing, you do not have a finished a/b test.
Route the same diagnosis to the live guide that owns the next object. Each row is a single hop.
| Live guide | Open it when |
|---|---|
| A/B test analysis | you need the hub method |
| experiment analysis | assignment is still dirty |
| CUPED explained | the covariate is the next object |
| experiment decision memo | the downloadable artifact is missing |
| what is a data agent | you need the trail object, not a chat |
Write the decision memo; a human still signs it
Upload a sanitized assignment-and-outcome extract, bind primary and guardrails, and ask for a ship / hold / iterate memo with SQL. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseHow this page is sourced. William Zhu is cofounder of InfiniSynapse (GitHub @allwefantasy); no personal LinkedIn, statistics credential, experiment-platform affiliation, or independent reviewer role is claimed. His profile establishes authorship, not statistical qualification. Desk decisions are recorded in run AB-CALL-20260823. Reviewed internally by analytics engineering · data platform · LLM security · editor. Editorial standards · corrections · publishing principles · Company Vision. COI: InfiniSynapse sells an AI-native Data Agent. ASA, NIST, FTC, IETF, Unicode, and H3 did not validate this run.
Frequently Asked Questions
Can an a/b test ship on a significant primary alone?
Bottom line: No. An a/b test ends in ship, hold, or iterate after guardrails and assignment integrity. A primary win with a refund or latency miss is a hold. If you peeked without a rule, treat the result as exploratory.
Who must sign an a/b test memo?
Bottom line: A human with launch authority. An a/b test can produce intervals and SQL. It cannot accept residual risk. Write the name. If marketing wants a public claim, raise the evidence bar before copy ships.
Does CUPED change the last line of an a/b test?
Bottom line: Only as tighter or wider uncertainty, not as a new action type. Leave CUPED off when the covariate leaks. An a/b test without CUPED is still valid. Do not use the adjustment to erase a hold.
Is a CSV enough to finish an a/b test?
Bottom line: Yes, if it includes unit, variant, assignment time, and outcomes. An a/b test on a file is still a test. Freeze the file date. Bind definitions. Do not treat a missing kill column as a clean guardrail.
Can readers recompute the 1.9-point and 0.4-point deltas?
Bottom line: No. Assignment/outcome rows and inferential outputs are unavailable. The CSV makes five aggregates and two held items inspectable, not independently reproducible.
Has an independent statistician reproduced this run?
Bottom line: No qualifying external report is published as of 2026-08-31. The protocol defines the data, pre-registration, diagnostics, and review required.
Conclusion
An a/b test ends in ship, hold, or iterate. Guardrails and optional CUPED are lines on the same memo. SQL is attached. A human signs. A green badge is not the product. Hold when a kill metric moves. Iterate with the same unit. Do not silently patch the freeze.
When the assignment table and the metric note are ready, ask for that memo on an authorized extract at https://app.infinisynapse.com/. Open the SQL, write the call, and keep the file for the next a/b test.