MongoDB Analytics: Tools, Queries and Dashboards
By William Zhu & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-09-24 · Last verified: 2026-09-24 · Next review: 2026-12-24 · Editorial standards · Corrections
Table of Contents
- TL;DR
- What MongoDB analytics means
- MongoDB analytics architecture options
- Native queries and aggregation pipelines
- Real-time and operational analytics
- Evidence Boundary
- A framework for documents that stay nested
- Methods: document-native vs flatten-first
- MongoDB analytics tools and dashboards
- Performance, indexing, and security
- Implementation steps
- Desk sample: users in Mongo, orders in Postgres (illustrative)
- Scorecard: stay in Mongo vs project to SQL
- Practical Static Replay
- Sources and Limited Claims
- Failure modes
- Frequently Asked Questions
- Conclusion
TL;DR
Direct answer: MongoDB analytics means querying operational BSON documents for reports, dashboards, and decisions without automatically flattening every collection first. Start with native aggregation for document-shaped questions, use a BI or embedded layer for governed delivery, and introduce ETL or a warehouse when many teams need a stable shared grain.
You can also join a relational neighbor on a stable key. The practical choice is not “MongoDB or analytics”; it is direct query, BI connector, federated query, streaming, or warehouse projection based on latency, scale, consumers, and governance. The downloadable static pack later in this guide demonstrates the decision controls without claiming a live production benchmark.
What MongoDB analytics means
Key Definition: MongoDB analytics means treating a document store as an analyst surface: nested fields stay nested, collection notes bind as context, and a relational neighbor can join in the same task. You do not have to flatten every collection into a warehouse before the first question.
Independent published context (separate from this page’s static pack): PostgreSQL documentation · Wikipedia: Data warehouse · NIST AI Risk Management Framework · NCSC secure AI system development guidelines (retrieved 2026-09-04). Those sources set the industry bar for definitions, risk, and architecture; they did not run this fixture, and they are not a product award.
Read scopes and aggregations start from MongoDB documentation (retrieved 2026-09-04). Document shape is the product, as restated in the Wikipedia MongoDB overview (retrieved 2026-09-04).
Flattening rules should respect Wikipedia document-oriented database overview (retrieved 2026-09-04). Join expectations fail for the reasons in the Wikipedia NoSQL overview (retrieved 2026-09-04).
MongoDB stores documents, not first-normal-form rows. The official MongoDB documentation is the contract for collections, BSON types, indexes, and aggregation. An analyst who pretends every document is a spreadsheet row will invent columns that exist on some documents and not others. An agent that does the same will sound confident and be wrong.
If the missing object is durable context rather than a one-off pack, continue in analyze a database without ETL. If the next failure is a join across modes or engines, use multimodal data analysis.
Enterprise framing of collections still uses Wikipedia BSON overview (retrieved 2026-09-04).
This is not “unstructured extraction.” PDFs and tickets are a different problem. MongoDB analytics is operational documents you already write from an app—users, carts, preferences, nested settings—asked with the same discipline you would use on a table. It sits next to what is data management because ownership, retention, and field meaning still apply. It also sits next to self-service analytics: a product manager can ask a goal if the notes exist, and still open the evidence.
MongoDB analytics architecture options
Four patterns cover most MongoDB analytics workloads. Direct aggregation keeps the document model and has the shortest path to an answer. A dashboard or embedded-analytics layer adds governed consumption. Federated query combines MongoDB with SQL or object storage without first copying every field. ETL or change data capture projects stable fields into a warehouse when many consumers need certified history.
| Pattern | Best fit | Freshness | Main trade-off |
|---|---|---|---|
| Native aggregation | Operational questions on current documents | Near-live | Analysts must understand BSON paths and arrays |
| BI or embedded layer | Shared dashboards and application analytics | Live to scheduled | Connector semantics and governance vary |
| Federated query | MongoDB plus relational or lake data | Query-time | Cross-source cost and grain must be controlled |
| ETL / warehouse | Certified metrics, long history, many consumers | Batch or streaming | More latency, modeling, and pipeline ownership |
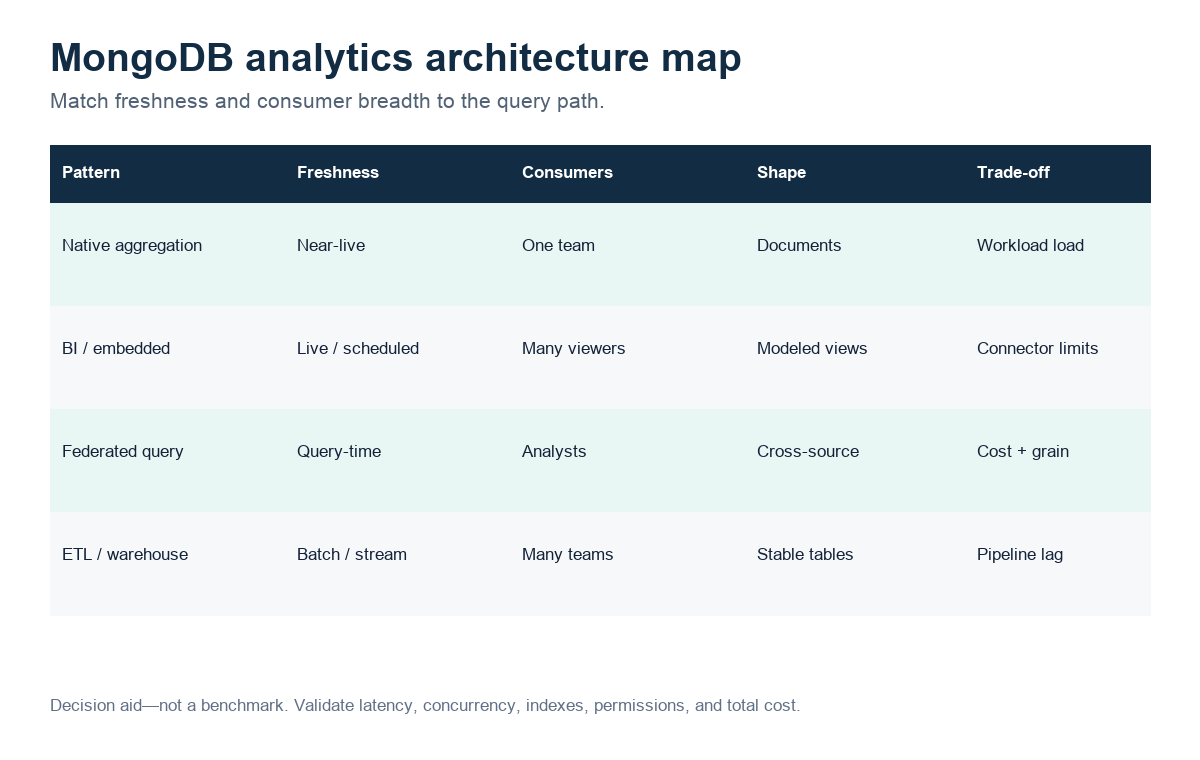
Figure. Architecture decision aid; not a measured vendor benchmark.
MongoDB documents remain the source of truth in all four patterns. The right architecture depends on the consumer and clock, not a blanket rule that NoSQL must be flattened. MongoDB documents its supported aggregation stages and Atlas Data Federation separately; verify feature and region support against the current official documentation.
Native queries and aggregation pipelines
A native MongoDB analytics pipeline normally narrows documents with $match, selects durable fields with $project, controls arrays before $unwind, and calculates metrics with $group. Put selective filters early and preserve the business grain explicitly. MongoDB's aggregation optimization guidance explains that the optimizer can reorder some stages, but it cannot repair an ambiguous business definition.
db.users.aggregate([
  { $match: { createdAt: { $gte: ISODate("2026-09-01") } } },
  { $project: { userId: 1, locale: "$profile.locale" } },
  { $group: { _id: "$locale", users: { $addToSet: "$userId" } } },
  { $project: { locale: "$_id", users: { $size: "$users" }, _id: 0 } }
])
This illustrative pipeline counts distinct users by locale; it is not a production benchmark. If profile.locale is missing, renamed, or stored inside an array, collection notes must define the fallback before the result is trustworthy.
Real-time and operational analytics
Real-time MongoDB analytics serves decisions close to the application event: inventory alerts, feature adoption, fraud review, or an in-product dashboard. Operational analytics reads the same document domain that powers the application, while a warehouse usually optimizes historical, cross-domain reporting. MongoDB's official change streams documentation describes how applications can subscribe to data changes; a stream processor or downstream store is still required when transformations, retention, or fan-out exceed the operational cluster's role.
Do not run an unbounded dashboard scan against a hot primary merely because the data is fresh. Define latency, concurrency, retention, and acceptable staleness first; then decide whether to query a replica, pre-aggregate, stream changes, or project a certified model.
Evidence Boundary
This is a synthetic, static, NON-CONNECTING identity fixture (MDA-20260831). No MongoDB URI, host, TLS path, Postgres DSN, user, executed query, recalled passage, warehouse hop, or production workflow was observed.
The package does not claim that anyone projected a live locale, joined orders, filed no flatten job, reused notes the next week, or left a warehouse ticket on the roadmap. To operationalize an analyst ask, each claim needs environment evidence.
Do not prove a negative privilege by writing to the production cluster. First review the role catalog. Any later negative test needs separate authorization. TLS is not optional because the path looks private.
This page has no customer case, no measured SLA, no media mention, and no independent institutional endorsement. The first-hand object is the authored pack you can download and lint offline. Do not treat this download as a measured result, a customer post-mortem, or media mention.
A framework for documents that stay nested
Four objects decide whether document questions are safe.
| Object | What you must know | Failure if missing | Fixture state |
|---|---|---|---|
| Collection | Name, id field, which nested paths are durable | The agent queries a ghost path | authored users |
| Notes | Enum meanings, deprecated keys, null vs missing | Two documents, two definitions | authored profile.locale |
| Grain | User, account, session, or event—pick one | Array explosion looks like “more users” | authored user |
| Neighbor | Whether orders or billing live in SQL | A flatten project starts too early | optional / HELD |
Collections, documents, and analyst questions
A collection is not a table with a bonus JSON column. Documents in one collection vary. Some users have profile.locale; older ones have locale; a third cohort has neither. Analyst questions must name the path they mean or the notes must map aliases. “Revenue by locale” is a goal. “Unwind every array and see” is a fishing trip that the store will happily make expensive.
Schema recall versus a warehouse model
A warehouse model freezes a grain. Schema recall for documents is closer to retrieval: the agent needs the notes that say which path is current. The NIST AI Risk Management Framework is the independent map for treating that context as a risk control—measure, manage, and govern the mapping—not as a prompt decoration. A semantic layer in a warehouse is a stricter cousin. Use notes first on MongoDB; promote a certified grain later if many teams consume the same flatten.
Direct query vs ETL and warehouse projection
Two methods compete. The expensive one often starts before anyone has asked a real question.
| ID | Candidate | Outcome | Why |
|---|---|---|---|
MDA-Q1-IDENTITY | uri, host, collection, postgres, task | HOLD / NOT READY | all identity fields HELD |
MDA-Q2-NESTED-NOTE | profile.locale at user grain | QUALIFIED FOR STATIC REVIEW | policy text; DO NOT EXECUTE |
MDA-Q3-ROW-HABIT | treat every document as a sheet row | REJECTED AS UNSUPPORTED | sessions are not users |
MDA-Q4-FLATTEN-FIRST | warehouse both stores first | REJECTED AS UNSUPPORTED | flatten is a later consumer |
Asking nested fields without a flatten project
Document-native analytics asks for a nested field the notes already define. Example: “Share of users with profile.locale in en-* who were created in the last 7 days.” The path is in the question. The agent projects that path. No warehouse ticket. This is the default when the app already writes the document you care about. This pack did not run that ask.
Operational reports—weekly active writers, preference adoption, nested feature flags—still need a grain. Arrays of addresses or devices will multiply people if you unwind without counting distinct ids. Write the grain in the goal. “Users, not devices” is a sentence the agent can follow if the notes say which array is devices.
Joining MongoDB with a relational store
Many companies keep identity or preferences in MongoDB and orders in PostgreSQL. The PostgreSQL documentation is the contract for the SQL neighbor. Join on a stable user_id. Aggregate each side to the same grain before the join. AI for data analysis programs that already federate sources can do this as one task. A flatten-first program would copy both sides into a data warehouse and wait on a model review. Sometimes you need that warehouse. Often you need Tuesday’s answer.
A useful collection note is boring and specific. Start with the collection name, the durable id (_id versus user_id), and three nested paths you will actually ask. Add a two-line alias table for renamed keys. Add a “do not ask” list for tokens, raw emails, and payment instruments. State how missing differs from null on the paths you care about—some apps omit profile.locale for default English, others store null. If an analyst filter will run every week (created_at, status, tenant_id), say whether an index already exists; an agent cannot invent a cheap plan on an unindexed scan of a hot collection. None of that is warehouse modeling. It is the minimum context that makes a document question repeatable.
MongoDB analytics tools and dashboards
No single tool wins every MongoDB analytics workload. Compare the query path, semantic controls, delivery format, cross-source support, and operating burden. Verify current capabilities and prices with each vendor rather than treating this table as a measured bake-off.
| Category | Examples | Best for | Watch for |
|---|---|---|---|
| Native MongoDB interfaces | Atlas UI, Compass, aggregation pipeline | Exploration and document-native queries | Not a complete governed BI layer |
| General BI | Power BI, Tableau, Looker | Shared dashboards and familiar governance | Connector behavior, nested arrays, refresh latency |
| Native NoSQL analytics | Knowi and similar platforms | Direct document queries, embedded dashboards | Vendor-specific semantics and licensing |
| Open-source BI | Apache Superset, Metabase | SQL-oriented self-hosted reporting | MongoDB often needs a bridge or modeled layer |
| Code and notebooks | Python, R, Jupyter | Statistics, custom transformations, models | Reproducibility and deployment ownership |
| Warehouse stack | CDC/ETL plus warehouse BI | Certified history across many domains | Pipeline cost and schema lag |
A product page can promise “no ETL,” but the real test is whether nested paths, missing values, arrays, permissions, and cross-database joins remain inspectable. Use document database reporting for recurring delivery and MongoDB query when the aggregation pipeline itself is the reviewable artifact.
Choosing a dashboard path
Use direct dashboards when questions stay close to one collection and freshness matters. Use a semantic or warehouse layer when many teams need the same metric, historical snapshots, row-level controls, and predictable joins. For embedded customer-facing analytics, also test tenant isolation, cache invalidation, export limits, and query concurrency.
Performance, indexing, and security
Production MongoDB analytics needs a workload budget. Review filters and sort keys with explain, add indexes for repeated selective predicates, limit returned fields, and avoid unbounded array expansion. MongoDB's official indexing documentation and read preference documentation describe the mechanics; neither replaces workload testing on your own document shapes.
Use a dedicated read-only identity, TLS, network restrictions, secret rotation, query timeouts, and an audit trail. Keep raw email, tokens, payment data, and unrestricted exports out of analyst-facing notes. The NIST AI Risk Management Framework and NCSC secure AI guidelines provide governance baselines when an AI agent participates in the query path.
How to implement MongoDB analytics safely
These steps replay the identity pack offline. Skipping “explain” is the usual document-store failure.
- Open
identity-register-MDA-20260831.csvand confirm every sensitive field isHELD. - Compare the accepted collection note as policy text. Do not execute. Review the role catalog; do not write to MongoDB to prove a negative grant.
- Reconcile
identity-decision-register-MDA-20260831.csv: Q3–Q4 rejected; Q1 held; Q2 static-only. No row is selected. - Read the assumption register and held-evidence list. Leave cluster and Postgres facts unresolved. TLS stays required.
- Run
python3 verify-MDA-20260831.pyfrom the downloads directory.
A passing local check does not authorize a live MongoDB ask. It reports file agreement among the authored downloads only.
For a later authorized review, collect owner approval, the URI, TLS evidence, the dedicated read grant, the bound note, one grain-bounded goal, and—only after authorized execution—the opened recall and any join. Until those exist, keep HOLD. Database credentials in a chat log are an incident.
Desk sample: users in Mongo, orders in Postgres (illustrative)
Static fixture, not a customer uplift and not a latency SLA. Sources: an authored users note in MongoDB with nested profile.locale, and an authored orders neighbor in PostgreSQL. Notes defined locale as profile.locale with a fallback list. Goal text: last-7-day order revenue by locale, users as the grain.
The lint register rejects a spreadsheet-row habit and rejects warehousing both stores before the first ask. MongoDB analytics is static-ready where path, grain, and forbidden unwind are named, and held where identity is missing. No executed projection, no posted memo, and no second-run reuse is claimed.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Static pack on this page | Grain, notes, inspectable artifacts | Customer uplift %, minutes, vendor bake-off |
| Published authority (linked) | Frameworks and definitions from the cited sources | That those sources ran this fixture |
Labels stay illustrative, not a measured cluster result. Published context: MongoDB docs, Wikipedia MongoDB / document stores / NoSQL / BSON, PostgreSQL docs, NIST, NCSC, retrieved 2026-09-04.
The phrase MongoDB analytics is the object under test. If a file cannot show how the query named the nested path and user grain, reject the number.
Decision scorecard: direct query vs SQL projection
| Signal | Stay in MongoDB + notes | Project to warehouse / SQL |
|---|---|---|
| Consumer | One team, one weekly pack | Many teams, certified metrics |
| Shape | Nested fields the app still writes | Stable columns others will join blindly |
| Change rate | Keys still evolving | Keys frozen by a model review |
| Join | One SQL neighbor on a shared id | Deep cross-domain stars |
| Risk | Notes and read-only role hold | Downstream SLAs on a table |
Stay in MongoDB when the document is the truth and notes can keep up. Project when other systems need a frozen table. Both can exist. Starting with the project is how document analytics never ships.
Practical Static Replay
Replay the MongoDB hub pack as a file comparison: freeze MDA-20260831, confirm held identity fields, confirm the accepted note names profile.locale and forbids unwinding devices[], confirm Q3–Q4 are policy rejects, then keep verifier output and hashes.
Figure. STATIC FIXTURE / NOT CONNECTED / NOT INDEPENDENTLY VALIDATED. Authored identity and policy labels only; no runtime or customer result.
Passing this replay means the MDA files agree. It does not prove reachability or suitability. Record Python version, OS, hashes, and HOLD output. Record freeze date beside HOLD.
Sources and Limited Claims
Direct official sources were retrieved on 2026-08-31. PostgreSQL documentation, Wikipedia data warehouse, MongoDB documentation, Wikipedia MongoDB, document-oriented database, NoSQL, BSON, and NCSC secure AI guidelines are cited here. NIST AI RMF keeps its official URL; this desk could not fetch a fresh 200. They describe the SQL neighbor, warehouse books, document shape, flatten rules, and least privilege. They do not validate this fixture. Re-check those URLs later.
None audited MongoDB analytics on this page. Some hosts may be retained without a fresh 200; keep the original URLs.
Internal review is not independent validation. A qualified reviewer would need owner approval, live URI and TLS evidence, the bound note, one authorized nested statement, and versions. Until then this pack is not a third-party audit, certification, award, media mention, or customer case. GitHub profiles are public engineering traces, not a published resume or independent endorsement. If a reviewer only reran Python, say so.
How to cite. InfiniSynapse, MongoDB Analytics: Tools, Queries and Dashboards, MDA-20260831, HOLD / NOT READY FOR CONNECTION, not independently validated. Name the downloaded files used.
Downloads:
- Identity register
- Accepted collection note
- Decision register
- Expected readiness
- Review rules
- Held evidence
- Assumptions
- Source check
- Reproduction protocol
- Verifier
Failure modes
Document stores punish spreadsheet habits. This pack did not run a live ask. A missing grain is how a MongoDB question fails.
Treating every document as a row
If you count documents as users while some documents are sessions, the store will not correct you. Name the grain. Put it in the notes. Reject tasks that say “rows.”
Unbound arrays and exploded joins
$unwind without a later distinct count multiplies people. Joining an unwound array to orders multiplies revenue. Write “do not unwind devices when counting users” in the notes. Inspect the pipeline.
Missing collection notes
Deprecated keys, null versus missing, and renamed paths are tribal knowledge. Unbound document analysis fills the gaps with fluent guesses. Bind the notes. If the task does not show recall, do not send the memo.
Before you connect, list the collection, the id, the nested paths you will ask, the fields that are forbidden, and the SQL neighbor if any. If you cannot fill that list, you are not ready to spend a document read on an agent. If you can, bind the list as notes and ask one grain-bounded question.
Cluster guides under this hub: Connect MongoDB to an AI Analyst; NoSQL Data Analysis without Flattening First; Analyze Nested JSON in MongoDB; Mongo plus Postgres Analysis in One Task; Document Database Reporting for Operations; MongoDB Schema Recall from Bound Notes; What Is MongoDB for an AI Analyst; audit MongoDB Atlas (authorize, do not flatten first); MongoDB Query the Agent Must Show; MongoDB NoSQL Analysis without a Warehouse Ticket; How Does MongoDB Work in an Analysis Task.
Related hops: analyze a database without ETL; multimodal data analysis; ClickHouse analytics; support ticket analytics on an export; natural language to SQL.
Connect MongoDB and bind collection notes
Add a read-only MongoDB source, upload the collection note, bind it, and ask one nested-field question you can inspect. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseHow this page is sourced. William Zhu is cofounder of InfiniSynapse (GitHub @allwefantasy); InfiniSynapse on GitHub. Company self-description, not independent authority. No personal LinkedIn is published. Desk experience: designing and reviewing analysis-pack methods—definition locks, read-only source binds, and downloadable
/tasksartifacts. Reviewed internally by analytics engineering · data platform · LLM security · editor. Editorial standards · corrections · publishing principles · About · Privacy · Terms · Contact zhuhl@infinisynapse.com. Company About. COI: InfiniSynapse sells an AI-native Data Agent; the banner is a commercial association. Fact-check: postgresql.org · wikipedia.org · nist.gov · ncsc.gov.uk · mongodb.com. No external organization audited it. This page is not third-party recognition.
Frequently Asked Questions
Do I have to flatten MongoDB into a warehouse first?
Bottom line: No. Flatten when many teams need a frozen grain. For the first analyst question, connect MongoDB, bind notes, and ask.
How do nested fields get into the answer?
Bottom line: You name the path in the goal or in the notes. Schema recall is not magic. MongoDB will not invent a durable path you never documented.
Can I join MongoDB to Postgres?
Bottom line: Yes on a stable id, after each side is aggregated to the same grain. Do not unwind arrays and then join.
Is this the same as extracting PDFs?
Bottom line: No. MongoDB analytics is operational documents. Unstructured files are a different surface.
What does a read-only role prevent?
Bottom line: Writes, drops, and “fix it in prod” prompts. The NCSC and NIST checklists treat that limit as a design requirement, not a nice-to-have.
Conclusion
MongoDB analytics works best when architecture follows the question: native aggregation for document-shaped operational answers, dashboards for governed delivery, federation for bounded cross-source work, and ETL or a warehouse for stable multi-team history. Preserve grain, inspect the query, and protect the operational workload.
MongoDB analytics is notes, grain, and a read-only client. Keep documents nested until a warehouse consumer actually exists. Bind the aliases. Ask one goal. Inspect recall and any SQL join.
InfiniSynapse describes itself on About. Privacy and Terms apply. If you later use the workspace, open InfiniSynapse only with authorized, sanitized inputs.