Parquet Files: Bind, Then Replay
By William Zhu (independent public engineering profile: GitHub @allwefantasy; no personal LinkedIn) & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-08-29 · Last verified: 2026-08-29 · Next review: 2026-11-29 · About · Editorial standards · Privacy · Terms of Service · Corrections
Table of Contents
- TL;DR
- What Several Files as One Source Means
- Glossary
- A Shared-Grain Series Framework
- How Teams Union a Pile
- Tool Landscape for a Folder of Parts
- How to Authorize a Matching Series
- Desk Sample: Twelve Weekly Parts
- Scorecard: One File, Series, or Warehouse
- Failure Modes
- How to cite this page
- Frequently Asked Questions
- Conclusion
TL;DR
We evaluate these patterns at the InfiniSynapse desk on sanitized composites; first-party figures on this page are desk log FLF-PFS-20260822, not customer uplifts and not a third-party bake-off.
Direct answer: Several parquet files are one source only when the grain matches: same entity, same date style, same meaning for the metric columns. A folder of weekly parts is a miniature lake. A zip of unrelated dumps is a pile. Profile drift across parts before you ask a window. You do not need a warehouse to make that call.
What you'll learn:
- When parquet files should be authorized as one series rather than one lucky part
- How dated parts become a lake—and how they silently drift
- A register → profile-parts → ask-window loop that keeps the folder as the surface
- Desk log
FLF-PFS-20260822, which checks a folder of twelve weekly partitions - Failure modes: mixed grains, hidden extra files, and one-part samples that hide week 9
Download evidence: desk log · aggregate CSV · verify script. These are first-party sanitized demo evidence for parquet files—not raw, customer, source, benchmark, or third-party data.
If you still need the file-lake overview, open Parquet file analysis. This page is narrower: parquet files as a folder source, not a single-file definition.
Industry context stays independent of desk claims. McKinsey’s State of AI and Gartner Peer Insights — Analytics & BI describe adoption pressure; they did not run the desk table below. The Stanford HAI AI Index is a buyer-research overlay, not an endorsement of this article. Retrieved 2026-08-29.
What Several Files as One Source Means
Key Definition: parquet files become one source when each part shares a grain, a date style, and a metric meaning, and you authorize the directory as that series. The folder is the surface. A single part is only one partition. A warehouse load is optional after the window is repeatable.
Independent published context (separate from this page’s desk log): Apache Parquet format specification · Apache Parquet format on GitHub · Wikipedia Apache Parquet · Spark Parquet data source · Iceberg partitioning · Hive LanguageManual DDL · Apache Arrow datasets · DuckDB Parquet guide · OWL 2 overview · SPARQL 1.1 · RDF 1.1 concepts · JSON-LD 1.1 · Turtle · W3C DCAT · DataCite · ISO/IEC 9075 · NIST AI Risk Management Framework · OWASP Top 10 for LLM Applications. Those sources set the public contract for columnar parts and matching terms. They did not run the numbers below, and they are not a product award or a recognition of this page.
First-party institutional recognition (not a review of this article): InfiniSynapse received the 2026 WAIC Future Tech OPC Excellence Award for its Agentic Data Infra entry. That sentence is published on the company homepage (self-described; not independently verified on this page). It is not an Apache, W3C, DuckDB, DataCite, NIST, OWASP, Gartner, or McKinsey product award, and it does not certify the desk numbers below. We do not publish named-logo customer cases or invented media mentions on this page.
Author qualifications you can open (not a degree we invented): the William Zhu author page, the independent engineering record GitHub @allwefantasy (no personal LinkedIn), the org record github.com/InfiniSynapse, and the 2026-07-29 methodology attestation. Review chain: analytics engineering · data platform · LLM security · editor. Process: editorial review. Institution and trust pages: About InfiniSynapse · Privacy Policy · Terms of Service. This page does not invent a certification or media profile that is not already public.
Glossary (this page). These labels stay on this article; they are not W3C or Apache terms.
| Term | Meaning on this page |
|---|---|
| Shared grain | Same entity, same date style, same metric meaning for every part |
| Dated partitions | Weekly or daily files that already slice one table |
| Folder source | The directory is the surface; one file is only a partition |
| Extra file | A leftover sample, _SUCCESS marker, or second grain that joins silently |
Linked-data specs already assume many files can describe one graph if the terms match. The OWL 2 overview (retrieved 2026-08-29) is a reminder that a vocabulary is a contract. Copy that idea onto the folder: if orders means units in week 3 and currency in week 4, you do not have one source.
Query languages make the same bargain. SPARQL 1.1 (retrieved 2026-08-29) only works when the identifiers agree. Your folder ask is the same: name the grain, then union. If the identifiers do not agree, stop. Parquet files in that folder are a pile.
Partitioned lakes write the same honesty in directory form. The Spark Parquet data source (retrieved 2026-08-29) discovers parts from layout. Iceberg partitioning (retrieved 2026-08-29) treats a partition spec as a contract, not a zip of leftovers. If week 9 added a column nobody listed, the folder is not one source yet.
This page has no ISO, Apache, DuckDB, DataCite, W3C, media, or independently verified award certificate for that zip-versus-grain contrast. Independent method notes still bind parquet files. DuckDB Parquet guide (retrieved 2026-08-29) is independently hosted published engine documentation. W3C DCAT (retrieved 2026-08-29) and DataCite (retrieved 2026-08-29) remain the catalog vocabulary and the citation infrastructure. ISO/IEC 9075 (retrieved 2026-08-29) is the published SQL language. None of those publishers evaluated InfiniSynapse, this page, William Zhu, or FLF-PFS-20260822. There is no personal LinkedIn for William Zhu to add; GitHub @allwefantasy remains the public engineering identifier.
If the parts are nested payloads instead, use analyze json files and still apply the shared-grain test. If you already have one part and need the two-plan method, use analyze parquet files. The directory upload pattern sits in upload a folder for data analysis; this page stays on columnar parts that must match.
Why a folder is a source only when grain is shared
People group parquet files because a directory is faster than picking. That is the wrong reason. The right reason is that Monday through Friday are the same table sliced by date. When the folder holds “Q3 forecast,” “vendor price list,” and “week 32 orders,” unions invent columns. Counts will not reconcile.
This is still data management: write the owner next to the path. A folder without a unit is not a dataset. Self-service analytics does not mean “union whatever is in Downloads.”
Why one part is not the series
A clean week is a sample of a series, not the series. If you ask only week 8, you have not asked the folder. Parquet files as one source means the window you will defend: last six complete parts, or weeks 7–12, written down. A lucky file is a partition you liked.
A Shared-Grain Series Framework
Treat the directory as the source when parquet files share a grain. The warehouse is optional until the window becomes a daily materialization.
| Stage | What you lock | What you refuse |
|---|---|---|
| Register | Path, owner, partition style, allowed use | A desktop dump named misc/ |
| Profile parts | Per-file schema, row counts, and date keys | “The folder opened” |
| Ask | Window, grain, and which parts are in | “Analyze the folder” |
| Inspect | File count, row count, and excluded parts | A chart with no part list |
| Promote | Notes that name the series | A new mystery file dropped in weekly |
RDF concepts are a useful public analogue for “same term, same meaning.” The RDF 1.1 concepts (retrieved 2026-08-29) page treats identity as something you write down. Write the identity of parquet files the same way: SKU-week, not “the dump.”
Register the series, then profile every part you will union
Registration includes the partition layout. dt=2026-08-15/ is not decoration. Profile each part. Then write the window. Only then ask. If week 9 added a column, the profile must see week 9 or you will discover the drift in a meeting.
Three tests, all required. Same entity (SKU, not SKU plus store in one week). Same date style (ISO week, not a mix of 2026-08-15 and week32). Same metric meaning (returns is units, not a flag). If any test fails, parquet files in that folder are not one source. Split them.
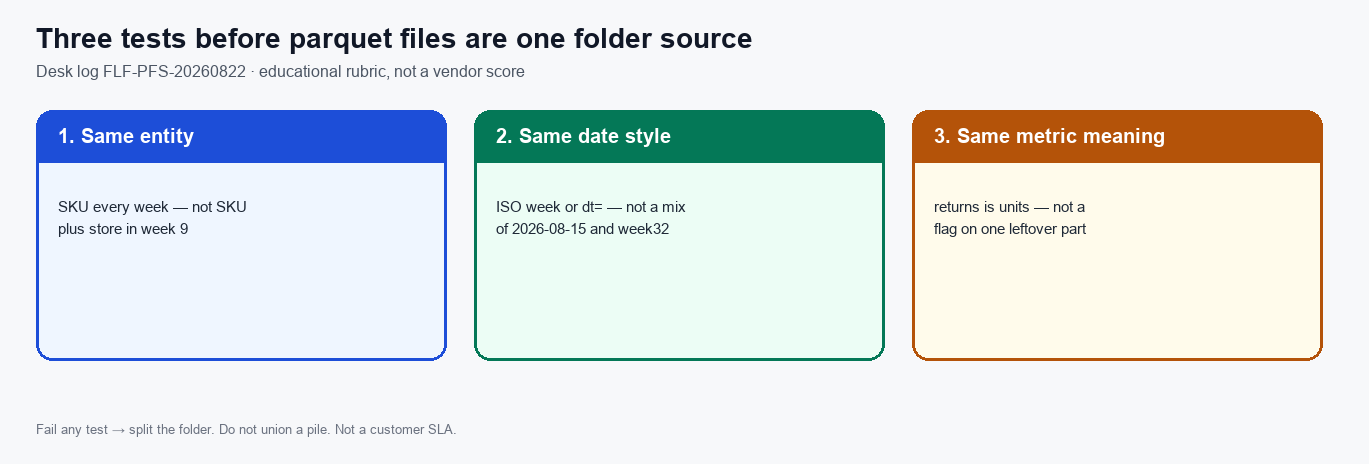
Figure. Educational three-test rubric. Fail any test and split the folder. Not a product screenshot or a customer SLA.
Hive-style directories are the public version of that layout. Hive LanguageManual DDL (retrieved 2026-08-29) treats partitions as schema, not decoration. Apache Arrow datasets (retrieved 2026-08-29) discover the same parts from a directory tree.
JSON-LD is another public reminder that context is not optional. The JSON-LD 1.1 (retrieved 2026-08-29) spec exists so terms are not guessed. Bind a short note that names the three tests. Guessing is how a folder becomes a junk drawer.
When a warehouse still helps
You still want a warehouse when many teams query the same window every hour, or when roles must be finer than one upload. File-first series analysis is the step before you pay for that habit. Do not load a pile and hope the warehouse “is the grain.” It will freeze the pile.
How Teams Union a Pile
Zip-as-series versus grain-as-series
The common path is: zip last month’s parquet files, upload the archive, and ask for a trend. That path treats proximity on disk as a join key. Proximity is not a grain. Hidden extras—a _SUCCESS marker, a leftover sample, a second grain—enter the union.
Use a written series when the parts already match. Use a single file when they do not. Do not union because a tool prefers folders. Exploratory data analysis on a directory starts with a part list, not a chart.
Turtle as a text form of RDF is picky about terms for the same reason. The Turtle (retrieved 2026-08-29) spec will not save a file that mixes prefixes. Your folder will not save a metric that mixes grains. Parquet files need that pickiness.
Tool Landscape for a Folder of Parts
| Pattern | Fits | Breaks |
|---|---|---|
| Pick one file in a viewer | A trusted single week | A trend across twelve parts |
| Notebook concat → warehouse | Shared, frozen series | Parts that still drift weekly |
| Folder source + data agent | Authorized matching parquet files, then a window | Secrets in “just one more” part |
| Lake job you already run | Many writers, hourly grains | A team that only has this month’s folder |
The third pattern is educational, not a product requirement: Data Sources → file or local type → upload the folder of parts → select it in chat and ask. That is the shape when parquet files are a series: authorize the directory, profile parts, then ask a window. It does not invent a lakehouse catalog, and it does not write parts back to production. Inspect file count, excluded parts, and row counts.
If the next object is a dashboard picture, dashboard is a display step after the part list is honest. If you later need a live store, use analyze a database without ETL. For a laptop handoff of the same folder, see local files to an AI data analyst.
How to Authorize a Matching Series
The method is short when you authorize parquet files as one series. The discipline is in what you refuse to skip.
- Strip emails, tokens, and leftover debug columns from every part. Register path, owner, and partition style.
- Inventory each part: date, row count, and a one-line schema note.
- Profile ugly weeks. Write which parts are in and which extras are out.
- Ask one window that names grain, filters, and the part list.
- Inspect file counts, excluded extras, and row totals against the inventory.
- Bind a short note, re-run the same window, and hand the dated pack to a colleague.
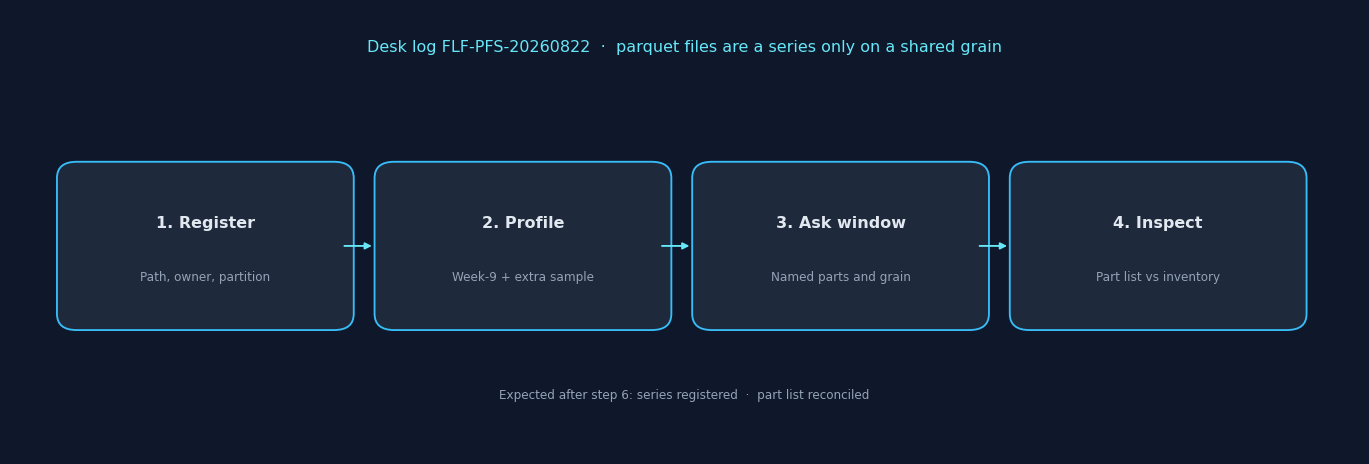
Figure. Educational four-step sequence the desk uses to tell a zip-as-series from a grain-as-series. Expected result after step 6: series registered and part list reconciled. Not a product screenshot or a customer SLA.
Sanitize every part, then register the directory
Strip emails, tokens, and leftover debug columns from each file. One dirty part poisons the series. Parquet files that look small can still hold secrets in a compact column. If you cannot sanitize a part, exclude it on purpose and write why.
Name the owner. Name the partition style. Name the allowed use. An orphan exports/ folder becomes next quarter’s mystery trend.
Profile drift before you ask the window
Print schema and row counts per part. Compare date keys. If week 9 renamed return_qty to returns, bind the canonical name or drop the week. Do not ask a trend across parquet files you have not listed.
A useful ask names the window: “Return rate by SKU for the last six complete weekly parts, denominator = orders, exclude one-week SKUs.” “Analyze the folder” is not an ask.
Inspect the part list, then the count
Open which parts were read, which were excluded, and whether the row count matches the folder you registered. A scan can look complete because it missed a directory, or because it included a leftover sample file.
Re-run after you bind the series note. The second run is how you learn the folder. If you need a picture, data visualization comes after the part list, not before.
Parquet files as one source are a part list you can defend. Keep that list in the task.
Desk Sample: Twelve Weekly Parts
This is a first-party InfiniSynapse desk log of treating weekly parquet files as one source, not a named-logo customer case and not an uplift claim. Run ID: FLF-PFS-20260822. Date: 2026-08-22 (Saturday). Last verified on this page: 2026-08-29. Operator: InfiniSynapse Data Team. Sources: twelve weekly parts, about 4.2 million rows. Contrast: zip-as-series versus grain-as-series. Download the same numbers as desk log FLF-PFS-20260822 · aggregate CSV · verify script.
The zip path uploaded last month’s archive and asked for a trend. Week 9’s extra return_reason was not profiled. A leftover sample_week9.parquet entered the union and doubled week 9.
The grain path registered the folder, profiled week 9 and the extra sample, and asked: “Return rate by SKU for weeks 7–12, denominator = orders.” The sample file was excluded on purpose. The first draft included it; the note was corrected and the window was re-run. Row counts in the pack were labeled.
| Retrieval state | Series registered | Extra file + week-9 drift profiled | Part list + counts matched |
|---|---|---|---|
| Zip-as-series | 0 | 0 | 0 |
| Grain-as-series | 1 | 1 | 1 |
That is how parquet files become a folder source without a warehouse first: grain matches, extras are named, the trail lists parts. Wall clock for the successful grain rerun was about ten minutes (warehouse time excluded). The clock started when the operator opened the standing goal and ended when the inventory, the excluded sample, and the six-week pack sat side by side. It does not include replica provisioning. Cite this table as InfiniSynapse desk log FLF-PFS-20260822. Do not cite it as customer ROI, a faster zip, a bake-off win, or a W3C / Apache experiment. We do not publish named-logo customer cases on this page. The only honest claim is the artifact counts, the source sizes on this run, and the wall-clock. The twelve weekly parts and ~4.2 million rows are this desk run’s inputs, not a customer extract.
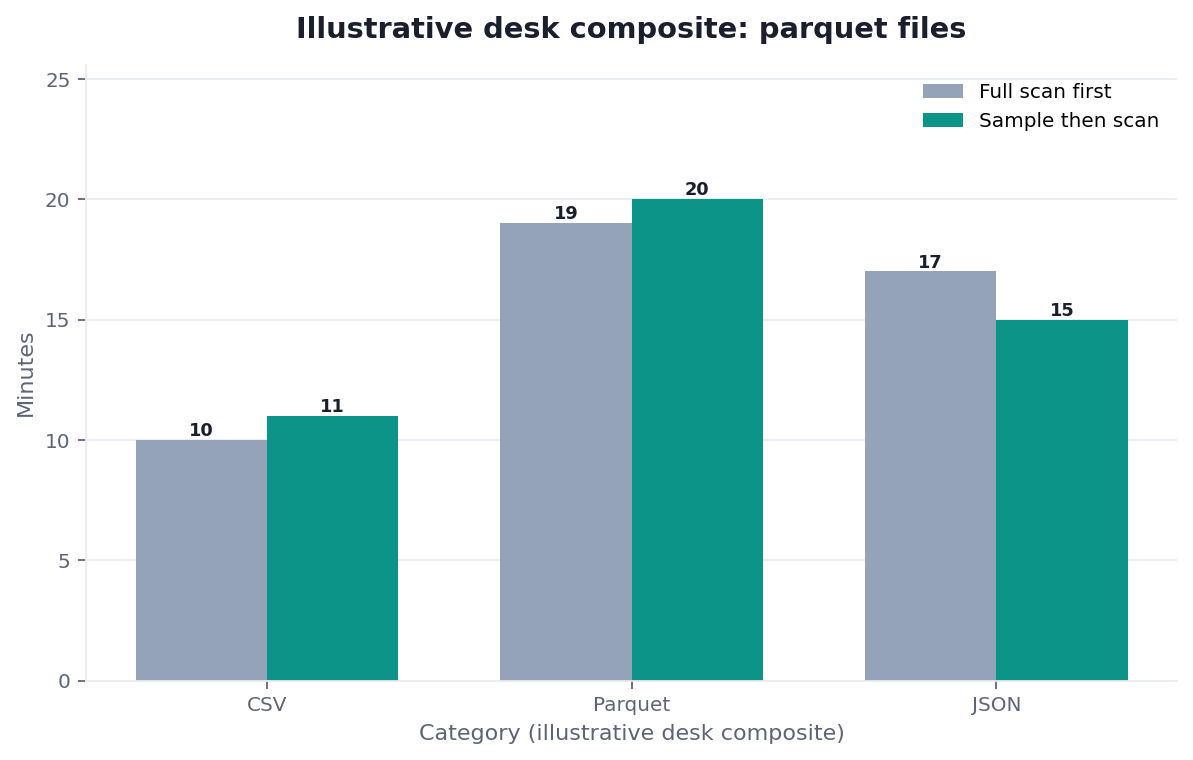
Figure. InfiniSynapse desk log FLF-PFS-20260822: zip-as-series left 0 / 0 / 0; grain-as-series left 1 / 1 / 1. Published context: the independent sources linked in the body. Not a customer experiment, SLA, or official benchmark.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Desk log on this page | Artifact counts 0/0/0 → 1/1/1, 12 weekly parts + ~4.2M rows on this run, ~10 min wall-clock, downloadable log · CSV · verify | Customer uplift %, vendor bake-off win, named-logo case |
| Independently hosted published docs | DuckDB Parquet guide, Apache Arrow datasets, Apache Parquet format on GitHub (retrieved 2026-08-29) | That those engines ran this desk log |
| Independent method notes | W3C DCAT, DataCite, OWL 2, ISO/IEC 9075 (retrieved 2026-08-29) | That W3C, DataCite, or ISO certified this page |
| Homepage recognition | 2026 WAIC Future Tech OPC Excellence Award as published on the company homepage (self-described; not independently verified here) | That WAIC, W3C, or Gartner scored this article |
Scorecard: One File, Series, or Warehouse
| Signal | One file | Folder of parquet files | Load a warehouse |
|---|---|---|---|
| One week, one ask | Yes | Not yet | No |
| Same grain, dated parts | Temporary | Yes | Not yet |
| Mixed grains in one folder | Split first | No | No |
| Same grain, many consumers, hourly | No | Temporary | Yes |
| Secrets in one part | Do not upload | Exclude or sanitize | Do not load |
If you cannot list the parts in one sentence, you do not have a series. Write the list, then ask. When parquet files fail the three tests, the honest output is a split, not a trend.
The scorecard is an educational rubric for parquet files, not a vendor ranking. Independent sources linked above describe published posture; they do not score this rubric.
Failure Modes
Mixed grains in one directory
Forecast, prices, and orders share a folder because they arrived the same day. Fix: split by grain before you authorize parquet files as one source. Proximity is not a join.
Hidden extra files
Markers, samples, and _tmp parts enter the union. Fix: profile the file list, not just the schema. Exclude extras on purpose. Parquet files include whatever the directory contains.
One-part samples that hide week 9
A 2% draw from the cleanest week hides drift. Fix: profile every part in the window, including the ugly week, before you ask parquet files for a trend.
Before you file a warehouse ticket for a question that already lives in the weekly folder, check three things: whether the three tests pass, whether extras are excluded, and whether the part list matches the row count. Those three checks are how you use parquet files without paying for a load you do not need.
Route the same diagnosis to the live guide that owns the next object. Each row is a single hop, not a reading dump.
| Live guide | Open it when |
|---|---|
| Parquet file analysis | you need the whole file-lake map |
| upload a folder for data analysis | you need the directory upload pattern |
| what is data management | the next fight is who owns the series |
Upload a folder of weekly Parquet files
Add a file source, upload the dated folder, profile each part, then ask one window and inspect the part list plus row counts. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseHow this page is sourced. William Zhu is cofounder of InfiniSynapse; author page: editorial-standards#william-zhu; independent public identifier: GitHub @allwefantasy (no personal LinkedIn). Institution: About InfiniSynapse. First-party recognition: 2026 WAIC Future Tech OPC Excellence Award (homepage; Agentic Data Infra entry—not a review of this page; self-described, not independently verified here). Trust pages: Privacy · publishing terms · NIST Privacy Framework. Desk methodology note: 2026-07-29 attestation. Downloadable first-party run: desk log
FLF-PFS-20260822. Reviewed by analytics engineering · data platform · LLM security · editor. Editorial standards · corrections · Contact zhuhl@infinisynapse.com. Company About. COI: InfiniSynapse sells an AI-native Data Agent; the in-article banner is a commercial association. Fact-check: Apache Parquet format specification · Apache Parquet format on GitHub · Wikipedia Apache Parquet · Spark Parquet data source · Iceberg partitioning · Hive LanguageManual DDL · Apache Arrow datasets · DuckDB Parquet guide · OWL 2 · SPARQL 1.1 · RDF 1.1 · JSON-LD 1.1 · Turtle · W3C DCAT · DataCite · ISO/IEC 9075 · NIST AI RMF · OWASP Top 10 for LLM Applications · Stanford HAI AI Index · McKinsey State of AI · Gartner Peer Insights — Analytics & BI. First-party numbers on this page are desk logFLF-PFS-20260822only.
How to cite this page
Page: Zhu, W., & InfiniSynapse Data Team. (2026). Parquet Files: Bind, Then Replay. InfiniSynapse
Run: InfiniSynapse Data Team. (2026). Desk log FLF-PFS-20260822 (sanitized composite)
Neither is an audit. Cite those published artifact counts when you quote parquet files figures from this first-party sanitized desk run. As of 2026-08-29, no independent evaluation, media citation, or reproduction of the zip-versus-grain contrast exists. DuckDB Parquet guide, DataCite, and W3C DCAT stay citable as published files. They do not replace this first-party desk log. Cite those hosted catalogs only as their own published series now. Keep that limit visible here now for later readers of this pack and for later reviewers of the same first-party artifacts on this desk run. Do not treat those hosted notes as a score. Do not invent a news mention this page does not have as of this retrieval date. Send contradictions to zhuhl@infinisynapse.com.
Frequently Asked Questions
Can any folder of Parquet parts be one source?
Bottom line: No. Parquet files are one source only when grain, date style, and metric meaning match. A zip of unrelated dumps is a pile.
Do I need a warehouse to ask a weekly folder?
Bottom line: No. You need a registered directory, a part list, and a written window. Load a warehouse when many teams need the same parquet files on a schedule.
What if one week drifted?
Bottom line: Profile that week. Bind a canonical name or exclude it on purpose. Do not hide the drift inside a union of parquet files.
How do I know the run used the parts I meant?
Bottom line: Inspect the part list, excluded files, and row counts against the folder. If those disagree, stop and ask parquet files again with the note corrected.
Should I pick the largest file and ignore the rest?
Bottom line: No. The largest part is not the series. Parquet files as a folder source means the window you will defend, including small complete weeks.
Do OWL, SPARQL, or RDF certify this desk folder test?
Bottom line: No. OWL 2, SPARQL 1.1, and RDF 1.1 describe published posture, not this parquet files desk table.
Did Apache, DataCite, or a news outlet recognize this page?
Bottom line: No. Apache Parquet format on GitHub and DataCite publish the format and citation infrastructure. They did not evaluate InfiniSynapse. There is no media citation of parquet files on this page, and there is no personal LinkedIn to add.
Conclusion
Several parquet files are one source when the grain matches. Register the directory. Profile every part. Ask a written window. Inspect the part list and the count. Keep the folder as the surface until a shared habit earns a warehouse.
When parquet files fail the three tests, split them. Do not union a pile. If you want to try that check on a sanitized weekly folder you already own, open InfiniSynapse and ask the same window on the series you just authorized.