llms.txt Checker: Inspect Hints Without Access Claims
Use an llms.txt checker to inspect status, content type, and links; queue defects without claiming crawler access, obedience, discovery, or AI citations.
Author credentials: William Zhu is cofounder of InfiniSynapse (GitHub @allwefantasy · auto-coder). Desk: shipping SEO Health and the /en/tool/ visibility pages. No personal LinkedIn published. About: team / editorial standards.
Publisher credentials: InfiniSynapse has public profiles on GitHub, YouTube, and X. A 2026 WAIC Future Tech OPC excellence award covers the Agentic Data Infra entry (WAIC; third-party recap: Xinhua / Caohejing). That award does not review this page or SEO Health. Method CLI: infinitegrowth on npm. Archive: recognition and scope notes.
Run the LLMs TXT Checker
Validate a public URL or pasted file against the 2026 llms.txt v2 proposal. Only the project H1 is required; summaries and file lists are reported as recommendations.
A bare domain checks /llms.txt. A complete .txt path is kept, including v2 files under /docs/. Public HTTP(S) URLs only; private networks and nonstandard ports are blocked.
On this page
By William Zhu · Cofounder, InfiniSynapse · Last updated: 2026-09-11 · Last verified: 2026-09-11 · Methods: Requested /llms.txt on eight public hosts; recorded status, content type, bytes, first signal, and unique absolute-link count. JSON-LD parsing is completed locally; missing types or unresolvable entities can become an InfiniSynapse punch list. Evidence observed 2026-09-11; not an official Google score.
Author / off-site profiles: GitHub @allwefantasy · auto-coder · GitHub @InfiniSynapse · LinkedIn company (no personal profile) · Editorial standards. No personal LinkedIn or vendor badge.
Reviewed by: InfiniSynapse Data Team · method review 2026-09-11. First-party method review.
Trust / COI: About · Corrections · Publishing principles · Privacy · Terms. SEO Health is commercial. The dated public probe below reports raw fields and limits. The InfiniSynapse Data Team publishes this method.
TL;DR
An llms.txt checker reads a public hint file at /llms.txt. It is not a robots.txt twin. Presence is not crawl access. A hint is not rich-result eligibility. Traffic lights are not a Google 100.
Direct answer: Use an llms.txt checker to see whether a hint file exists and whether its links resolve. Use the robots tool for allow and disallow. Do not treat the hint as policy.
What you'll learn:
- Why an llms.txt checker is a hint-file read, not a crawl-policy engine
- How robots.txt and RFC 9309 stay the allow/disallow book
- A dated public probe with raw fields, status handling, and explicit limitations
- When a missing hint is optional, not a markup punch list
The social card at ./images/og-cover.png matches the hero. Paste a public URL at infinitegrowth.agency/seo-tools#check. Do not paste secrets.
We evaluate an llms.txt checker hands-on as the InfiniSynapse Data Team. Our hint-file review records response and link facts; an optional task cannot turn absence into a schema defect.
What an llms.txt checker is
Key Definition: An llms.txt checker is a local, deterministic read of a public llms.txt hint file—present or absent, links resolvable or not. It is not a robots.txt twin, not a sitemap, not an official Google health score, and not a crawl-access grant.
Observed page CLI (2026-09-11, infinitegrowth@0.1.1): seo-health check https://llmstxt.org/ --format json --lang en exited 0. issues[].status listed Title Length (warning), Meta Description (warning). Process exit 0 is not a clean page.
issues[].name | issues[].status |
|---|---|
| Title Length | warning |
| Meta Description | warning |
| H1 Tag | good |
| URL | good |
| Robots.txt | good |
| Sitemap.xml | good |
| Image Alt Text | good |
| Page Structure | good |
The dated public-page probe below reports raw observations.
Independent citation: According to [robots introduction](https://developers.google.com/search/docs/crawling-indexing/robots/intro), a robots.txt file tells crawlers which URLs they may fetch; it is not a noindex directive. The llms.txt checker page still treats that source as independent. Google's robots introduction page is the third-party rule this write-up holds to. The dated probe below is evidence, not that rule.
Robots.txt is the policy file crawlers already know. A check that starts there is already on the wrong file. Open the robots.txt checker when the question is allow or disallow.
RFC 9309 is the Robots Exclusion Protocol. This check does not implement that protocol. A hint file cannot override a Disallow. Presence of /llms.txt does not mean GPTBot may fetch.
Google’s robots introduction is the crawl-policy book for Googlebot. This check is not that book. Keep the books separate.
Plain text is what the hint file usually is: lines, links, optional prose. A check that treats the file as JSON-LD will invent a type that was never shipped.
The llms.txt checker stays on the hint. The hub schema markup audit is the structured-data job. This page is a sibling file job, not a @type list. A hint file is not a structured data tool for AI agents.
A hint is not a notification protocol
W3C Linked Data Notifications describe a inbox protocol for messages. MDN’s Link header is another pointer mechanism, and it still is not a robots grant. This check is not that protocol. It does not prove a model received your hint. It proves the file was fetchable on the day you checked.
Node.js file-system docs are how teams read a file they already wrote. This check should fail the same way—show missing, empty, or broken links—then stop inventing crawl rights. A service-case traffic story is not product proof; it is not product proof that a hint file is policy.
What this check will not do
The llms.txt checker will not parse Article dates. That is Article schema SEO. It will not score experience. An EEAT checker is a different surface. It will not draw a sitemap. Use sitemap for SEO when the question is URL discovery.
A hint-file framework
Keep the hint optional. Keep robots as policy. Keep markup on its own hub. An llms.txt checker that mixes those layers will sell markdown as an allow list. A ticket that mixes those three layers will sell a markdown file as an allow list.
Read the file, do not invent policy
Chrome extracts structured data locally on HTML. The llms.txt checker is a different extract: a text file at a well-known path. Do not paste /llms.txt into a JSON-LD pretty-print and call it schema.
Paste the HTML URL at infinitegrowth.agency/seo-tools#check for the eight modules on the page that links the hint. Those lights still apply after an llms.txt checker pass on the HTML page. An SEO health checker pass is the cheap companion, not a substitute for the robots tool.
Compare the hint to robots, then stop
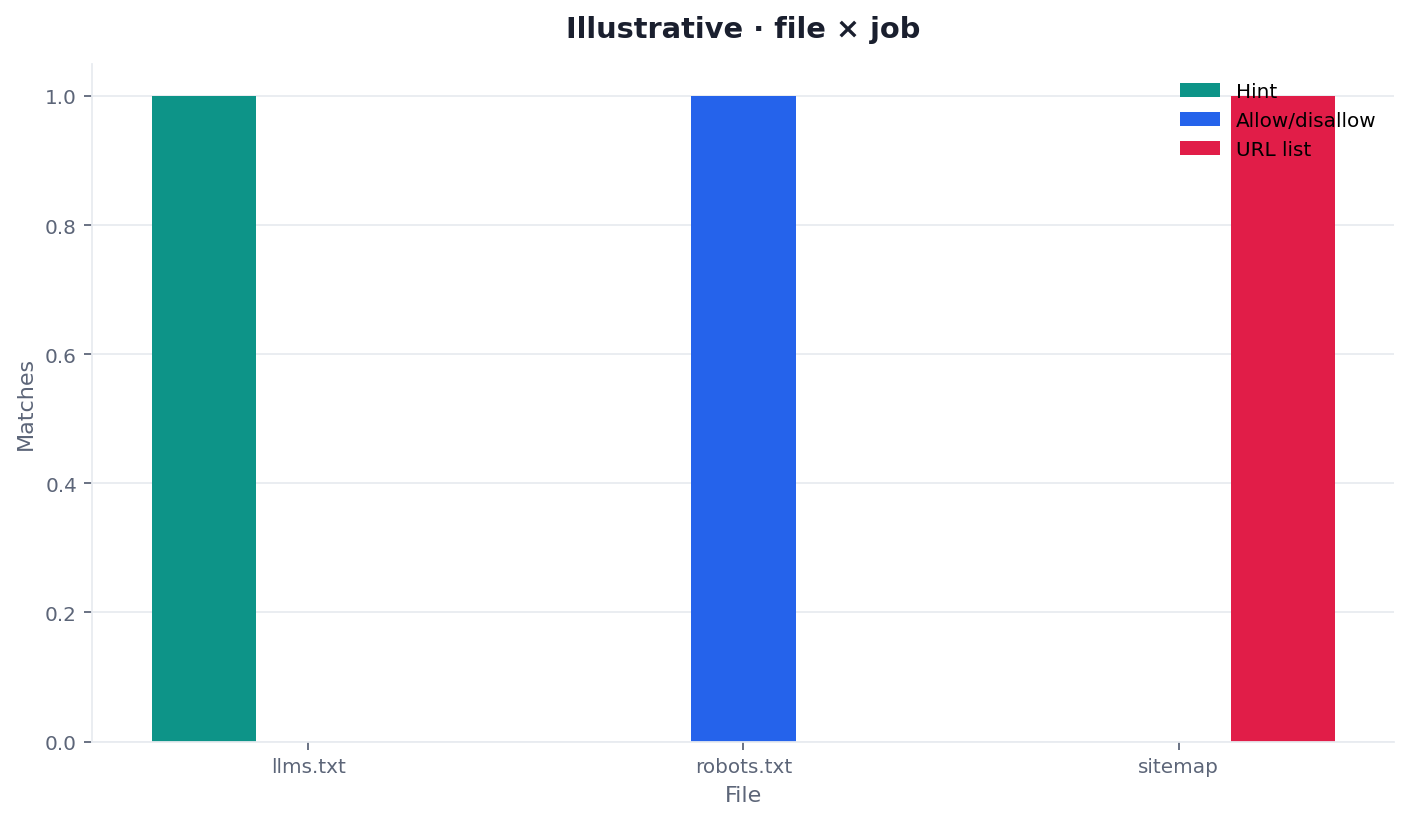
If robots.txt disallows a path the hint lists, the hint lost. The file read should say “hint present, policy denies.” It should not say “models will read this.” For the three-file map, open llms.txt vs robots vs sitemap.
Eight lights still apply on the HTML page
A site can ship a polished llms.txt and still fail title, canonical, or speed on the pages it names. A file read that ignores the eight modules will celebrate a text file on a blocked host. Traffic lights are not a Google 100. An llms.txt checker still only read a hint.
llms.txt checker versus a robots twin
A twin would share semantics. The llms.txt checker must refuse that sale. Robots is policy. The hint is optional documentation.
Allow lists stay in robots
GPTBot allow and disallow belong in robots. Open GPTBot robots allow list when that is the ticket. A ticket that edits User-agent: GPTBot is already on the wrong file. Use the robots.txt checker to prove the policy you shipped.
Access audits stay on user agents
Who may fetch is a public-user-agent question. Open AI crawler access audit when that is the ticket. This check does not impersonate a bot. It reads a hint file.
Landscape of hint files and crawl policy
The landscape is hint files, robots policy, sitemaps, and CDN blocks. An llms.txt checker stays on the hint. Only the hint is this page’s Target. Do not retarget robots.txt checker or sitemap for SEO as this page’s keyword.
The llms.txt checker is closer to a file listing than to a chat. It should fail loud when the path 404s, when links 404, or when the file is HTML error chrome. Prefer a short list of public docs over a dump of every URL in the sitemap.
Cloudflare or WAF blocks are a different layer. A hint cannot override a CDN challenge. That note belongs with crawler-access siblings, not inside this file read as a markup claim.
Query movement after you add a hint still uses Search Console. That overlay is a sister job. It does not prove a model read the file. It does not grant rich-result eligibility.
Some hosts also ship /llms-full.txt. An llms.txt checker still treats that as a hint, not robots. Markdown versus plain text does not change the job. A locale-specific hint does not replace a locale-specific robots.txt rule. If /zh/ is disallowed, a Chinese paragraph in llms.txt cannot override it.
Broken absolute links are the usual desk miss. Relative links that resolve on a docs subdomain but 404 on the apex are the second. Record the host you fetched. Re-fetch after a docs move. The seo-health CLI (npm i -g infinitegrowth) can fail a pull request when an HTML template drops @type. That gate is markup. A missing hint file is not that gate.
How to run the local check
Run the llms.txt checker as four inspectable steps. JSON-LD parse is local. A missing hint file is optional; only broken links inside a fetched text response belong in this checker result.
That method sentence stays on structured data. The hint file is a different object. Do not turn a missing llms.txt into an InfiniSynapse markup ticket.
Step 1 — Fetch the well-known path
Request https://example.com/llms.txt on the host you ship. An llms.txt checker that reads a staging file you never deploy is theater. Record status code and content type.
Step 2 — Confirm it is a hint, then walk the links
Confirm the body is the hint you intended, not a CMS 200 of a homepage. Walk the listed URLs. An llms.txt checker that stops at “file exists” will hide a list of 404 docs.
Step 3 — Prove robots separately
Open the robots txt check on the same host. Write allow and disallow for the public user agents you care about. An llms.txt checker does not replace that step. If GPTBot is the ticket, leave this page after the hint read.
Step 4 — Keep markup on the hub
If the question is a missing Article or Organization type, leave the hint. Open the schema markup audit. Chrome extracts structured data locally on those HTML URLs. Paste a public HTML URL at infinitegrowth.agency/seo-tools#check if you also need the eight lights.
Do not present a missing hint as an official Google score. Do not present a service-case traffic story as crawler-file proof.
Independent citation 2: According to [Linked Data Notifications](https://www.w3.org/TR/ldn), this W3C document is an independent web-standards reference, not a ranking certificate. A second independent source, from W3C, keeps this page claim from resting only on first-party lights.
Public llms.txt probe: eight hosts, status and link count
Observed sample (2026-09-11, InfiniSynapse Data Team): We requested /llms.txt on eight public hosts with one desktop user-agent, recorded HTTP status and content type, and counted unique absolute HTTP links in the returned body. A non-200 row was not parsed as a missing hint.
| Host | HTTP | Content-Type | Bytes / unique absolute links | First returned signal |
|---|---|---|---|---|
| llmstxt.org | 200 | text/plain | 637 / 3 | # llms.txt |
| cloudflare.com | 200 | text/plain | 17,176 / 90 | # Cloudflare |
| vercel.com | 200 | text/plain | 3,797 / 19 | # Vercel |
| docs.anthropic.com | 308 | text/html | 9 / 0 | redirect body /llms.txt |
| openai.com | 403 | text/html | 9,896 / 1 | access-denied HTML, not inspected hint |
| perplexity.ai | 403 | text/html | 5,645 / 2 | challenge HTML, not inspected hint |
| shopify.com | 200 | text/plain | 12,520 / 75 | # Shopify |
| developers.google.com | 404 | text/html | 45,613 / 42 | HTML error page, not hint links |
Status and content type come before link validation
The Google 404 body contains many absolute links because it is an HTML error page. Counting those as hint links would be a false positive. The OpenAI and Perplexity rows are 403 responses; they do not prove the hint is absent. Anthropic returned 308 in this no-follow observation and needs redirect handling before body validation. Only the four 200 text/plain rows were valid candidates for heading and link checks.
Reproduction and limits.
Request exactly https://HOST/llms.txt, save final status before redirects, content type, body byte length, first line, and absolute-link count. Then resolve links only for 200 text responses. One network location and user-agent can receive different edge behavior from another. The probe says nothing about crawler obedience, model ingestion, training, ranking, or citations.
An llms.txt checker should retain the status and content type beside every result. Repeat the llms.txt checker after redirects or documentation migrations.
Selection scorecard
Use this scorecard to keep an llms.txt checker inside its job. Each row is inspectable. None of the rows is an official Google health score.
| Test | Pass | Fail |
|---|---|---|
| File is the hint | Public /llms.txt text | Homepage HTML 200 |
| Links resolve | Listed URLs fetch | Stale dump |
| Policy stays in robots | Robots tool used | Hint treated as allow list |
| Hint-file scope | Hint presence + links | Robots twin |
| Markup left on the hub | Types audited on HTML | Hint filed as schema |
A row that fails the twin test is a policy ticket. A row that fails the markup test is a category error.
Failure modes that twin the files
Most disappointment after an llms.txt checker is a category error. The hint was never robots.txt. If the host is Nuxt, the public HTML pass is Nuxt SEO and llms.txt.
Inventing crawl access from a present file
A present hint can sit next to a Disallow. An llms.txt checker should say “hint present, policy denies.” It should not say “models will train on this.” Do not attach an invented citation percent.
Filing a missing hint as a schema gap
llms.txt is optional documentation. A ticket that opens an InfiniSynapse punch list because the file 404s is mixing books. Missing Article or Organization types are markup tickets. A missing hint is a product choice.
The hint-file handoff starts only after the deterministic response is retained. SEO Health preserves syntax, robots, and llms.txt responses as deterministic observations before any task is created. Teams may upload parsed defects server-side into an InfiniSynapse Server API long-task workspace, where the InfiniSynapse API layer converts broken links, wrong content types, and contradictory hints into a human-ready fix queue. It does not revalidate Google eligibility or prove crawler behavior.
Read the hint, then prove robots separately
Fetch /llms.txt on the host you ship. Use the robots tool for allow and disallow.
Run SEO Health CheckerFrequently Asked Questions
Does a present llms.txt mean models may crawl?
Bottom line: No. An llms.txt checker reads a hint file. Allow and disallow live in robots.txt. Use the robots tool.
Is the hint an official Google score?
Bottom line: No. Traffic lights are eight modules on a pasted HTML URL. An llms.txt checker is a file read. Neither object is an official Google health or EEAT score.
Does a hint replace sitemap or schema?
Bottom line: No. Discovery stays in the sitemap tool. Types stay on the schema markup audit. Keep the llms.txt checker on the hint.
When does InfiniSynapse write a punch list?
Bottom line: JSON-LD gaps can be a credited long-task list. An llms.txt checker does not spend that budget because a hint file is missing.
Conclusion
An llms.txt checker earns trust when it reports a hint file, resolvable links, and the robots book beside it—and stops before twin theater. Read the file. Prove policy in the robots tool. Leave markup to the hub. Open the InfiniSynapse web app only when you want a structured-data punch list written as a task. Then paste the live HTML URL again and keep the eight lights honest.
William Zhu · Cofounder, InfiniSynapse · GitHub @allwefantasy
Desk-validated SEO Health methods. Corrections: zhuhl@infinisynapse.com · corrections policy.