First Question to Ask Your Data: Bind, Then Replay
By William Zhu (independent public engineering profile: GitHub @allwefantasy; no personal LinkedIn) & the InfiniSynapse Data Team · Published: 2026-08-22 · Last updated: 2026-08-29 · Last verified: 2026-08-29 · Next review: 2026-11-29 · About · Editorial standards · Privacy · Terms of Service · Publishing terms · Corrections
Table of Contents
- TL;DR
- What the First Question to Ask Your Data Is
- A Framework for a Known Grain
- How the First Ask Differs from Demos and Tickets
- Tool Landscape for the First Ask
- Independent Public-Data Trial
- How to Ask One Known Grain
- Desk Sample: Two Passes on One First Tuesday
- Scorecard: Ready for the First Ask
- Failure Modes on Day One
- How to cite this page
- Frequently Asked Questions
- Conclusion
TL;DR
We evaluate these patterns at the InfiniSynapse desk on sanitized composites; first-party figures on this page are desk log ADR-FQA-20260825, not customer uplifts and not a third-party bake-off.
Direct answer: The first question to ask your data after signup is a grain you already know—this week versus last week, same filter you would say in the room—asked on a sanitized or authorized source, then opened as a number, a filter, and a file.
What you'll learn:
- Why the first question to ask your data is a known grain, not a new metric
- How demos, tickets, and a reopenable first ask differ when you do not write SQL
- A four-row first sentence that keeps the window honest
- What to open after signup so you do not brief a paragraph
- When the first ask is enough and when you stop
Download evidence: desk log · aggregate CSV · verify script.
If you cannot write a JOIN, you still own the first Tuesday. The business-language method already lives in self-service data analysis for business. This page is narrower: the first question to ask your data is a grain you already know. A fluent paragraph you cannot reopen is just a faster way to be wrong on day one.
What the First Question to Ask Your Data Is
Key Definition: The first question to ask your data is a known grain you can already say out loud, asked on an authorized or sanitized source in plain language, then opened as the number, the filters, and the supporting table before you invent a new metric or brief a room.
In plain language: the grain is the window, the entity, and the warehouse or SKU group you already say in stand-up. A collision is a filter the room never named. A label is the metric sentence in the bound note. The method is known decision → sanitized source → filter → file. The first question to ask your data only counts if you can reopen those objects, not if the onboarding tour sounded complete.
Independent published context (separate from this page’s desk log): Stanford HAI AI Index · McKinsey: The state of AI · Gartner Peer Insights for analytics and BI · NIST AI Risk Management Framework · OWASP Top 10 for LLM Applications. Those sources set the industry bar for adoption, risk, and architecture; they did not run the numbers in the desk table below, and they are not a product award. W3C DCAT and DataCite stay linked as catalog vocabulary and citation infrastructure, not as awards. There is no DataCite DOI for this desk log. Retrieved 2026-08-29.
That definition sits next to a public OLAP (retrieved 2026-08-29) idea: analysis assumes a grain. Wikipedia’s OLAP note is useful because it treats grain as a precondition, not as a product feature. Day one does not invent one. It reuses the grain you already run the meeting on. There is no personal LinkedIn. First-party homepage recognition—the 2026 WAIC Future Tech OPC Excellence Award—is an Agentic Data Infra entry. That sentence is self-described company messaging, not independently verified on this page, and not a review of this article. The author’s public qualification on this page is the inspectable GitHub @allwefantasy engineering profile plus the 2026-07-29 methodology attestation. There is no professional certification and no third-party endorsement of the author to add.
Notice what the definition leaves out. The first question to ask your data is not “tell me something interesting.” It is not a migration. It is not a promise you will never need an analyst. It is a right plus a check: you can ask a known comparison, and you can see how the number was made.
A founder’s first question to ask your data can be “Is cash collected this week covering the burn we planned?” A product manager’s first question to ask your data can be “Did activation drop after last Tuesday’s release, same cohort as last week?” An operator’s first question to ask your data can be “Which warehouse drove late ships this week versus last week?” None of those sentences is a new metric. All of them are grains you already know.
If you want the sentence shape, read how to ask data in plain language. If the weekly object is a PM pack, use data analysis for product managers. If intake is the pattern, read chat with your data. If you are still browsing, use exploratory data analysis. If you want the agent primitive, read What Is a Data Agent. If the first file is columnar, the Parquet (retrieved 2026-08-29) documentation is enough background for why that upload can answer a known grain.
The NIST artificial intelligence (retrieved 2026-08-29) pages—and the more specific NIST AI Risk Management Framework (retrieved 2026-08-29)—are useful context for why a first ask is still an AI-assisted number that needs a bound definition. They will not write your grain. The first question to ask your data still needs that grain.
A Framework for a Known Grain
The first question to ask your data gets easier when the sentence has four parts. SQL is optional because someone—or an agent—can produce the statement. Your job is to keep day one honest.
| You write | Why it works | What to open after |
|---|---|---|
| The known decision | “We already compare this week versus last week on returns.” | The grain and the window |
| The known metric sentence | “Return units are returned units this week, same definition as last week.” | The filter list |
| The comparison you already say | “This week versus last week, same warehouse.” | The two result tables |
| The stop rule | “If I do not know the grain, I will not invent one.” | The bound note, or you stop |
The first question to ask your data is mostly those four rows. You do not need a new metric after signup. You do need the sentence you already use. Signup fails when it becomes a tour of every table.
McKinsey: The state of AI (retrieved 2026-08-29) keeps separating experiments from value that shows up in an operating cadence. Read that split as a day-one test: if next Tuesday cannot rerun the same grain, you ran a demo, not an evaluation.
Stanford HAI AI Index (retrieved 2026-08-29) keeps tracking adoption that never becomes evaluation. The first question to ask your data is evaluation: same source, same grain, same stop rule.
Apache Arrow (retrieved 2026-08-29) is useful context for why a file you upload can still be a columnar table. Arrow explains the memory layout; it will not choose your grain. Day one still needs that choice.
How the First Ask Differs from Demos and Tickets
Teams already have three habits after signup. Only one of them is the first question to ask your data.
Waiting for a perfect warehouse
You defer the first ask until “the model is ready.” That is a program. It can be wise later. It is not the first question to ask your data, because a known grain already exists on a source you can sanitize.
Clicking every demo tile
You tour sample dashboards and call it onboarding. You may learn the UI. That is not the first question to ask your data. A tour is not a grain. Day one is the sentence you would say on Tuesday without the product.
Asking one known grain you can reopen
You select a sanitized sample or an authorized source, write the comparison you already know, and open the table the task wrote. That is the first question to ask your data. You still did not write SQL. You did accept the duty to look.
If the first file is a lake extract, continue in Parquet data analysis. Day one still ends in the sentence you will say out loud.
Tool Landscape for the First Ask
Ignore the vendor aisle for a minute. Ask what object you will hold after the first question to ask your data.
Certified dashboards are fine for questions someone already designed. They are a poor first ask when you need to prove you can reopen a number. Spreadsheet exports are fine if you say they are a snapshot. ChatBI tools are fast and often hide the statement. A data agent that connects the source you authorize, binds a short known-grain note, and leaves a file you can download is the shape that matches the first question to ask your data.
Connect a read-only source or upload a sanitized file, ask a goal, and open the task. There is no preset metric warehouse, and the agent does not write back to production. That boundary is a feature: the first question to ask your data does not require you to become an engineer.
What you should see after signup
After one ask, the first question to ask your data should leave you with: the restated goal, the filter list, a table or chart, and a file. If you only have a paragraph, you are not done.
The WCAG 2.1 quick reference (retrieved 2026-08-29) is a useful reminder that the file you keep should be openable by the people who will brief it. Accessibility here is practical: a screenshot a reviewer cannot replay is not a first-hour artifact. Use WCAG as texture, not as a score for your last number. Day one still ends in the spoken sentence.
When the first ask is enough
The first question to ask your data is enough when you can say the grain, open the filter, and keep the file. It is not enough when you invent a metric to impress the room. Stop and write the known grain again.
Gartner Peer Insights — Analytics & BI (retrieved 2026-08-29) is useful texture for how buyers describe that first-hour gap. It did not run your signup ask.
Independent Public-Data Trial
The safest day-one evaluation uses a source whose publisher, fields, and release are independently documented. The NYC Taxi and Limousine Commission trip records (retrieved 2026-08-29) provide monthly files with pickup times, locations, distances, and fares. The World Bank World Development Indicators (retrieved 2026-08-29) provide named indicators by country and period. The U.S. Data.gov catalog (retrieved 2026-08-29) offers additional government datasets with publisher metadata. These sources are independent published series a reviewer can reopen without InfiniSynapse; they are not a score for the desk table below. They let a new user test filters, dates, grain, and totals without uploading confidential records.
Your first question to ask your data should have an answer that can be checked directly. For taxi records, ask for trip counts by pickup zone for one published month, with a stated date boundary and exclusion rule. For World Bank data, ask for one named indicator across a fixed set of countries and years. Do not begin with “find something surprising.” Begin with a comparison that has a visible source and an expected shape.
Use this independent protocol:
- Record the publisher, dataset name, release or period, retrieval date, and file checksum when available.
- Write the expected grain, time window, filters, exclusions, and output columns before the run.
- Save the restated goal, generated table, filter list, and downloadable file.
- Repeat the same request in a fresh task without copying the first answer.
- Recalculate one subtotal with a spreadsheet, notebook, or database query.
- Ask someone outside the buying decision to compare both runs with the source.
A pass means the source, grain, filters, row shape, and subtotal agree in both runs. A result fails if local dates shift silently, null records disappear without disclosure, geographic codes change meaning, or the answer provides a percentage without its numerator and denominator. The failure should remain in the review record because it identifies the definition or control needed before private data is connected.
Third-party data is not third-party endorsement
NYC TLC, World Bank, Data.gov, Apache, W3C, NIST, Stanford, McKinsey, Gartner, and OWASP provide public data, standards, documentation, or research. None endorses InfiniSynapse, reviewed this page, or ran desk log ADR-FQA-20260825. Linking an authoritative publisher establishes where a definition or test input came from; it does not create a customer testimonial.
William Zhu’s public GitHub profile makes the author identity inspectable, and the editorial standards identify internal reviewers. For stronger independent assurance, ask a data owner or analytics engineer outside the vendor-selection team to sign the source, grain, filter, and recalculation checklist. A named, reproducible review is more useful than an unattributed quote.
Privacy and onboarding boundary
Public data is appropriate for learning the workflow, but a production trial still needs authorization and minimization. The NIST Privacy Framework (retrieved 2026-08-29) offers a risk-management structure for identifying and governing personal data. Start with the least sensitive source that can test the known comparison. Do not upload credentials, raw personal records, health information, payment details, or unrestricted production exports merely to complete onboarding.
How to Ask One Known Grain
Do this on a sanitized sample or a source you already authorize. Do not wait for a migration. Day one starts the day you sign up.
Write the grain you already know
Bad: “Explore the database.” Better: “This week versus last week, return units, same warehouse we already use in stand-up.” The first question to ask your data starts when the comparison already exists in the room. If it does not, you are inventing.
Point at a sanitized or authorized source
Pick a sample, a live database you may use, or a sanitized file. A secret-filled export is a control failure. If the file is a snapshot, say so: “This file is a Tuesday sample.”
Open the number, then decide if you can brief
Read the filter. Read the window. Open the table. Then write the one sentence you would say out loud. Day one ends in that sentence, not in the onboarding tour. If you cannot say the filter out loud, you cannot brief the number.
Recalculate one subtotal
Choose one location, period, or entity and compute its subtotal outside the generated answer. Record null handling, date boundaries, and exclusions. If that small check fails, stop before connecting a private source.
Save the day-one evidence
Keep the question, source identifier, grain, filters, result, and recalculation together. When the first sentence is written, ask it and keep the file. That is the first question to ask your data diagnostic. Day one is repeatable only if next week can reuse the same grain.
Desk Sample: Two Passes on One First Tuesday
This is a first-party InfiniSynapse desk log of a day-one signup pack, not a named-logo customer case and not an uplift claim. Run ID: ADR-FQA-20260825. Date: 2026-08-25 (Tuesday). Operator: InfiniSynapse Data Team. Attestor: William Zhu. Sources: a sanitized Monday returns export, about 1,050 return units across two complete weeks in Warehouse West, plus a one-page note that locked return units (marketplace included, same warehouse). Contrast: browsing the catalog versus a known stand-up grain. Download the same numbers as desk log ADR-FQA-20260825, the aggregate CSV, and the verify script. The script only checks published rows; it is not a third-party audit.
An ops lead chose a first question to ask your data after signup: “Which SKU group drove return units this week versus last week in Warehouse West, using the sanitized Monday export, same definition we already say in stand-up?” The first pass browsed sample tiles. Grain named: 0. Filter opened: 0. File opened: 0. That catalog tour is not the first question to ask your data.
The same goal was then walked as a known grain. The grain was restated as SKU group × week × warehouse. The result table showed 640 return units this week and 410 last week, with one bundle group contributing 180 of the increase. Marketplace returns were included. Grain named: 1. Filter opened: 1. File opened: 1. The lead kept the file instead of a screenshot.
No customer uplift is claimed. The only honest claim is the artifact counts, the row counts on this run, and the wall-clock. The win was a reopenable grain, not a hero chart.
| Retrieval state | Grain named | Filter opened | File opened |
|---|---|---|---|
| Browse the catalog | 0 | 0 | 0 |
| Known stand-up grain | 1 | 1 | 1 |
Wall clock for the successful pass was about five minutes (warehouse time excluded). The clock started when the operator wrote the standing grain and ended when the restated filter, the two week tables, and the file sat in one folder. Cite this table as InfiniSynapse desk log ADR-FQA-20260825. Do not cite it as customer ROI, a bake-off win, or a Wikipedia / Gartner / Stanford / McKinsey experiment. We do not publish named-logo customer cases on this page. The 1,050 return units and the 410 / 640 / 180 split are this desk run’s inputs, not a customer extract.
Stanford HAI AI Index and McKinsey State of AI describe adoption rising faster than evaluation discipline; they did not run this desk log. Those published surveys are the industry data you may cite for context. They are not a score for this page.
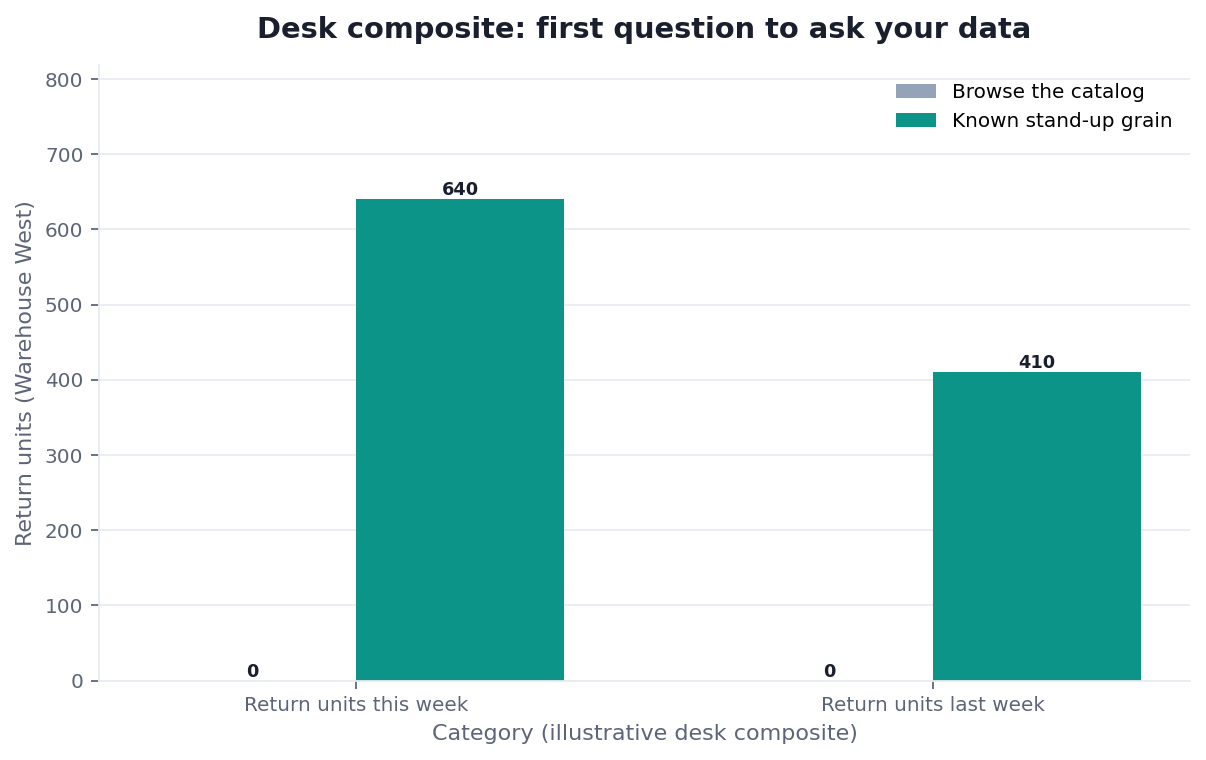
Figure. InfiniSynapse desk log ADR-FQA-20260825: catalog browse left 0 / 0 / 0; known stand-up grain left 1 / 1 / 1 (410 vs 640 return units; one bundle added 180). Published context: the independent sources linked in the body. Not a customer experiment, SLA, or official benchmark.
| Evidence class | What you can cite | What you cannot claim |
|---|---|---|
| Desk log on this page | Artifact counts 0/0/0 → 1/1/1, 410 vs 640 return units, one bundle +180, ~1,050 lines on this run, ~5 min wall-clock, downloadable log · aggregate CSV · verify script | Customer uplift %, vendor bake-off win, named-logo case |
| Published authority (linked above) | Independent series from NYC TLC, World Bank WDI, and Data.gov; category notes from Wikipedia OLAP, Parquet, Apache Arrow, NIST AI, and WCAG 2.1; adoption and risk from Stanford HAI, McKinsey, Gartner, NIST AI RMF, OWASP; catalog and citation infrastructure from W3C DCAT and DataCite | That those sources ran this desk log |
| Homepage recognition | 2026 WAIC Future Tech OPC Excellence Award as published on the company homepage; self-described, not independently verified here | That WAIC, Gartner, or NIST scored this article |
That is the first question to ask your data on day one. No SQL. No new metric. No invented uplift.
Scorecard: Ready for the First Ask
Use this before you announce that the first question to ask your data is done.
| Check | Pass | Fail |
|---|---|---|
| You can write a grain you already know | Ask | You are inventing |
| The metric sentence exists outside the model | Ask | Bind a note first |
| The source is authorized or sanitized | Ask | Stop |
| You can open the filter after the answer | Brief | Do not brief |
| You did not invent a new metric on day one | Healthy | You will over-trust |
| You will keep the file, not a screenshot | Repeatable | Folklore |
The first question to ask your data is ready when four or more rows pass.
Failure Modes on Day One
These three show up before any architecture debate.
Asking for insights instead of a grain
“Tell me something interesting” is not a grain. The first question to ask your data is a comparison you already know.
Uploading a file full of secrets
Someone pastes production credentials or raw customer rows. The first question to ask your data requires a sanitized or authorized source. OWASP Top 10 for LLM Applications (retrieved 2026-08-29) is the reminder that a prompt can leak what you paste.
Inventing a metric to impress the room
Someone asks for a “health score” nobody has defined. The first question to ask your data is the grain you already say out loud.
Before you put a number in the first meeting, check that you can say the grain, the filter, and the source out loud. If any of those is fuzzy, do not brief yet.
Route the same diagnosis to the live guide that owns the next object.
| Live guide | Open it when |
|---|---|
| self-service data analysis for business | you need the business-language method, not only the first ask |
| ask data in plain language | the missing object is the meeting sentence |
| data analysis for product managers | the first grain is a weekly product decision |
| Data Analysis for Operators | Ops needs today’s grain, not a new semantic model |
| Data Analysis for Founders without a Warehouse Team | Five people can ask if the source is already there |
| When to Call an Analyst | Self-serve stops where the grain does not exist |
Ask one known grain on a sanitized source
Connect a sanitized sample—or a source you authorize—and ask the grain you already know. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseHow this page is sourced. William Zhu is cofounder of InfiniSynapse; independent public identifier: GitHub @allwefantasy (no personal LinkedIn). Institution: About InfiniSynapse. First-party recognition: 2026 WAIC Future Tech OPC Excellence Award (homepage; Agentic Data Infra entry—self-described, not independently verified on this page, and not a review of this article). Trust pages: Privacy · publishing terms · NIST Privacy Framework. Desk methodology note: 2026-07-29 attestation. Downloadable first-party run: desk log
ADR-FQA-20260825· aggregate CSV · verify script. Reviewed by analytics engineering · data platform · LLM security · editor. Editorial standards · corrections · Company Vision. Contact zhuhl@infinisynapse.com. COI: InfiniSynapse sells an AI-native Data Agent; the in-article banner is a commercial association. Fact-check: Stanford HAI AI Index · McKinsey: The state of AI · Gartner Peer Insights — Analytics & BI · NIST AI Risk Management Framework · OWASP Top 10 for LLM Applications · Wikipedia OLAP · Apache Parquet docs · Apache Arrow docs · NIST AI overview · WCAG 2.1 quick reference · NYC TLC trip records · World Bank WDI · Data.gov catalog · W3C DCAT · DataCite. First-party numbers on this page are desk logADR-FQA-20260825only.
How to cite this page
Page: Zhu, W., & InfiniSynapse Data Team. (2026). First Question to Ask Your Data: Bind, Then Replay. InfiniSynapse
Run: InfiniSynapse Data Team. (2026). Desk log ADR-FQA-20260825 (sanitized composite)
Neither is an audit. Cite those published artifact counts when you quote first question to ask your data figures from this first-party desk comparison. As of 2026-08-29, no independent reproduction of this day-one contrast exists. DataCite and W3C DCAT stay citable as catalog and citation standards. Keep the desk log, the aggregate CSV, and the verify script beside that citation. First question to ask your data citations should name the run ID, not a fluent restatement of a screenshot. Reopen first question to ask your data after those files. Name first question to ask your data quotes. Send contradictions to zhuhl@infinisynapse.com.
Frequently Asked Questions
Do I need SQL for the first question to ask your data?
Bottom line: No. The first question to ask your data is a known grain in plain language. You still need to read a filter list and a time window. That is literacy, not engineering.
Should the first ask invent a new metric?
Bottom line: No. The first question to ask your data is a grain you already know. Inventing a score after signup is how you brief folklore.
What source should I use after signup?
Bottom line: Use a sanitized sample or a source you already authorize. Day one fails if the file is full of secrets.
When is the first ask enough to brief?
Bottom line: When you can open the filter, restate the grain, and keep the file. Day one is not enough if you only have a paragraph.
What public data should I use for an independent trial?
Bottom line: Use a documented official dataset with a fixed release, visible fields, and a subtotal you can reproduce—such as NYC TLC trip records or a named World Bank indicator.
Do the external institutions endorse this article?
Bottom line: No. They provide data, standards, documentation, or research. No linked organization is represented as a customer, certifier, or independent reviewer of InfiniSynapse.
Did NIST, Gartner, or a news outlet recognize this page?
Bottom line: No. The NIST AI Risk Management Framework and Gartner Peer Insights for analytics and BI publish risk language and buyer texture. They did not evaluate InfiniSynapse. There is no independent award page for this article, no media citation of this signup guide on this page, no professional certification for the author, and there is no personal LinkedIn to add.
Conclusion
The first question to ask your data is a day-one habit: write a known grain, point at a sanitized or authorized source, open the filter, keep the file. You do not need a new metric. You do need the courage to refuse a paragraph you cannot reopen.
Use the scorecard on the first number you generate. If you cannot say the grain out loud, you are not ready.