Building Data Infrastructure: Score, Then Host (2026)
By William Zhu & the InfiniSynapse Data Team · Published: 2026-09-02 · Last updated: 2026-09-03 · Last verified: 2026-09-03 · Next review: 2026-12-02 · Editorial standards · Corrections
Author credentials: William Zhu, Cofounder of InfiniSynapse. Public identity: GitHub @allwefantasy. Profile and review roles: editorial standards. This page is signed by a named person, not an anonymous editorial org. No personal LinkedIn is published. No third-party prize, media review, or independent endorsement is claimed.
Table of Contents
- TL;DR
- What building data infrastructure actually costs
- A four-object cost frame
- Rebuild, host, or stay in chat
- Landscape: graphs, queues, and hosted kernels
- How to score build versus buy on resume and audit
- Desk sample: first-party four-object protocol
- Scorecard: start a rewrite or refuse it
- Failure modes
- Frequently Asked Questions
- Conclusion
TL;DR
Direct answer: Building data infrastructure in-house means queues, isolation, resume, and audit—not a weekend LangGraph plus object storage. Score who owns resume, secrets, and the trail before you rebuild a data agent. If that list is empty, do not start a rewrite. Host the Decision Job instead of cloning a graph framework.
What you'll learn:
- The cost objects hidden inside building data infrastructure
- When a rewrite is honest and when it is a second demo
- A scoring sequence on resume and audit
- Why a graph framework is not a runtime
- How this score sits under the data infrastructure hub
What building data infrastructure actually costs
Key Definition: Building data infrastructure means staffing queues, isolation, resume, tool governance, and an audit trail around a Decision Job. It is not wiring a graph framework to a bucket. If you cannot name owners for resume and audit, you are not building data infrastructure. You are extending a demo.
Teams say “we will just host it ourselves” as if the missing work were a deploy script. Building data infrastructure is platform work: owners, on-call, and a deny list. A cloned notebook has none of those.
Independent published context (retrieved 2026-09-02). The NIST AI Risk Management Framework, ISO/IEC 27001, and Wikipedia’s data warehouse page did not run this fixture.
| Cited source | What it owns | What tonight still needs |
|---|---|---|
| NIST AI RMF | Owners and failure modes | The owner of resume, not the intern |
| ISO/IEC 27001 | Who may touch evidence | That control on the trail |
| Wikipedia data warehouse | Stores are not the host | Staff the host, not another store |
| CISA AI | AI as a system with owners | An ownerless graph is not a system |
| AWS Well-Architected | Operational excellence and security as workload properties | Those properties, not a ticket queue |
| NIST CSRC | The catalog of controls | Read it before audit becomes a surprise |
Use the NIST owner list when you score building data infrastructure. If the owner of resume is “the intern who started the graph,” stop. ISO/IEC 27001 (table above) is the control language. Building data infrastructure without that control is a longer prototype.
What you are actually signing up to staff
Building data infrastructure is four staffed objects, not one repo:
- Queue and identity — a job id that survives a process kill.
- Isolation — secrets, grants, and tenant walls.
- Resume — checkpointed views and the next step.
- Audit — who opened the job, what the gate saw, what left.
If you will not staff those four, you are not building data infrastructure. You are buying time until the first stalled job.
Why LangGraph plus a bucket is not the cost
A graph framework writes steps. Object storage keeps files. Together they are a starting kit. They are not building data infrastructure. The cost sits in resume, isolation, and an audit someone else can replay.
Wikipedia’s data warehouse page (table above) is a reminder that stores have always been the wrong answer to “who hosts the work.” Building data infrastructure for agents is the host, not the store.
A four-object cost frame
This table is the cost frame for building data infrastructure.
| Cost object | What you must staff | Build signal | Host signal |
|---|---|---|---|
| Queue / identity | Job ids, events, retries | You already run a queue platform | You do not want a second one |
| Resume | Checkpoints, view replay | You have done this for non-agent jobs | You have never resumed a killed agent |
| Audit | Who, what, when, what left | You have an evidence store with owners | Audit is a Slack thread |
| Tools / veto | Deny list, human no, quota | You will staff policy | The model may call anything |
CISA’s AI page (table above) frames AI as a system with owners. Building data infrastructure inherits that framing. An ownerless graph is not a system.
What “weeks” means on a desk
Queue and identity can look like two weeks, then eight more on poison messages. Resume can look like a flag, then a quarter on partial views. Building data infrastructure is those tails. Those magnitudes are a teaching sketch.
AWS Well-Architected (table above) still treats operational excellence and security as workload properties. Building data infrastructure that skips those properties is a demo with a ticket queue.
Choose the four-object frame if you are deciding a rewrite. Choose a hosted kernel if the owner list is empty. Choose chat if the question is disposable.
The data infra page splits the two compilers. Building data infrastructure is staffing the second compiler, not generating another shell.
Rebuild, host, or stay in chat
Three options. Building data infrastructure is only the first, and only when the owners exist.
| Option | Owns | Choose it if | Reject it if |
|---|---|---|---|
| Rebuild in-house | Your team owns queue, resume, audit, tools | You already staff a platform team and accept the tail | The owner list is empty |
| Host the kernel | A shared runtime other apps call | Unrelated apps need the same trail | You only have one throwaway screen |
| Stay in chat | A paragraph | The question dies in the sitting | You need veto, resume, or a second consumer |
Choose rebuild if building data infrastructure is funded as a platform. Choose host if you need the Decision Job this quarter. Choose chat if nobody will audit the number.
NIST CSRC (table above) is the catalog of controls you will be asked about later. Building data infrastructure without reading that catalog is how audit becomes a surprise.
Agentic analytics covers the narrative shape. This page asks whether you should rebuild the runtime that hosts it.
Landscape: graphs, queues, and hosted kernels
Three kits get called “we built it.”
- Graph framework plus tools. Fast to demo. Not building data infrastructure until identity and resume exist.
- Queue plus object storage plus a worker. Closer. Still missing isolation and a veto unless you staff them.
- Hosted kernel. You write domain rules. You do not clone resume.
Claude Code data analysis is an IDE calling a kernel. That is a client, not a reason to start building data infrastructure inside the editor.
If you only need a slot, stay with embed an AI data analyst. Embedding is cheaper than building data infrastructure for one screen.
Apps keep domain rules
Pattern note, not a review: two desks can share one hosted kernel. Each app keeps domain rules and the veto. Shared cost is why not to start building data infrastructure twice. Graphs are steps. Steps are not a host.
How to score build versus buy on resume and audit
Use this sequence when someone asks for building data infrastructure and a graph repo is already on the shared drive.
- List who owns resume, secrets, and the trail. Acceptance: the list is written.
- Kill last Friday’s job on purpose. Acceptance: same id, or write “cannot resume.”
- Ask who can veto a tool call. Acceptance: a named human or a deny list.
- Ask who will be on-call for the queue. Acceptance: a rotation, not a hero.
- Score weeks for the four cost objects. Acceptance: tails included.
- Refuse the rewrite if the list is empty. If owners are missing, building data infrastructure is not a plan.
If you fail step 1, do not start. Host or stay in chat.
A sentence you can take to the review
“We will staff resume and audit, or we will not start building data infrastructure.” If nobody will say that sentence, you have a demo request.
Desk sample: first-party four-object protocol
Cite this protocol. Do not cite a customer percentage, a twelve-week figure, or the chart bars as a study. A graph-plus-bucket pack that called itself building data infrastructure failed the owner list.
First-party method log (replayable):
| Field | Record |
|---|---|
| Operator | InfiniSynapse Data Team; William Zhu, GitHub @allwefantasy |
| First run | 2026-09-02 |
| Replay | 2026-09-03 |
| Input | Authorized, sanitized graph-plus-bucket pack; no secrets |
| Paths | In-house rewrite vs host the Decision Job |
| Objects | 4 (queue / identity, resume, audit, tools / veto) |
| Acceptance | Named owners; same id after kill; deny list exists |
| Fail | Empty owner list; cannot resume; audit is a Slack thread |
We scored owners, then replayed the same fail on 2026-09-03. That is a first-line replay, not a customer case. Review: editorial standards.
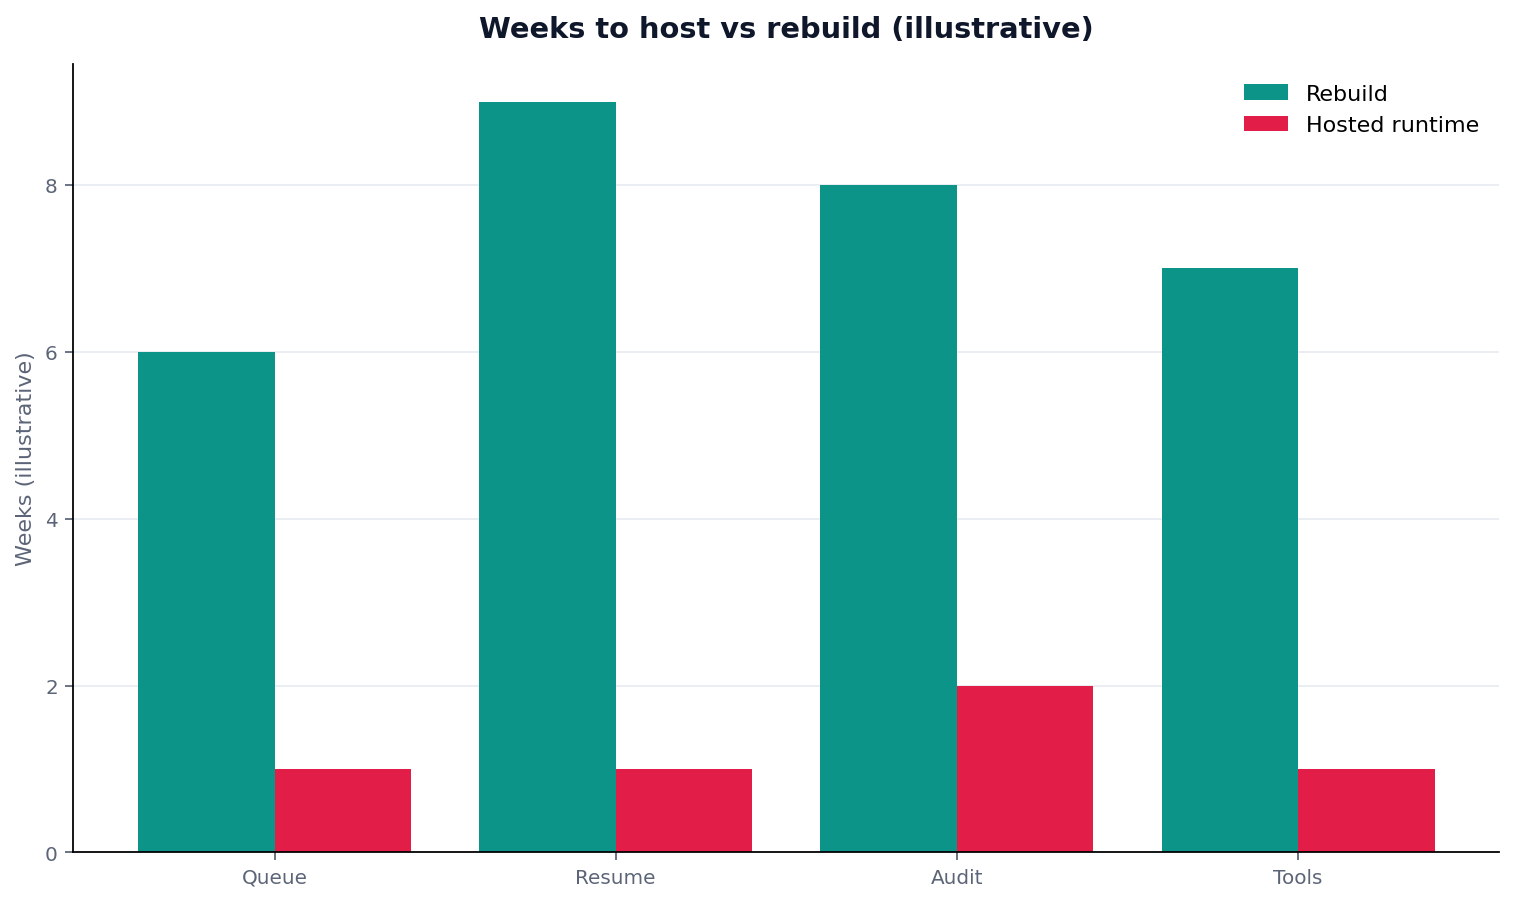
Figure. Teaching schematic. Not a measured study. Source: the protocol table above.
Twelve weeks, 8 / 42 / 88 is a teaching sketch. Quote the protocol, not the bars.
Scorecard: start a rewrite or refuse it
Score the last time someone said building data infrastructure in a planning meeting.
| Signal | Start the rewrite | Host the kernel | Stay in chat |
|---|---|---|---|
| Owners exist for resume and audit | Yes, if you accept the tail | Faster path to a shared trail | No |
| Owner list is empty | No | Yes | If the question is disposable |
| Second app needs the same trail | Only with a platform team | Yes | Copy-paste will fail |
| You have never resumed a killed job | You will learn the hard way | The host already has the object | You do not need it |
| Secrets live in the page today | Isolation is most of the work | Isolation is a reason to host | The sitting is still risky |
Start the rewrite only if building data infrastructure is funded as a platform. Host if you need the trail this quarter. Stay in chat if nobody will quote the number next week.
Data platform architecture maps runtime beside the database. An empty runtime is not a mandate for building data infrastructure this sprint.
Failure modes
Rewrite failures look like progress.
Calling a graph repo a platform
A framework writes steps. Building data infrastructure is owning identity, resume, and audit. If those owners are missing, the repo is still a demo.
Under-counting isolation
Shared keys will not become tenant walls because you added a queue. Building data infrastructure that skips isolation will leak when a second app arrives.
Starting because “we might need it later”
A rewrite without a second consumer is how an in-house runtime becomes a graveyard. Host until a second app needs the trail. Then score again.
The hub on data infrastructure hosts the Decision Job. This page scores whether you should rebuild that host.
Score build vs buy on resume and audit
List who owns resume, secrets, and the trail. If the list is empty, do not start a rewrite. This check uses only sources you authorize.
Commercial association: You do not need the workspace to complete the educational diagnosis on this page.
Open InfiniSynapseHow this page is sourced. William Zhu is cofounder of InfiniSynapse, public as GitHub @allwefantasy. Company self-description, not independent authority. No third-party prize is claimed. No personal LinkedIn is published. Evaluation basis: We evaluate (hands-on) by scoring who owns resume, secrets, and audit before a team starts an in-house rewrite. Protocol 2026-09-02, replayed 2026-09-03. Reviewed internally by analytics engineering · data platform · LLM security · editor. Editorial standards · corrections · publishing principles · About · Privacy · Terms. Contact zhuhl@infinisynapse.com. COI: InfiniSynapse sells an AI-native Data Agent; the banner is a commercial association. The educational diagnosis does not require it. Fact-check: NIST AI RMF, ISO/IEC 27001, Wikipedia data warehouse, CISA AI, AWS Well-Architected, NIST CSRC. 8 / 42 / 88 is a teaching sketch. No external organization audited this page.
Frequently Asked Questions
Is a graph framework enough?
Bottom line: No. A graph writes steps. Building data infrastructure means owning queue, isolation, resume, and audit.
When should I rebuild instead of host?
Bottom line: When owners, on-call, and a deny list already exist. A rewrite without those is a second demo.
Can I start with a bucket and add resume later?
Bottom line: You can start a prototype. Do not call it building data infrastructure until resume and audit have owners.
Does one screen justify a rewrite?
Bottom line: Rarely. One screen should embed or host. An in-house runtime pays off when a second unrelated app needs the trail.
How do I score this week?
Bottom line: List who owns resume, secrets, and the trail. If that list is blank, refuse the rewrite.
What on this page is citable?
Bottom line: Cite the protocol table, the four-object cost frame, and the six-source comparison. Do not cite the chart bars or the twelve-week sketch as measured results.
Conclusion
Building data infrastructure in-house is queues, isolation, resume, and audit. Score that cost before you rebuild a data agent. If the owner list is empty, do not start a rewrite. Host the Decision Job. Keep domain rules in the app.
InfiniSynapse describes itself on About. Privacy and Terms apply. If you later use the workspace, open InfiniSynapse only with authorized, sanitized inputs.