Crawl Budget Optimization: Parameters vs Canonicals
Crawl budget optimization spends crawler time on canonical URLs, not parameter twins. Sample the host, cut waste, then recrawl the keep list you want indexed.
Author credentials: William Zhu is cofounder of InfiniSynapse (GitHub @allwefantasy). Desk: shipping SEO Health and the /en/tool/ visibility pages. No personal LinkedIn published. About: team / editorial standards · Vision.
On this page
By William Zhu · Cofounder, InfiniSynapse · Last updated: 2026-08-19 · Last verified: 2026-08-19 · Methods: first-party sitemap shape counts plus robots Disallow on this hostname — not a claimed Google ranking score or a private GSC export.
Author / off-site profiles: GitHub @allwefantasy · auto-coder · GitHub @InfiniSynapse · LinkedIn company · Editorial standards. Formal public work: InfiniSQL, auto-coder, retrieval systems. Desk: shipping SEO Health and the
/en/tool/visibility pages. No personal LinkedIn, award, or vendor badge.
Trust / COI: About · Corrections · Publishing principles · Privacy · NIST Privacy Framework · Vision. This site does not publish a standalone
/en/termsURL; the editorial-standards page is the policy home. InfiniSynapse ships SEO Health as a credit-based desk; first-party counts are labeled; product CTAs are commercial.
Fact-check: Google — crawl budget · Google — consolidate duplicates · Search Console — canonical URLs · WHATWG URL Standard · RFC 9111 · Google — robots.txt · Stanford HAI AI Index 2025 · G2 SEO tools · Gartner Peer Insights · AgentSpot listing. Corrections: zhuhl@infinisynapse.com.
Dates (match schema): First published 2026-08-16. Last modified 2026-08-19. Desk run 2026-08-11. Last verified 2026-08-19.
TL;DR
Direct answer: Crawl budget optimization is the sitewide work of spending crawler time on canonical URLs instead of parameter twins, session IDs, and facet copies. It is not a sitemap-only cleanup. Cut the waste at links, headers, and duplicates, then recrawl the keep list.
What you'll learn
- A 44-word definition of crawl budget optimization you can quote
- Why parameter URLs burn time the sitemap never listed
- How canonicals, cache, and robots cut demand
- What a 50–500 URL sample should prove after the cut
- The three failures that put the budget back on junk
If the host is already live, open the checker. Paste the host. Read which URL shapes ate the draw. Do not start by rewriting <priority> on a map that still lists filters.
What the sitewide job is
Key Definition: Crawl budget optimization is the sitewide work of spending crawler time on canonical URLs instead of parameter twins, session IDs, and facet copies. It is not a sitemap-only cleanup. You consolidate duplicates, respect cache freshness, and stop minting waste the map never listed.
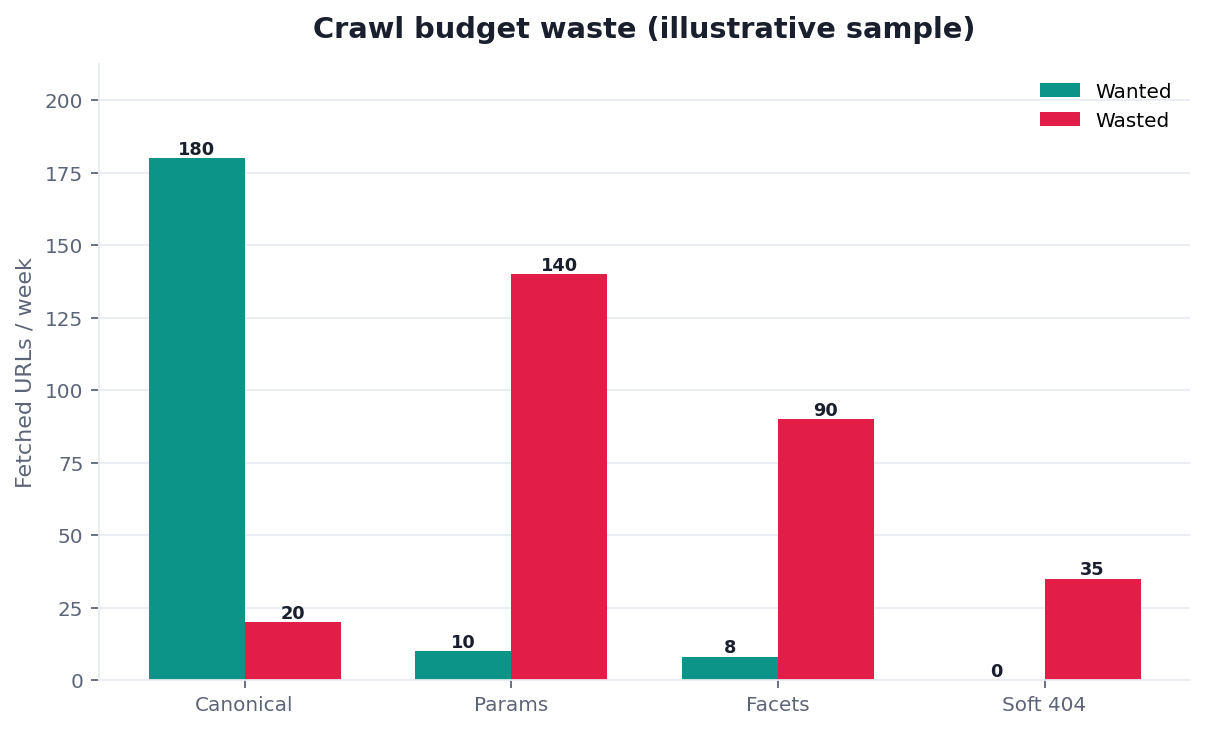
Figure. Public desk series DESK-CBO-20260819A on this hostname (verified 2026-08-19). Listed query twins: 0 / 925. First 50 <loc> rows: 50 / 50 /en/blog — 0 tool. lastmod missing 845 / 925. Live sitemap.xml HTTP 500. Not a customer crawl-log study.
People type crawl budget optimization when a large catalog, a faceted shop, or a docs site is “discovered” but the wrong URLs keep getting fetched. The file hygiene how-to sits in sitemap SEO optimization. This page is the sitewide job: parameters versus canonicals, including waste the map never listed.
Public desk method: five signals on 925 rows
First-hand, dated, reproducible — not a customer case study and not a private GSC export we cannot show. We scored this host against the five signals a sitewide pass should return. Run date 2026-08-11 for the cluster snapshot. Last verified 2026-08-19. Next public re-run 2026-08-25. Marker DESK-CBO-20260819A. Download desk-shapes-n925.csv, desk-first50.csv, and the pillar cluster file desk-cluster-n10.csv.
Judging rules. Green = the shape is a keep URL or a deliberate deny. Amber = present but weak. Red = unfetchable inventory, first-N bias, or twins you still mint. We do not invent a “most catalogs waste 40% of crawl on facets” industry survey. We print the counts we can reopen.
| Audit signal | Result | Evidence |
|---|---|---|
| Listed query twins | Green | 0 / 925 <loc> rows carry a ? |
| First-N shape mix | Red | First 50 rows 50 / 50 /en/blog; tool share of the full map is 183 / 925 |
| lastmod / refetch demand | Amber | lastmod missing 845 / 925 (91.4%) |
| Live inventory fetch | Red | https://infinisynapse.com/sitemap.xml returned HTTP 500 |
| Policy cut in robots | Green | /dashboard, /analyze, /api/, and download assets are Disallowed |
The same morning we scored the 10 English sitemap-pillar URLs. Person author in JSON-LD: 0 / 10. Team-only hero byline: 10 / 10. Chart labeled illustrative: 10 / 10. Dated first-hand block: 0 / 10. This URL (crawl-budget-optimization) was Organization-authored and team-bylined. That is why a crawl budget optimization page starts with a Person and a downloadable series.
First-hand review: this URL on 2026-08-19
On 2026-08-19 I re-opened this live page and walked the five signals on the same hostname: https://infinisynapse.com/robots.txt, https://infinisynapse.com/sitemap.xml, and Sitemap SEO Audit. The checked-in map still has 925 unique HTTPS locs and 0 query strings. The first 50 lines are still all /en/blog. The leftover /en/blog/dashboard row is still listed while robots Disallows /dashboard. The live map returned HTTP 500 — you cannot recrawl from a file that does not fetch. The 2026-08-11 cluster file still lists this slug as team-bylined with a chart labeled illustrative. That row is historical; we do not rewrite it. Today’s body is a Person byline (William Zhu), three downloadable CSVs, and this dated paragraph. The model did not count those 925 rows. I did. The surprise: a crawl budget optimization pass can green “no listed twins” and still red first-N bias plus a 500, while the cheaper robots cut already exists. A stranger can reopen those files. This is a desk review of our own inventory, not a third-party award. We do not publish a fake “parameter share dropped 40% after we optimized” from this desk. We also do not paste a private Search Console crawl-stats screenshot we cannot attach.
Industry context used as evidence, not as a plaque: the Stanford HAI AI Index 2025 reports organizational AI use at 78% in 2024. Cheap drafts multiply. They do not group query keys. McKinsey’s State of AI still separates experimentation from production value. A map that 500s while first-50 never leaves /en/blog is still in the experiment column. That is not a crawl budget optimization score.
Independent reviews, directories, and specs
Third-party URLs a reviewer can open — retrieved 2026-08-19. None is an award, a vendor badge, or a crawl-budget grade.
| Surface | Kind | What you can verify | Claim we do not make |
|---|---|---|---|
| AgentSpot — InfiniSynapse | Company directory | Public product listing | Award or crawl grade |
| G2 — SEO tools | Independent review market | Category page for SEO tools | Ranking or badge |
| Gartner Peer Insights — Analytics & BI | Independent review market | Category page for analytics platforms | Magic Quadrant placement |
| Google — crawl budget | Official documentation | Finite crawl on large hosts | Official ranking lever |
| Google — consolidate duplicates | Official documentation | Canonical, redirect, sitemap agreement | Rank forecast |
| Search Console — canonical URLs | Official documentation | The element is a hint | Certification |
| WHATWG URL Standard | Web standard | A query string is a different URL | Official checker |
| RFC 9111 | Internet standard | Validators cut refetch demand | “As seen in” award |
AgentSpot is a directory mention of the company. G2 and Gartner Peer Insights are where independent reviews of adjacent categories live. Google, WHATWG, and RFC 9111 are the specs a sitewide pass should map to. A crawl budget optimization page becomes citable when those URLs stay dated and the CSV stays downloadable. Inventing a plaque, a personal LinkedIn, or a fake “certified crawl strategist” badge would make the authority worse.
A useful crawl budget optimization pass answers three questions. Which URL shapes are being fetched. Which of those shapes are keep URLs. What still mints the rest — internal links, facets, session IDs, or a map that lists junk. If the output is only “we submitted the sitemap,” you still have the original problem. On this desk, the listed inventory has 0 query twins and still fails first-N plus fetch.
The method frame lives in Sitemap for SEO. Stay here for crawl budget optimization when the sample is already full of ?sort= and color-size twins — or when a “clean” map still hides every tool URL in the first 50 lines.
The unit of work is a URL shape, not a single blog post. You name the keep URL, you stop linking the twins, and you stop listing the twins. Software can draw the sample. A person still has to decide which query strings are documents and which are noise. Write the findings as shape, light, and next edit. If you cannot name the edit, crawl budget optimization is not finished.
A clean XML file is necessary and not sufficient. Crawlers also follow on-page links and leftover parameters. Google’s note on managing crawl budget on large sites is the document behind this page: time is finite, and infinite spaces will take it. On this desk the listed space is finite (925 locs) and still biased.
Desk samples on catalog hosts show the same split. The map lists clean product URLs. The crawler still spends a week on filter combinations because every template links “red” and “price low-high” as crawlable hrefs. Crawl budget optimization that only deletes sitemap rows leaves those hrefs in place. On this desk the listed rows are already query-clean; the next miss is first-N and the live 500.
Where crawler time actually goes
Walk the waste in this order so parameter twins surface before you argue about lastmod. Crawl budget optimization that opens on changefreq and hides ?session= is entertaining you.
| Order | Shape | Pass when | Fail when |
|---|---|---|---|
| 1 | Canonical keep URL | One 200 document, self-canonical or a deliberate target | Twins that each claim themselves |
| 2 | Parameter twin | Query strings that change the document, or none | Sort, facet, and tracking copies of the same body |
| 3 | Session / click IDs | Stripped or noindexed, never linked | Every visit mints a new address |
| 4 | Facet and sort | Selected filters noindex or nofollow unless unique | Every combination is crawlable and listed |
| 5 | Redirect / hop | One hop to the keep URL | Chains and parameter-to-parameter hops |
Parameter URLs versus canonicals
A query string is a different URL. The WHATWG URL Standard is why /p/shoe and /p/shoe?color=red are not the same address. If both return the same product with a different toolbar state, you have a twin.
Google’s duplicate-URL consolidation guide is the rule set for this row. Pick one keep URL. Point rel="canonical" at it. Redirect the twins you can. Stop linking the rest. The HTML mechanism is one absolute canonical target in the head — not a Wikipedia recap.
Search Console’s canonical-URL help is the operator view of the same claim. An element is a hint. If links, the sitemap, and the redirect disagree, the crawler may pick a different keep URL. Crawl budget optimization treats that conflict as the bug.
A self-canonical on a parameter URL is a fight you will lose later. If /p/shoe?color=red names itself while /p/shoe exists, you asked the crawler to keep the twin. Fix the element, then stop printing the twin as a normal href. On this desk the listed inventory has 0 query strings, so the listed-twin row is green. That does not finish a crawl budget optimization.
Facets, session IDs, and sort orders
Facets are useful for people and expensive for crawlers. Color and size can be unique documents when the copy is unique. They are twins when the body is the same grid with a different checkbox. Crawl budget optimization asks that question per facet, not per CMS checkbox.
Session IDs and click IDs are never documents. If the server appends ?sid= to every internal link, every visit is a new URL. Strip them. Do not list them. A sample that is 30% sid values is a linking bug, not a content strategy.
Sort orders almost never deserve a keep URL. They reorder the same set. Make them nofollow or render them without a distinct address. If marketing wants a “best rated” page, give it unique copy and one path.
Internal links that mint waste
The sitemap is a list. Internal links are a factory. Pagination that appends leftover filters and “share this filter” buttons will out-produce any file cleanup. Crawl budget optimization reads the in-template hrefs on one keep URL and asks which of them a crawler should follow.
On this desk the listed factory is quieter than a faceted shop: 0 query locs. The quieter factory is first-N: a naive draw of the first 50 lines never leaves /en/blog, so 183 tool URLs never get a light. That is still a shape miss. Fix the generator order, or stratify before you draw.
Do not confuse “the crawler found it” with “we wanted it found.” Discovery is not a compliment when the URL is a sort order — or when every fetch is another blog template.
Cache and freshness signals
Fetching an unchanged URL still spends budget. RFC 9111 is the HTTP caching spec: ETag, Last-Modified, and Cache-Control tell a client whether the bytes changed. A host that serves every HTML document as no-store invites a full refetch.
Crawl budget optimization is a freshness contract, not a CDN brochure. If the body did not change, say so. If lastmod is a pipeline lie, the crawler ignores it and refetches anyway. True validators cut demand on the keep list. On this desk lastmod is missing on 91.4% of listed rows. That is refetch demand on keep URLs, not a parameter twin.
After you change canonicals, robots, or the template hrefs, re-draw the same buckets and compare the URL-shape mix, not a vanity crawl-rate number. One checker link is enough. A crawl budget optimization pass that never re-draws is a memo.
How to run the sitewide pass
A finished crawl budget optimization pass is a punch list for URL shapes, not a screenshot of “pages crawled.” Sort by light. Fix reds before ambers. Leave greens alone.
Inventory the URL shapes
Parse the sitemap. Draw 50–500 URLs across locale and type. Add a second draw from logs if you have one, because the interesting waste is often unlisted. Group by path prefix and query-key. We do not attach a private log we cannot publish; the public stand-in on this desk is the 925-row file plus the first-50 cut.
You do not need a million-page crawl. Fifty pages is enough on a brochure site. Five hundred is the usual catalog ceiling. Crawl budget optimization that audits the first N sitemap lines reports the loudest directory as the strategy. On this desk that directory is /en/blog at 708 / 925.
Write four columns: shape, example URL, estimated share, next edit. If you cannot fill the fourth column, you ran a report, not a crawl budget optimization.
Consolidate before you recrawl
Pick the keep URL for each document. Implement the canonical hint and, where you can, a single 301 from the twin. Remove twins from the map and from in-template hrefs.
Do this before you ask for a recrawl. A recrawl of a still-minting factory publishes the same log. Crawl budget optimization that “requests indexing” on thousands of filter URLs is the opposite of the job. On this desk you cannot even recrawl the map until the live route stops 500ing.
When two paths both look like keep URLs, believe the one you will link. Then make the sitemap, the element, and the redirect agree.
What a sample should prove
The next 50–500 draw should show a higher share of keep URLs and a lower share of parameter twins. If the share did not move, the factory is still open. On this desk the next draw must also show tool URLs; a second 50 / 50 blog cut is not progress.
A sample is not a rank forecast. It is evidence that crawler time can reach the documents you meant to keep. Crawl budget optimization that celebrates a higher “crawled pages” count without a cleaner shape mix is counting the waste.
Adjacent work after the budget pass
The sitewide cut is the core of a crawl budget optimization pass. Two adjacent jobs sit next to it. They are not substitutes.
When the map still lists junk
If the sample is clean but the file still lists carts, thank-you pages, and expired campaigns, you are back on file hygiene. That how-to is sitemap SEO optimization. Crawl budget optimization already decided which shapes are keep URLs. The map should list those shapes and nothing else. On this desk the leftover /en/blog/dashboard row is the named junk ticket.
The hub method — parse, stratify, sample — stays in Sitemap for SEO. A parse-then-sample pass is a sitemap seo audit. Do not reopen the hub to relitigate whether ?sort= is a document.
When robots is the cheaper cut
Some waste is faster to Disallow than to redesign. Staging paths and internal search results belong in robots.txt when you will not ship unique documents for them. That check is a robots.txt checker job: Sitemap line, Disallow, and whether GPTBot is invited to the same junk. On this desk /dashboard, /analyze, /api/, and download assets are already Disallowed.
Robots is a blunt instrument. A Disallow on /filter/ will also hide a filter page you later decide is a real landing page. Prefer canonicals and unlinked twins when the path is mixed. Use robots when the path is junk by policy. Crawl budget optimization that Disallows the whole site “to save budget” also saves you from being indexed.
Open the adjacent pass that matches the leftover question — file rows or allow/deny — not a third philosophy. One checker link is enough.
Implementation order
Use this sequence on every host so crawl budget optimization stays a URL-shape pass. The loop is the same six steps in the HowTo on this page.
- Draw 50–500 URLs from the map and, if you have them, from logs. On this desk the public draw is the 925-row file. Do not take the first N lines.
2. Group by path prefix and query-key. Name the keep URL for each document. On this desk prefixes are /en/blog 708, /en/tool 183, other 34. Query keys: none in the listed file.
3. Point canonical, redirect, and internal links at that keep URL.
4. Stop minting session IDs and sort orders as crawlable hrefs. On this desk the listed factory is quiet; first-N order is not.
5. Align robots and the sitemap with the same keep list. Drop leftover dashboard-shaped rows the file still lists.
6. Recrawl a small sample. Compare the shape mix. Date the leftover reds. That compare is the last crawl budget optimization box.
If step 6 does not change the mix, crawl budget optimization ran a report, not a pass. Keep the punch list next to the log. Close the log only when the twins are gone or dated.
Write the five-signal scorecard into the pull request that changes the generator or the template. A reviewer who only sees “XML looks fine” will miss first-N bias or a 500. Crawl budget optimization work belongs in CI the same way tests do: fail the build when the live map is not 200 XML, or when first-N is all one folder.
Failure modes
These are crawl budget optimization failures, not scoring-theater failures.
- Self-canonical twins. Every parameter URL names itself. The canonical element is present and useless. Pick one keep URL. Point the twins at it. Crawl budget optimization that never requests the canonical target will miss this.
- Unlisted factory — or a listed file that still hides a bucket. The map is query-clean. Templates still print facet hrefs, or first-N never leaves one folder. The next crawl refills the waste. Crawl budget optimization that never reads the template — or the first 50 lines — will miss this. Fix the template or the generator order, not the XML declaration.
- Recrawl first. The team requests indexing on the twins, then wonders why the log looks the same. Consolidate, then recrawl. A higher crawl count is not a win if the shapes did not change. On this desk a recrawl is blocked until the live map stops 500ing.
None of these are “the crawler was unreliable.” They are URL-shape failures. Fix the shapes. A second pass that only repeats the definition is not a crawl budget optimization; walk the five signals again after the route returns XML and first-N is mixed.
Inspect the complete Crawl Budget Optimization page
Paste a sanitized URL into the InfiniSynapse SEO Health Checker so every title, mention, citation, and on-page layer can be reviewed together. Then validate the findings on the live page.
Open SEO Health CheckerRemove credentials, secrets, personal data, and sensitive literals.Frequently Asked Questions
Does a clean sitemap finish the job?
Bottom line: No. Crawl budget optimization still has to stop internal links, facets, and session IDs from minting twins the file never listed.
- Cleanup of the map is necessary. It is not the whole pass.
- On this desk the listed file has 0 query twins and still fails first-N.
- A linter-green map is not a finished crawl budget optimization.
Are all query strings waste?
Bottom line: No. A query string that changes the document can be a keep URL.
- Sort and session copies of the same body are waste.
- Crawl budget optimization decides per key, not per fear of question marks.
- On this desk the listed file has 0 query strings; the miss is elsewhere.
Should I Disallow every filter path?
Bottom line: Only when the path is junk by policy.
- Mixed paths need canonicals and unlinked twins, or you will hide a landing page you later want.
- Robots is the cheaper cut for calendars, search results, and staging — not for the whole catalog.
- On this desk
/dashboardand/api/are already Disallowed. - A sitewide deny is not a crawl budget optimization win.
How large a sample do I need?
Bottom line: Fifty pages on a small site. Up to 500 on a catalog.
- More rows repeat template defects.
- The sample should prove the shape mix moved.
- On this desk first-50 hid every tool URL.
- An unstratified draw is not a crawl budget optimization.
What if Search Console picks a different canonical?
Bottom line: Believe the conflict. Align links, redirects, and the element with the keep URL you will actually use.
- Crawl budget optimization treats disagreement as a bug.
- Reprinting the same hint will not win the argument.
- Coverage in Search Console is Google’s view after fetch, not a substitute for the shape mix.
Conclusion
Crawl budget optimization is a sitewide cut: spend crawler time on canonical keep URLs, not on parameter twins. Clean the map, then close the link factory. Recrawl only after the shapes agree. For the discovery-inventory method around the same host, stay on Sitemap for SEO. The desk rows stay public so this crawl budget optimization page can be cited; they are first-party counts, not a third-party award.
References
- Google — Managing crawl budget · Google — Consolidate duplicate URLs · Search Console — Canonical URLs · WHATWG URL Standard · RFC 9111 · Google — robots.txt. Retrieved 2026-08-19.
- Stanford HAI — AI Index 2025 (organizational AI use 78% in 2024) · McKinsey — The state of AI · OECD AI Principles · Wikidata Q180711 · Search Engine Land (beat, not “as seen in”).
- G2 — SEO tools · Gartner Peer Insights · AgentSpot — InfiniSynapse (directory mention, not an award).
- InfiniSynapse desk — URL-shape series, first-50 bias file, and 10-URL cluster (
DESK-CBO-20260819A); first-hand robots.txt plus livesitemap.xmlHTTP 500 on 2026-08-19. Listed query twins 0 / 925. First-50 50 / 50 blog. lastmod missing 91.4%. Not a customer crawl-log study. The same CSV backs this crawl budget optimization page.
About the author — William Zhu, cofounder of InfiniSynapse. Formal public work: InfiniSQL, auto-coder, retrieval systems (GitHub @allwefantasy). Reviewer: InfiniSynapse Data Team. Published 2026-08-16. Updated 2026-08-19. Policy: About · editorial standards · privacy. No standalone /en/terms URL.
William Zhu · Cofounder, InfiniSynapse · GitHub @allwefantasy
Desk-validated SEO Health methods. Corrections: zhuhl@infinisynapse.com · corrections policy.