
What Is a Federated Query?什么是联邦查询?
A federated query is one logical query whose plan reads from two or more separately managed data sources and combines their selected results at query time. A federated query engine resolves source objects, translates types and operations through connectors, pushes safe work to each source, executes remaining joins or aggregations, and returns one result with execution and source evidence. An inner remote join is a SQL Server linked-server hint, separate from this architecture.
联邦查询是一条逻辑查询,其执行计划读取两个或更多分别管理的数据源,并在查询时组合选定结果。联邦查询引擎解析来源对象,通过连接器转换类型与操作,把安全工作下推到各来源,执行剩余连接或聚合,再返回带执行和来源证据的统一结果。inner remote join 是 SQL Server 链接服务器上的提示,和这种架构是两回事。
For the full topic map and the neighboring methods that support this workflow, continue with the federated queries and data virtualization guide.
如需查看完整主题结构以及支撑本流程的相邻方法,请继续阅读联邦查询与数据虚拟化指南。
The term describes a query behavior, not a universal product contract. One engine may join a warehouse table with an operational database; another may query object storage and a remote catalog; a cloud service may expose only specific external sources through managed connectors. Connector, source, edition, region, identity, network, type, operator, quota, and transaction support must all be verified.
该术语描述查询行为,并不代表统一产品契约。一个引擎可能连接数据仓库表与业务数据库;另一个可能查询对象存储和远程目录;某云服务则只能通过托管连接器访问特定外部来源。连接器、来源、版本、区域、身份、网络、类型、操作符、配额和事务支持都必须逐项验证。
Trino provides one concrete model: catalogs configure connectors, a coordinator parses and plans, workers fetch through connectors, and stages, tasks, splits, operators, and exchanges execute the distributed plan. Athena, BigQuery, Redshift, and PostgreSQL foreign-data wrappers expose different boundaries. Their official documentation is evidence for implementations, not proof that every federated query engine behaves alike.
Trino提供一种具体模型:目录配置连接器,协调器解析和规划,工作节点通过连接器读取数据,阶段、任务、分片、操作符和交换共同执行分布式计划。Athena、BigQuery、Redshift和PostgreSQL外部数据包装器则具有不同边界。它们的官方文档是实现证据,并不能证明所有联邦查询引擎行为相同。
Federated Query Example, With and Without Pushdown联邦查询示例:有下推与无下推
Suppose recent orders remain in an operational PostgreSQL database while customer segments live in a warehouse. An analyst wants revenue by segment for the last seven days. A federated query can resolve both tables, push the date filter and order aggregation to PostgreSQL, fetch the small customer lookup from the warehouse, join the bounded results, and return one table.
假设近期订单保存在业务 PostgreSQL 数据库中,而客户分群位于数据仓库。分析师需要最近七天按分群统计的收入。联邦查询可以解析两张表,把日期筛选和订单聚合下推到 PostgreSQL,从仓库读取较小的客户查找表,连接受限结果并返回一张表。
SELECT c.segment, SUM(o.revenue) AS revenue
FROM postgres.sales.orders AS o
JOIN warehouse.crm.customers AS c ON o.customer_id = c.customer_id
WHERE o.order_date >= CURRENT_DATE - INTERVAL '7' DAY
GROUP BY c.segment;| Stage阶段 | Best execution location最佳执行位置 | Evidence to inspect检查证据 |
|---|---|---|
| Filter recent orders筛选近期订单 | PostgreSQL sourcePostgreSQL 来源 | Remote SQL, rows scanned, date boundary远程 SQL、扫描行数、日期边界 |
| Aggregate revenue聚合收入 | PostgreSQL when connector support is safe连接器安全支持时在 PostgreSQL | Remote aggregate and returned row count远程聚合与返回行数 |
| Join customer segments连接客户分群 | Engine or source chosen from cardinality and cost依据基数与成本选择引擎或来源 | Join order, bytes moved, duplicate checks连接顺序、移动字节、重复检查 |
This is an illustrative plan, not a promise that every connector pushes the same operations. Run EXPLAIN, inspect generated remote requests, and reconcile the result with source counts before treating the plan as production-safe.
这是示意计划,并不承诺每个连接器都会下推相同操作。把计划视为生产安全之前,应运行 EXPLAIN、检查生成的远程请求,并用来源计数核对结果。
Remote SQL before pushdown下推前的远程 SQL
BigQuery's introduction to federated queries shows the failure mode. A filter written outside EXTERNAL_QUERY can leave the remote database with a full scan:
BigQuery 联邦查询介绍展示了这种失败模式。写在 EXTERNAL_QUERY 之外的过滤,可能让远程数据库执行全表扫描:
SELECT *
FROM operations_table
The engine then filters after the rows have already moved. That pattern is still a federated query, and it is often the slow one.
引擎会在行已经传回之后再过滤。这仍然是联邦查询,而且常常是慢的那种。
Remote SQL after pushdown下推后的远程 SQL
When column pruning and filter pushdown apply, the source keeps only the needed columns and the predicate:
当列裁剪和过滤下推生效时,来源只保留需要的列和谓词:
SELECT customer_id, revenue
FROM sales.orders
WHERE order_date >= CURRENT_DATE - INTERVAL '7' DAY
BigQuery documents that this EXTERNAL_QUERY form pushes column pruning and filters, not joins, limits, ordering, or aggregation. Trino's pushdown reference lists predicate, projection, aggregation, join, limit, and Top-N where a connector implements them. Treat the order example as safe only after EXPLAIN shows where the date filter, the revenue aggregate, and the segment join actually run.
BigQuery 写明这种 EXTERNAL_QUERY 形式会下推列裁剪和过滤,不会下推连接、限制、排序或聚合。Trino 下推文档列出连接器实现后的谓词、投影、聚合、连接、限制和 Top-N。只有 EXPLAIN 显示日期过滤、收入聚合和分群连接的实际位置之后,上面的订单示例才算安全。
How Major Engines Run a Federated Query主流引擎如何执行联邦查询
These rows are product boundaries from current vendor documentation, not a universal feature list. Confirm edition, region, and connector before you design around one cell.
下表是各厂商当前文档里的产品边界,不是通用功能清单。围绕某一格做设计之前,先确认版本、区域和连接器。
| Engine引擎 | How work reaches the source工作如何到达来源 | Sources named in the docs文档点名的来源 | Pushdown the docs state文档写明的下推 |
|---|---|---|---|
| BigQuery | EXTERNAL_QUERY over a connection, or an external table通过连接使用 EXTERNAL_QUERY,或使用外部表 | AlloyDB, Spanner, Cloud SQL, SAP Datasphere (Preview)AlloyDB、Spanner、Cloud SQL、SAP Datasphere(预览) | Column pruning and filters for EXTERNAL_QUERY; joins and aggregates are not pushed in that formEXTERNAL_QUERY 下推列裁剪和过滤;这种形式不下推连接和聚合 |
| Amazon Redshift | Leader node reads metadata; compute nodes send subqueries领导节点读取元数据,计算节点发送子查询 | RDS and Aurora for PostgreSQL and MySQL, plus Redshift and S3PostgreSQL 与 MySQL 的 RDS 和 Aurora,以及 Redshift 和 S3 | Predicate pushdown; remote statements land in SVL_FEDERATED_QUERY谓词下推;远程语句记入 SVL_FEDERATED_QUERY |
| Databricks | Foreign catalog on a Unity Catalog connectionUnity Catalog 连接上的外部目录 | MySQL, PostgreSQL, Snowflake, SQL Server, Redshift, BigQuery, and othersMySQL、PostgreSQL、Snowflake、SQL Server、Redshift、BigQuery 等 | Inspect the foreign scan in Query Profile or EXPLAIN FORMATTED在 Query Profile 或 EXPLAIN FORMATTED 中查看外部扫描 |
| Trino | Catalog and connector目录与连接器 | Whatever that connector supports取决于该连接器支持的来源 | Predicate, projection, aggregation, join, limit, and Top-N when implemented连接器实现后的谓词、投影、聚合、连接、限制和 Top-N |
Amazon Redshift's federated query overview uses the live operational read to avoid a separate ETL pipeline for that slice. Databricks query federation is aimed at ad hoc reporting, proofs of concept, and the exploratory phase of a pipeline. The same page points high-volume, low-latency work at managed ingestion instead.
Amazon Redshift 联邦查询概览用实时业务库读取来避免为这一小段再做一条 ETL。Databricks 查询联邦面向临时报表、概念验证和管道的探索阶段。同一页把高数据量、低延迟的工作指向托管摄入。
Federated Query Architecture from Client to Source从客户端到来源的联邦查询架构
Supplies query text, identity, role, purpose, locale, time zone, resource class, deadline, and result expectations.
提供查询文本、身份、角色、用途、语言环境、时区、资源类别、截止时间和结果预期。
Maps logical names to endpoints, credentials, owners, schemas, types, functions, statistics, limits, health, and versioned capabilities.
把逻辑名称映射到端点、凭据、所有者、Schema、类型、函数、统计、限制、健康和带版本能力。
Resolves objects and fields, checks syntax and types, applies policies, and rejects operations that cannot preserve required semantics or authorization.
解析对象和字段,检查语法与类型,应用策略,并拒绝无法保持所需语义或授权的操作。
Chooses join order, execution location, pushdown, partitioning, exchange, memory, spill, concurrency, and fallback using available evidence.
依据可用证据选择连接顺序、执行位置、下推、分区、交换、内存、溢写、并发和回退。
Execute connector-specific requests, stream bounded data, normalize returned types, propagate cancellation, and expose source errors.
执行连接器专属请求,流式传输受限数据,规范返回类型,传播取消,并暴露来源错误。
Performs remaining joins or aggregates and returns provenance, observation times, warnings, coverage, plan identity, rows, bytes, timing, and audit correlation.
执行剩余连接或聚合,并返回来源证明、观察时间、警告、覆盖、计划身份、行数、字节、时序和审计关联。
These are responsibilities, not mandatory products. A cloud service may combine them; a self-managed engine may separate control plane, coordinator, workers, catalogs, and secret management; an embedded foreign-data mechanism may place planning inside an existing database. Evaluate where each responsibility lives and who operates it. The catalogs, identity chain, and transaction rules that remain after the query belong to a federated database system.
这些是职责,并非必须对应独立产品。云服务可能把它们组合起来;自管引擎可能分离控制面、协调器、工作节点、目录和密钥管理;嵌入式外部数据机制则可能把规划放在现有数据库内部。应评估每项职责位于何处以及由谁运营。查询结束后仍然保留的目录、身份链和事务规则,属于一套联邦数据库系统。
How a Federated Query Works Step by Step联邦查询如何逐步工作
- Bind identity and intent.绑定身份与意图。 Authenticate the caller and attach purpose, role, resource class, deadline, time zone, result policy, and session settings.验证调用者,并附加用途、角色、资源类别、截止时间、时区、结果策略和会话设置。
- Parse and resolve.解析与定位。 Convert query text into a logical plan and resolve every catalog, schema, table, column, type, function, and policy.把查询文本转换为逻辑计划,并解析每个目录、Schema、表、列、类型、函数和策略。
- Analyze capabilities.分析能力。 Compare required operations with connector and source support; reject or compensate for differences explicitly.比较所需操作与连接器和来源支持情况;显式拒绝差异或执行补偿。
- Optimize placement.优化执行位置。 Use statistics, selectivity, locality, transfer cost, source load, memory, concurrency, and deadlines to choose pushdown and join order.使用统计、选择性、位置、传输成本、来源负载、内存、并发和截止时间选择下推及连接顺序。
- Generate source subplans.生成来源子计划。 Translate approved fragments into source-native requests with bounded columns, predicates, aggregates, limits, parameters, and identifiers.把获批片段转换为来源原生请求,并限制列、谓词、聚合、行数、参数和标识符。
- Execute and exchange.执行与交换。 Run remote and local stages, stream or stage results, enforce budgets, propagate cancellation, and avoid unsafe unbounded retries.运行远端和本地阶段,流式或暂存结果,执行预算,传播取消,并避免不安全的无界重试。
- Join, aggregate, and normalize.连接、聚合与规范化。 Apply remaining operations while preserving types, nulls, precision, collation, time, provenance, and declared incomplete-result policy.执行剩余操作,同时保留类型、空值、精度、排序规则、时间、来源证明和已声明的不完整结果策略。
- Return result and evidence.返回结果与证据。 Expose plan identity, pushed and local operations, source states, rows, bytes, timings, warnings, observation times, policy decisions, and audit correlation.暴露计划身份、下推与本地操作、来源状态、行数、字节、时序、警告、观察时间、策略决定和审计关联。
When a Federated Query Loses to Ingestion or CDC联邦查询何时不如摄入或 CDC
These terms overlap, but they answer different architecture questions. A federated query is the execution act. Data virtualization is the access layer around it. ETL materializes transformed data. CDC continuously copies changes. The data federation guide covers the architecture. The right choice depends on freshness, repeated workload, source impact, history, governance, and failure tolerance.
这些术语相互重叠,但回答的是不同架构问题。联邦查询是一种执行行为;数据虚拟化是更广泛的访问与抽象层;ETL 会物化转换后的数据;CDC 持续复制变更。正确选择取决于新鲜度、重复负载、来源影响、历史、治理和故障容忍度。
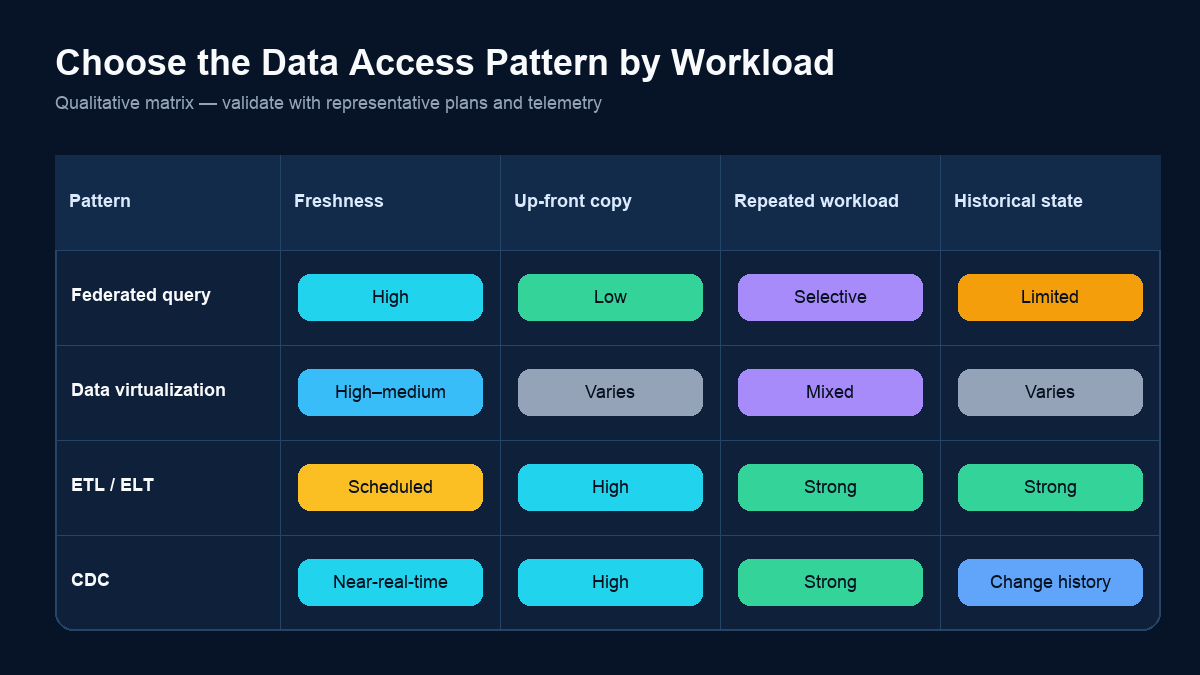
| Pattern模式 | Primary job主要任务 | Data movement数据移动 | Best fit适用场景 |
|---|---|---|---|
| Federated query联邦查询 | Execute one query across sources跨来源执行一条查询 | Selected and intermediate results move at query time查询时移动选定结果与中间结果 | Selective, current, occasional cross-source analysis选择性、当前、偶发的跨源分析 |
| Data virtualization数据虚拟化 | Expose governed logical views across systems跨系统公开受治理逻辑视图 | Depends on federation, cache, or materialization取决于联邦、缓存或物化 | Stable consumer contracts over changing sources在变化来源之上提供稳定使用者契约 |
| ETL or ELTETL 或 ELT | Build reusable modeled datasets构建可复用的模型化数据集 | Copies data on a schedule or trigger按计划或触发器复制数据 | Repeated analytics, history, predictable performance重复分析、历史与可预测性能 |
| CDCCDC | Replicate source changes continuously持续复制来源变更 | Moves inserts, updates, and deletes移动插入、更新与删除 | Low-latency replicas and incremental pipelines低延迟副本与增量管道 |
For the broader architecture boundary, use the federated queries and data virtualization guide. This page stays focused on what a federated query means and how one query is planned and executed.
架构边界见数据联邦指南。本页只讲联邦查询本身:一条查询如何被规划并执行。相邻方法见联邦查询与数据虚拟化指南。
Verify Federated Query Pushdown with the Actual Plan使用实际计划验证联邦查询下推
Pushdown sends selected work to a source so less data crosses the network and less coordinator work remains. Common forms include predicate, projection, nested-field dereference, aggregation, join, limit, and Top-N pushdown. It is valuable only when the translated operation is semantically safe and the source can execute it within its protection envelope.
下推把选定工作发送到来源,从而减少跨网络数据量和协调器剩余工作。常见形式包括谓词、投影、嵌套字段解引用、聚合、连接、限制和Top-N下推。只有当转换后的操作在语义上安全,且来源能在保护范围内执行时,下推才有价值。
Capture normalized and physical plans. Identify remote scans, filters, projections, aggregates, joins, limits, exchanges, repartitioning, local operators, estimates, and selected connectors.
捕获规范化计划与物理计划。识别远程扫描、筛选、投影、聚合、连接、限制、交换、重分区、本地操作、估计和选定连接器。
Reconcile the plan with source logs and telemetry: submitted text or parameters, rows scanned and returned, bytes transferred, partitions read, duration, connections, memory, spill, cancellation, and errors.
将计划与来源日志及遥测核对:提交文本或参数、扫描与返回行数、传输字节、读取分区、时长、连接、内存、溢写、取消和错误。
Do not assume a join is pushed because both tables use the same connector type. Some engines require the same catalog, compatible types, translatable predicates, trusted statistics, and connector-specific support. A pushed join can also expand rows; placement must be validated from actual cardinality and transfer evidence.
不能因为两张表使用同一种连接器就假设连接已下推。某些引擎要求相同目录、兼容类型、可转换谓词、可信统计和连接器专属支持。下推连接也可能扩大行数;执行位置必须依据实际基数和传输证据验证。
Failure rule: if a mandatory filter, authorization predicate, time boundary, precision rule, or row limit cannot be preserved, reject the query or use an approved alternative. Silently performing a different operation is not optimization.
失败规则:如果必需筛选、授权谓词、时间边界、精度规则或行数限制无法保持,应拒绝查询或使用获批替代方案。静默执行不同操作不是优化。
Control Cross-Source Joins and Data Movement控制跨源连接与数据移动
A cross-source join is where many promising prototypes fail. The planner must decide which side to filter or aggregate remotely, which side to move, whether to broadcast a small relation, whether to repartition streams, and whether an approved temporary stage or cache is allowed. A poor decision can scan operational tables, saturate links, exhaust coordinator memory, spill sensitive data, or miss a deadline.
跨源连接是许多看似成功原型失败的地方。规划器必须决定哪一侧在远端筛选或聚合、移动哪一侧、是否广播小关系、是否重分区数据流,以及是否允许获批临时暂存或缓存。错误决定可能扫描业务表、占满链路、耗尽协调器内存、溢写敏感数据或错过截止时间。
| Factor因素 | Required evidence所需证据 | Risk when missing缺失风险 |
|---|---|---|
| Cardinality and selectivity基数与选择性 | Fresh row counts, value distributions, filter selectivity, skew, and null rates最新行数、值分布、筛选选择性、倾斜和空值率 | Wrong build side, network explosion, or memory exhaustion错误构建侧、网络膨胀或内存耗尽 |
| Key semantics键语义 | Type, normalization, uniqueness, collation, padding, case, and duplicate rules类型、规范化、唯一性、排序、填充、大小写和重复规则 | False matches, missed matches, or duplicate multiplication错误匹配、漏匹配或重复倍增 |
| Location and transfer位置与传输 | Region, route, bandwidth, egress, encryption, data class, and staging permission区域、路由、带宽、出口、加密、数据分类和暂存许可 | Unexpected cost, policy violation, or deadline miss意外成本、策略违规或错过截止时间 |
| Source envelope来源范围 | Concurrency, scan, CPU, I/O, timeout, lock, replica, and maintenance limits并发、扫描、CPU、I/O、超时、锁、只读副本和维护限制 | Production-source degradation or cascading retries生产来源降级或级联重试 |
When a recurring join repeatedly moves the same large data, materializing an approved model may be safer and cheaper. Federation is not a moral preference for “no copies”; it is one execution choice whose movement, retention, freshness, security, cost, and reliability must be compared with alternatives.
当重复连接持续移动同一批大数据时,物化获批模型可能更安全、更经济。联邦并不是“不复制”的道德偏好;它只是一个执行选择,必须将其移动、保留、新鲜度、安全、成本和可靠性与替代方案比较。
When to Use a Federated Query—and When Not To何时使用联邦查询,以及何时不应使用
- The question needs current data from separately governed sources.
- Filters and aggregation can sharply reduce each source result.
- The workload is selective or occasional rather than a repeated full scan.
- Copying complete datasets would add unjustified delay or governance scope.
- 问题需要来自分别治理来源的当前数据。
- 筛选与聚合能显著缩小每个来源的结果。
- 负载具有选择性或偶发性,而不是重复全表扫描。
- 复制完整数据集会增加不必要的延迟或治理范围。
- The same large join runs repeatedly or needs predictable latency.
- Historical snapshots, audit replay, or slowly changing dimensions are required.
- A source cannot tolerate analytical scans or reliable pushdown is unavailable.
- Cross-region transfer, failure coupling, or source quotas dominate the design.
- 同一大型连接重复运行或需要可预测延迟。
- 需要历史快照、审计重放或缓慢变化维度。
- 来源无法承受分析扫描,或缺少可靠下推。
- 跨区域传输、故障耦合或来源配额主导设计。
A practical threshold is evidence, not ideology: compare rows scanned, bytes transferred, source CPU, end-to-end latency, failure rate, freshness, and operating cost on a representative workload. If query-time movement remains large after safe pushdown, test an approved materialized model.
实际阈值应由证据而非偏好决定:在代表性负载上比较扫描行数、传输字节、来源 CPU、端到端延迟、故障率、新鲜度与运行成本。若安全下推后查询时移动量仍然很大,应测试获批的物化模型。
Federated Query Limits You Should Verify需要核对的联邦查询限制
Read-only access只读访问
BigQuery states that the external statement must be read-only, so DML and DDL are rejected. Databricks documents foreign tables as read-only, with a narrow exception for a federated Hive metastore. Plan on reads unless the specific engine documents writes.
BigQuery 要求外部语句只读,因此会拒绝 DML 和 DDL。Databricks 将外部表记为只读,联邦 Hive metastore 是窄例外。除非该引擎明确写了写入能力,否则按只读来设计。
Region, quota, and types区域、配额与类型
BigQuery allows a single-region dataset to query a source in that same region, and it documents a cross-region byte cap plus a limit of 10 unique connections on one federated query. Those numbers belong to BigQuery. Other engines publish different quotas. Cost may follow bytes returned or slots consumed, and the source database still has its own limits. A read replica is the usual way to keep analytical scans off the primary.
BigQuery 允许单区域数据集查询同一区域的来源,并写明跨区字节上限,以及一条联邦查询最多 10 个不同连接。这些数字属于 BigQuery。其他引擎的配额不同。费用可能按返回字节或 slot 计算,来源数据库仍有自己的限制。常用做法是查只读副本,避免分析扫描打到主库。
Unsupported types fail the query until they are cast. Collation can also change the answer: a case-insensitive comparison executed on the source is not the same as the engine's default case-sensitive filter applied after the rows return. If a time grain differs across sources, prune and align that grain before the join. PostgreSQL's foreign-data wrapper planning notes show why remote paths, rechecks, and join placement have to be read from the plan.
不支持的类型在转换之前会导致查询失败。排序规则也会改变答案:在来源上执行的不区分大小写比较,不同于行返回后引擎默认的区分大小写过滤。来源时间粒度不同时,应在连接前先裁剪并对齐。PostgreSQL 外部数据包装器规划说明解释了为什么远程路径、复查和连接位置必须从计划里读。
When to Reject the Federated Query何时拒绝这条联邦查询
If a mandatory filter, authorization predicate, time boundary, precision rule, or row limit cannot be preserved, reject the federated query or use an approved alternative. Silently running a different operation is not optimization.
如果强制过滤、授权谓词、时间边界、精度规则或行数限制无法保持,就拒绝这条联邦查询,或改用已批准的替代方案。悄悄执行另一种操作并不是优化。
Federated Query Use Cases联邦查询的使用场景
Live reporting实时报表
Redshift's overview is explicit: a federated query can put live operational rows into a BI report and apply transformations without a standing ETL pipeline for that question. The report is only as current as the source statement and the pushdown you verified.
Redshift 的概览写得很明确:联邦查询可以把实时业务行放进 BI 报表,并做转换,而不必为这个问题维护一条常驻 ETL。报表的新鲜度取决于来源语句,以及你核对过的下推。
Proof of concept概念验证
Databricks reserves query federation for on-demand reporting, proofs of concept, and the start of an ETL design. That is the right window to learn join keys, grain, and selectivity before you pay for a pipeline.
Databricks 把查询联邦用于按需报表、概念验证和 ETL 设计的起步阶段。这是在为管道付费之前,弄清连接键、粒度和选择性的合适窗口。
Migration window迁移窗口
While history is being copied, a federated query can still read the system that has not moved. Keep the cutover rule explicit: which source wins for a given date, what happens when one side fails, and when the live path is retired. The data virtualization guide is the place for the longer access-layer design.
历史数据仍在复制时,联邦查询可以继续读取还没迁走的系统。切换规则要写清:某个日期以哪边为准、一侧失败时怎么办、以及何时停用实时路径。更长的访问层设计见数据虚拟化指南。
Use InfiniSynapse for Related Approved Multi-Source Analysis使用InfiniSynapse执行相关获批多来源分析
The InfiniSynapse public product pageInfiniSynapse公开产品页面 visibly describes direct connections to supported databases and multi-source joint analysis. That makes the application a relevant entry when the actual task is approved analysis across supported sources. The existing data-source identification guide数据源识别指南 and data-quality guide数据质量指南 can help prepare source scope and checks.
InfiniSynapse public product pageInfiniSynapse公开产品页面明确描述了对受支持数据库的直接连接和多来源联合分析。当实际任务是在受支持来源之间开展获批分析时,该应用可作为相关入口。现有数据源识别指南数据源识别指南和数据质量指南数据质量指南可帮助准备来源范围和检查。
This page does not claim that every InfiniSynapse connection implements a universal federated SQL engine, arbitrary cross-source join, connector pushdown, distributed transaction, source-native identity delegation, full EXPLAIN plan, workload governor, or every capability discussed above. Confirm the exact visible source and workflow before relying on it.
本页不声称每个InfiniSynapse连接都实现通用联邦SQL引擎、任意跨源连接、连接器下推、分布式事务、来源原生身份委派、完整EXPLAIN计划、工作负载治理器或本文讨论的全部能力。使用前应确认确切可见来源与工作流。
Before opening the application, prepare confirmed supported connection details, data-owner approval, least-privilege credentials, network and certificate requirements, approved tables and fields, join keys and grain, time and freshness rules, reconciliation checks, expected result size, and source-load limits.
打开应用前,请准备已确认支持的连接信息、数据所有者批准、最小权限凭据、网络与证书要求、获批表与字段、连接键与粒度、时间与新鲜度规则、核对检查、预期结果大小和来源负载限制。
After support, authorization, semantics, freshness, reconciliation, and workload limits are confirmed, open InfiniSynapse for the related multi-source analysis workflow.
确认支持、授权、语义、新鲜度、核对和工作负载限制后,打开InfiniSynapse执行相关多来源分析工作流。
Analyze approved data sources分析获批数据来源Federated Query FAQ联邦查询常见问题
What is a federated query?
什么是联邦查询?
A federated query is one logical query whose execution plan reads from two or more separately managed data sources and combines selected results at query time. A query engine resolves source objects, translates types and operations through connectors, pushes safe work to sources, executes remaining joins or aggregates, and returns one result with source and execution evidence.
联邦查询是一条逻辑查询,其执行计划读取两个或更多分别管理的数据源,并在查询时组合选定结果。查询引擎解析来源对象,通过连接器转换类型与操作,把安全工作下推到来源,执行剩余连接或聚合,再返回带来源与执行证据的统一结果。
How does a federated query work?
联邦查询如何工作?
The engine binds identity and session context, parses the query, resolves catalogs and objects, checks policy and connector capabilities, chooses execution locations and join order, generates source-native subplans, runs remote and local stages, normalizes returned types, combines results, and returns provenance, observation times, warnings, coverage, plan identity, rows, bytes, and timing.
引擎绑定身份与会话上下文,解析查询,定位目录与对象,检查策略与连接器能力,选择执行位置与连接顺序,生成来源原生子计划,运行远端和本地阶段,规范返回类型,组合结果,再返回来源证明、观察时间、警告、覆盖、计划身份、行数、字节和时序。
Does a federated query copy data?
联邦查询会复制数据吗?
It does not require every source dataset to be copied into one permanent store before the query. Data can still cross the network and may be exchanged, buffered, spilled, staged, cached, logged, or returned. Every intermediate artifact needs explicit authorization, encryption, retention, invalidation, deletion, provenance, and freshness rules.
它不要求在查询前把每个来源数据集复制到一个永久存储中,但数据仍可能跨网络传输,并被交换、缓冲、溢写、暂存、缓存、记录或返回。每种中间工件都需要明确的授权、加密、保留、失效、删除、来源证明和新鲜度规则。
Are federated queries read-only?
联邦查询通常是只读的吗?
Often yes. BigQuery rejects DML and DDL in the external statement. Databricks documents foreign tables as read-only except a federated Hive metastore case. Confirm the engine you will run. Do not assume writes from the label.
通常是。BigQuery 会拒绝外部语句中的 DML 和 DDL。Databricks 将外部表记为只读,联邦 Hive metastore 是窄例外。以实际运行的引擎文档为准,不要从功能名称推断可以写入。
Are federated queries slower than local queries?
联邦查询会比本地查询慢吗?
They can be. The engine waits on the source, moves intermediate rows, and may lack the source indexes in its own plan. Pushdown, region proximity, and selective filters narrow the gap. A repeated full scan usually belongs in a materialized model.
可能会。引擎要等待来源、移动中间结果,而且自己的计划里未必有来源上的索引。下推、区域距离和有选择性的过滤能缩小差距。反复的全表扫描通常更适合物化模型。
What is query pushdown in federation?
联邦中的查询下推是什么?
Pushdown delegates supported operations such as predicates, projections, aggregates, joins, limits, or Top-N to a connected source. It can reduce transfer and coordinator work, but support varies by connector, source, version, expression, and query shape. Verify the actual EXPLAIN plan and source logs; never assume pushdown from a feature label.
下推把连接来源支持的谓词、投影、聚合、连接、限制或Top-N等操作委派给来源执行,可以减少传输和协调器工作。但支持情况会因连接器、来源、版本、表达式与查询形状而异。必须检查实际EXPLAIN计划与来源日志,不能从功能标签推断。
What happens when one federated query source fails?
一个联邦查询来源失败时会发生什么?
Follow a declared result policy. Fail closed when the source is mandatory or partial data could be unsafe; return an explicitly marked partial result only when policy and consumers allow it; or use an approved bounded cache or materialized fallback with visible observation time and coverage. Deadlines and cancellation must bound downstream source work.
应遵循已声明结果策略。来源必需或部分数据可能不安全时关闭式失败;仅在策略与使用者允许时返回明确标记的部分结果;或使用带可见观察时间与覆盖的获批有边界缓存或物化回退。截止时间与取消必须限制下游来源工作。
When should data be materialized instead of queried through federation?
何时应物化数据而不是使用联邦查询?
Prefer materialization, replication, or centralized integration when repeated high-volume scans, stable shared history, predictable latency, strict availability, common semantics, source isolation, or recurring heavy joins outweigh live access. A hybrid can materialize historical or expensive components while keeping small current dimensions live, provided time, coverage, precedence, and rollback are explicit.
当重复高容量扫描、稳定共享历史、可预测延迟、严格可用性、统一语义、来源隔离或重复重连接的重要性高于实时访问时,应优先物化、复制或集中式集成。混合方案可以物化历史或昂贵组件,同时保持小型当前维度实时,但必须明确时间、覆盖、优先级和回滚。
Official Sources and Verification Notes官方来源与验证说明
- Trino concepts for coordinators, workers, catalogs, connectors, stages, tasks, splits, and distributed query executionTrino关于协调器、工作节点、目录、连接器、阶段、任务、分片与分布式查询执行的概念文档
- Trino connector-specific predicate, projection, aggregation, join, limit, and Top-N pushdown documentationTrino连接器专属谓词、投影、聚合、连接、限制与Top-N下推文档
- Amazon Athena Federated Query connector and external-source documentationAmazon Athena联邦查询连接器与外部来源文档
- Google BigQuery introduction to federated queries, supported sources, pushdown, and limitationsGoogle BigQuery关于联邦查询、受支持来源、下推与限制的介绍
- Amazon Redshift documentation for querying operational databases and combining remote and local dataAmazon Redshift关于查询业务数据库并组合远程与本地数据的文档
- PostgreSQL foreign-data-wrapper planning documentation for paths, rechecks, remote joins, and upper relationsPostgreSQL关于路径、重检、远程连接与上层关系的外部数据包装器规划文档
- Databricks query federation and when to ingest insteadDatabricks 查询联邦,以及何时改为摄入
These sources establish concrete behavior for their documented implementations. They do not establish one universal federated-query feature set. Verify the exact engine edition, connector and version, source and version, region, topology, identity path, query operators, type mappings, plan behavior, limits, failure semantics, availability, licensing, pricing, and commercial terms you will operate.
这些来源为其记录的具体实现建立行为证据,但不建立通用联邦查询功能集。请针对计划运行的确切引擎版本、连接器及版本、来源及版本、区域、拓扑、身份路径、查询操作符、类型映射、计划行为、限制、故障语义、可用性、许可、定价和商业条款重新验证。