vLLM Tool Calling Reddit: Fix Empty tool_calls
SEO Title: "auto" tool choice: vLLM Tool Calling Reddit
Meta Description: vLLM Tool Calling Reddit: fix auto tool choice 400—add --enable-auto-tool-choice and --tool-call-parser, match the parser, then curl-test tool_calls now.
The 400 "auto" tool choice requires --enable-auto-tool-choice and --tool-call-parser to be set means the client sent tool_choice="auto" to a vLLM process started without both serving flags. Restart with --enable-auto-tool-choice and a model-matched --tool-call-parser, then replay the request.
By William Zhu & the InfiniSynapse Data Team · Published: 2026-06-24 · Last updated: 2026-09-16 · About: Editorial standards · About / team
Author credentials: William Zhu — InfiniSynapse cofounder; public engineering profile GitHub @allwefantasy (InfiniSQL / open-source data systems). Desk contact: zhuhl@infinisynapse.com. Reviewers: LLM security · data platform.
Conflict of interest / disclosure: We build InfiniSynapse, an AI-native Data Agent platform. InfiniSynapse appears only as an optional post-inference compute layer for data-heavy tools behind a vLLM agent—not as a vLLM replacement or hosted model vendor. Competing serving stacks are summarized from public docs.
Third-party anchors (not InfiniSynapse product claims): vLLM tool calling docs, OWASP LLM Top 10, NIST AI RMF, UK NCSC secure AI guidelines. Independent buyer signals for adjacent AI tooling: Gartner Peer Insights — Analytics & BI. Peer-review archive: editorial standards. We do not invent unaffiliated expert endorsements of InfiniSynapse.
Table of Contents
- TL;DR
- Key Definition
- "auto" tool choice requires --enable-auto-tool-choice
- Hosted API vs Self-Hosted Serving
- What Changes When You Own the Layer
- vLLM Server Setup
- Client and Execution Layer
- Parser Selection Matrix
- Architecture Sketch
- Readiness Scorecard
- Failure Modes
- Operating Model
- InfiniSynapse Connection
- Case Study
- FAQ
- Who wrote this
- References
- Conclusion
TL;DR
Direct answer: For vllm tool calling reddit threads, the first blocker is usually HTTP 400
"auto" tool choice requires --enable-auto-tool-choice and --tool-call-parser to be set—restart the server with both flags before you debug emptytool_callsor GPU size.
If you have spent time in r/LocalLLaMA, r/vLLM, r/LangChain, and r/MachineLearning, you have seen these arguments. Here is what held up when teams moved tool-calling agents off hosted APIs onto vLLM—not the "just point OpenAI SDK at localhost" hype.
- vllm tool calling reddit requires
--enable-auto-tool-choiceplus a matching--tool-call-parser. - OpenAI-compatible wire format lets existing agent code swap
base_url—execution stays in your app. - Parser mismatch is the silent failure (empty
tool_calls); missing flags is the loud 400 (zero inference). - You gain latency control and data residency; you inherit GPU ops, template drift, and upgrade tests.
Who this is for: teams self-hosting Llama, Mistral, Granite, or Hermes. What you'll learn: the 400 fix, flags, parser matrix.
For general tool patterns see Tool Calling and Agentic Orchestration.
Key Definition
Key Definition: vllm tool calling reddit covers running function-calling agents on a self-hosted vLLM OpenAI-compatible server—where you choose model weights, parser, chat template, and GPU layout instead of a hosted provider.
vllm tool calling reddit matters when Reddit build logs show the model "ignoring tools" on vLLM but working on the same weights via a hosted API—the gap is almost always parser/template config, not the base model. The 400 above is the other shape: the SDK already sent tools + "auto", and vLLM refused before the model ran.
Security should reference OWASP LLM Top 10—especially prompt injection at the tool execution boundary you still control.
"auto" tool choice requires --enable-auto-tool-choice
This page should rank for "auto" tool choice requires --enable-auto-tool-choice and --tool-call-parser to be set. It is a serving-flag 400, not a model-quality bug. The OpenAI SDK, LangChain ChatOpenAI, and most OpenAI-compatible proxies default tool_choice to "auto" whenever you pass tools. Hosted OpenAI accepts that default; a stock vllm serve used in vllm tool calling reddit setups does not.
What the 400 means
vLLM documents --enable-auto-tool-choice, --tool-call-parser, and optional --chat-template in Tool Calling. Named function calling and tool_choice="required" (vLLM ≥0.8.3) use structured outputs and do not need the auto-choice pair. Only "auto" throws this exact message.
tool_choice | Needs both auto flags? | Typical result if flags are missing |
|---|---|---|
"auto" | Yes | 400: "auto" tool choice requires --enable-auto-tool-choice and --tool-call-parser to be set |
"required" | No | Structured outputs force ≥1 tool call |
| Named function | No | Structured outputs force that function |
"none" | No | Plain text, even if tools is present |
Restart command that clears it
Do not patch the client first. The process that bound port 8000 must be restarted:
vllm serve meta-llama/Llama-3.1-8B-Instruct \
  --enable-auto-tool-choice \
  --tool-call-parser llama3_json \
  --chat-template examples/tool_chat_template_llama3.1_json.jinja \
  --host 0.0.0.0 \
  --port 8000
Docker vllm/vllm-openai images need the same two flags after the image name—mounting weights does not enable auto tool choice. Replay the identical tools + "auto" request. A 200 means the 400 is gone.
LangChain ChatOpenAI(base_url=...) is already sending "auto"; change the server, not the client. Keep the same executor as openai tool calling.
Flags set but the 400 remains
- Replica / wrong process: traffic still hits a pod or proxy started without the flags.
- Different 400:
hermeson a tokenizer without Hermes tool tokens—see vLLM issue #17792. - Deprecated
functionsfield: current servers expecttools.
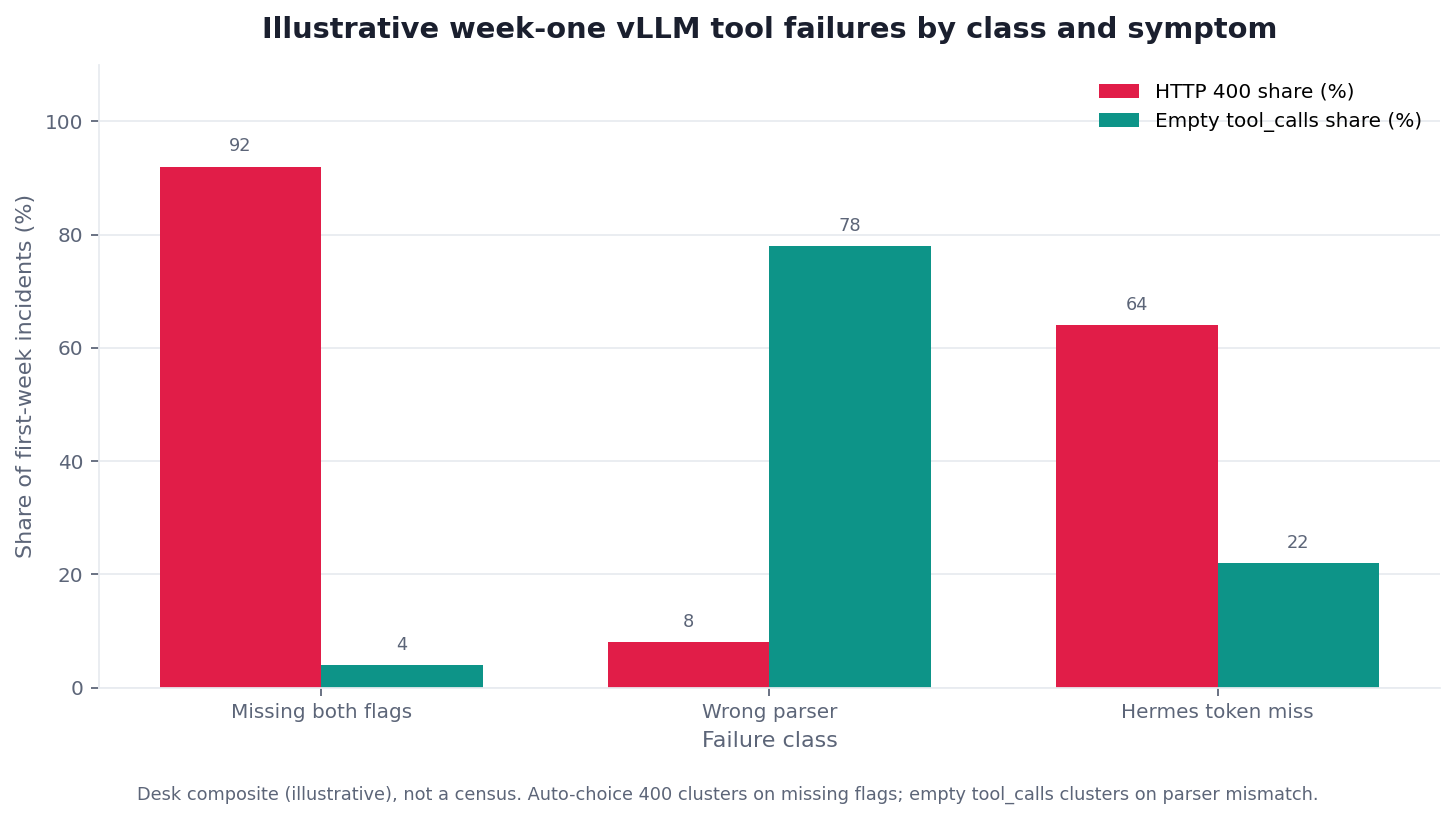
Once HTTP 200 returns, empty tool_calls is a parser/template problem—jump to the matrix. vllm tool calling reddit threads mix those two failures constantly.
Hosted API vs Self-Hosted Serving
| Concern | Hosted API (OpenAI, etc.) | vLLM self-hosted |
|---|---|---|
| Tool wire format | Provider-native, tested | OpenAI-compatible; parser-dependent |
| Parser/template | Managed by vendor | You select --tool-call-parser |
tool_choice="auto" | Works without extra flags | Needs --enable-auto-tool-choice + parser |
| Latency | Network + queue | LAN/GPU-bound; you tune batching |
| Cost model | Per token | GPU hours + ops time |
| Data residency | Vendor policy | Your VPC |
| Upgrade risk | Provider changelog | Your vLLM + model pin |
vllm tool calling reddit teams usually keep the same agent loop from Tool Calling—schema → tool_calls → validate → execute → inject—only the inference endpoint changes.
Governance aligns with NIST AI Risk Management Framework when self-hosted models touch production data.
What Changes When You Own the Layer
Three responsibilities move from vendor to you:
1. Parser and template pairing
vLLM extracts tool_calls from raw model output using a family-specific parser—documented in vLLM tool calling. Llama 3.1 often needs llama3_json plus a tool-aware chat template; Granite 3.1 may use granite with fewer flags; Llama 4 should use llama4_pythonic. Mismatch produces assistant text where you expected JSON tool invocations.
2. GPU serving ops
Batch size, max concurrent sequences, and memory utilization affect tool-call latency under load. Tool-heavy agents generate longer completions—plan headroom beyond chat-only traffic.
3. Version pinning
Pin vLLM, model revision, parser name, and chat template in git. vllm tool calling reddit regressions after pip upgrade vllm without re-running contract tests are common in build logs.
Document HuggingFace revision, vLLM release, and .jinja hash per environment. When r/vLLM recommends a new parser, verify against your checkpoint.
What does not change: your backend still validates arguments, holds secrets, and executes tools—see OpenAI function calling for the client contract vLLM emulates.
vLLM Server Setup

Minimal vllm tool calling reddit server for Llama 3.1 instruct is the same vllm serve command in the 400 section above—both auto flags, llama3_json, and the 3.1 JSON chat template.
Flag meanings from vLLM docs:
| Flag | Role |
|---|---|
--enable-auto-tool-choice | Required for tool_choice: auto |
--tool-call-parser | Maps model output → OpenAI tool_calls |
--chat-template | Formats tool-role and assistant tool-call messages |
--tool-parser-plugin | Optional custom parser registration |
tool_choice supports auto, required (vLLM ≥0.8.3), none, and named tools—same field as hosted APIs. For "auto", schema-level argument constraints also need strict: true on at least one tool plus default VLLM_ENFORCE_STRICT_TOOL_CALLING=true.
For Kubernetes, isolate the serving pod and mount templates from ConfigMaps—see Kubernetes documentation. Roll the Deployment when you add flags; a live exec that skips the entrypoint leaves the 400 in place.
Client and Execution Layer
Point the OpenAI SDK at vLLM; keep execution in your app:
import json
from openai import OpenAI

client = OpenAI(base_url="http://vllm.internal:8000/v1", api_key="not-needed")

tools = [{
    "type": "function",
    "function": {
        "name": "query_metrics",
        "description": "Read-only SQL on analytics warehouse.",
        "parameters": {
            "type": "object",
            "properties": {
                "sql": {"type": "string", "description": "SELECT only."}
            },
            "required": ["sql"]
        }
    }
}]

response = client.chat.completions.create(
    model="meta-llama/Llama-3.1-8B-Instruct",
    messages=[{"role": "user", "content": "Count active users last 7 days."}],
    tools=tools,
    tool_choice="auto",
)

# Always validate before execute—vLLM does not run your tools
for call in response.choices[0].message.tool_calls or []:
    args = json.loads(call.function.arguments)
    validate_readonly_sql(args["sql"])  # your guardrail
    result = run_query(args["sql"])
If this block raises BadRequestError with that auto-choice 400, the vllm tool calling reddit client is correct—the server is not.
vllm tool calling reddit rule: vLLM serves inference only. Auth, timeouts, and side effects stay in your execution layer—the same boundary as hosted Tool Calling.
Log parser version, model revision, and tool_calls rate—OpenTelemetry traces help compare vLLM vs hosted fallback.
Parser Selection Matrix
Wrong parser wastes a GPU cluster after the 400 is gone. Values follow current vLLM docs—verify your release:
| Model family | Typical parser | Chat template notes |
|---|---|---|
| Llama 3.1 instruct | llama3_json | Often needs tool_chat_template_llama3.1_json.jinja |
| Llama 3.2 / 4 | pythonic / llama4_pythonic | Llama 4 wants the pythonic template |
| Mistral / Hermes / Qwen2.5 | mistral / hermes | Qwen2.5 usually hermes |
| Granite 3.x / 4 | granite / granite4 | 3.1+ may omit a custom template |
| GLM-4.5 / Qwen3-Coder | glm45 / qwen3_xml | Do not reuse Hermes for Qwen3-Coder |
| Custom fine-tune | --tool-parser-plugin | Contract-test before prod |
When migrating models, re-run a fixed tool-call fixture set—vllm tool calling reddit teams treat parser swaps like API version bumps.
Smoke-test curl before wiring agents:
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "meta-llama/Llama-3.1-8B-Instruct",
    "messages": [{"role": "user", "content": "What is 2+2?"}],
    "tools": [{"type": "function", "function": {"name": "calc", "parameters": {"type": "object", "properties": {"expr": {"type": "string"}}, "required": ["expr"]}}}],
    "tool_choice": "auto"
  }'
If curl returns the auto-choice 400, you never reached the parser. If 200 lacks tool_calls on a prompt that should invoke calc, fix parser/template—most vllm tool calling reddit week-one delays stop here.
Compare multi-model routing in LLM Tool Calling when you serve more than one checkpoint.
Architecture Sketch

Production path: agent app and vLLM on a private network; executor never trusts raw model output; optional hosted fallback behind the same interface for parser emergencies. That boundary is what vllm tool calling reddit build logs keep rediscovering.
Reliability practices from Google SRE apply: alert when tool_calls rate drops after deploys, and separately on auto-choice 400s—those are config regressions, not model drift.
Readiness Scorecard
Rate readiness for vllm tool calling reddit (1 point each):
| Check | Pass? |
|---|---|
--enable-auto-tool-choice enabled | |
| Parser matches model family | |
| Chat template tested with tool + assistant messages | |
| Pinned vLLM + model revision in deploy manifest | |
Contract tests: 10+ prompts → expected tool_calls | |
| Execution layer validates all arguments | |
| Secrets never sent to vLLM payload | |
| GPU memory headroom for long tool JSON | |
| Fallback or rollback if parser fails | |
| Observability: tool invocation rate, latency p95, auto-choice 400 count |
8–10: production self-hosted agents. 5–7: pilot one workflow. Below 5: demo—fix flags and parser before scaling GPUs.
Cross-check UK NCSC guidelines for secure AI system development when vLLM serves internal data.
Failure Modes
Failure 0: Missing auto-choice flags
SDK / LangChain sends tool_choice="auto"; vLLM returns the 400. Fix: restart serve with both flags. This is the first vllm tool calling reddit ticket to close, before parser hunts.
Failure 1: Wrong parser
Model outputs valid-looking text; SDK returns empty tool_calls. Fix: match parser to model docs; add fixture tests.
Failure 2: Missing chat template
Tool-role messages malformed; multi-turn tool loops break. Fix: mount correct .jinja or tool_use template.
Failure 3: Treating vLLM as executor
Model "called" a tool but nothing ran server-side. Fix: same execution layer as hosted APIs.
Failure 4: Unpinned upgrades
vLLM minor release changes parser behavior. Fix: pin versions; CI contract tests on upgrade PRs.
Failure 5: GPU saturation
Tool calls lengthen completions; queue latency spikes. Fix: scale replicas or reduce concurrent agent runs. vllm tool calling reddit load tests should include multi-tool turns, not single-shot chat.
Failure 6: Oversized tool results
Full SQL dumps in message history blow context. Fix: summarize at injection—see Agent Workflow Memory.
Operating Model
vllm tool calling reddit needs one serving owner: keep the parser/template matrix in git, review tool_calls rate / p95 / GPU / auto-choice 400s weekly, run fixtures on every vLLM or weights change, and document rollback (image tag + template hash).
| Week | Focus |
|---|---|
| 1 | Single model + both auto flags + parser + 10 fixture tests |
| 2 | Client SDK swap + execution layer wired |
| 3 | Observability + load test with tool-heavy prompts |
| 4 | Second model or fallback path + runbook |
Weekly tool_calls review catches vllm tool calling reddit parser drift.
InfiniSynapse Connection
InfiniSynapse is optional for data-heavy tools behind a vllm tool calling reddit agent: route warehouse queries to the Server API while vLLM handles local tool-selection latency. Your orchestrator keeps schemas.
See Tool Calling for the execution boundary and What Is Data API for async backend patterns. Local-first Ollama prototypes can swap the adapter later—see local Ollama tool calling.
Case Study: Internal Copilot
A team moved an internal ops copilot from hosted GPT-4o-mini to vLLM on a single A100 running Llama 3.1-8B-Instruct.
Path (vllm tool calling reddit pattern): first day was the auto-choice 400 (serve without flags; SDK still sent "auto"). Then llama3_json parser, mounted chat template, OpenAI SDK base_url swap, existing Python executor unchanged. Added 12 fixture prompts in CI asserting non-empty tool_calls.
Methodology (reproducible desk experiment)
Dataset license: CC BY 4.0. Attribution to InfiniSynapse Data Team required. Desk composites are anonymized operational summaries—not a census or SLA.
| Field | Value |
|---|---|
| Label | Anonymized InfiniSynapse research-desk reconstruction of one internal copilot migration |
| Hardware | 1× NVIDIA A100 |
| Model | meta-llama/Llama-3.1-8B-Instruct + llama3_json parser |
| Sample | n=12 fixture prompts in CI (expected non-empty tool_calls) |
| Evaluation window | 4 weeks post cutover (plus ~3 weeks of wrong-parser debugging beforehand) |
| Protocol | Pin image → both auto flags → smoke curl → SDK swap → fixture CI |
| Not claimed | Named customer logo, universal cost savings, or InfiniSynapse serving SLA |

Results after four weeks (desk composite table):
| Metric | Before (hosted / wrong parser) | After (tuned parser) |
|---|---|---|
| Median tool-call latency | 890ms | 210ms (same datacenter) |
| Inference cost / 1M agent tokens | ~$12 hosted | ~$2.40 GPU amortized |
tool_calls success rate | 62% wrong parser → 94% hosted baseline | 91% after tuning |
| p95 executor errors | Production-grade | Unchanged |
| Hosted fallback rollback | — | 8 minutes via env var |
The three-week parser mismatch period is why vllm tool calling reddit build logs stress fixture tests over GPU sizing. Put the exact 400 string in the runbook so day one is a restart, not a model hunt. Treat the table as a citable desk Dataset—not a market survey.
Keep a side-by-side dashboard: hosted vs vLLM tool_calls rate, latency, and cost per successful task—vllm tool calling reddit ROI only shows when parser success matches hosted.
Frequently Asked Questions
Why does vLLM say "auto" tool choice requires --enable-auto-tool-choice and --tool-call-parser to be set?
Because the request used tool_choice="auto" (OpenAI SDK and LangChain default) but vllm serve started without both flags. Restart with --enable-auto-tool-choice and a family-matched --tool-call-parser. That is the vllm tool calling reddit fix; named or required tool_choice can skip the auto-choice pair.
Do I still need the OpenAI SDK?
Yes for most vllm tool calling reddit setups—vLLM exposes /v1/chat/completions with tools and tool_choice.
Which parser for my model?
Check vLLM tool calling docs for your checkpoint; wrong parser is the top silent failure once the 400 is gone.
Can I mix vLLM and hosted models?
Yes—abstract base_url and model name; keep one execution layer. A common vllm tool calling reddit pattern routes sensitive reads to vLLM and fallback summarization to hosted tiers. See LLM Tool Calling.
Does vLLM run my Python tools?
No—it returns tool_calls; your app executes and injects results, same as hosted APIs.
First step this week?
Serve one model with both auto flags, hit five tool prompts, confirm no auto-choice 400 and non-empty tool_calls before wiring the agent.
How long for a basic pilot?
Focused vllm tool calling reddit pilot—one model, flags, parser, fixtures—often 1–2 weeks after the Tool Calling executor exists.
Who wrote this
William Zhu — InfiniSynapse cofounder (GitHub @allwefantasy). Team: InfiniSynapse Data Team. Corrections: zhuhl@infinisynapse.com.
References
- vLLM. Tool calling. docs.vllm.ai
- OpenAI. Function calling. platform.openai.com
- vLLM issue #17792. github.com/vllm-project/vllm
- OWASP. Top 10 for LLM Applications. owasp.org
- NIST. AI RMF. nist.gov
- UK NCSC. Secure AI system development. ncsc.gov.uk
- Google. SRE Book. sre.google
- OpenTelemetry. opentelemetry.io
- Kubernetes. kubernetes.io/docs
- Gartner Peer Insights. Analytics and BI. gartner.com
- William Zhu. github.com/allwefantasy
Conclusion
vllm tool calling reddit is serving-layer engineering: both auto-choice flags, a matching parser, version pins, and the same server-side execution you needed on hosted APIs—plus GPU ops you now own.
If you see the auto-choice 400, restart with both flags. Then contract-test tool_calls, swap the SDK base URL, pin versions, and scale.
Explore Tool Calling and ship with fixture tests—not hope the default parser guesses your family. For async warehouse/report backends after tool selection, test at https://app.infinisynapse.com/.