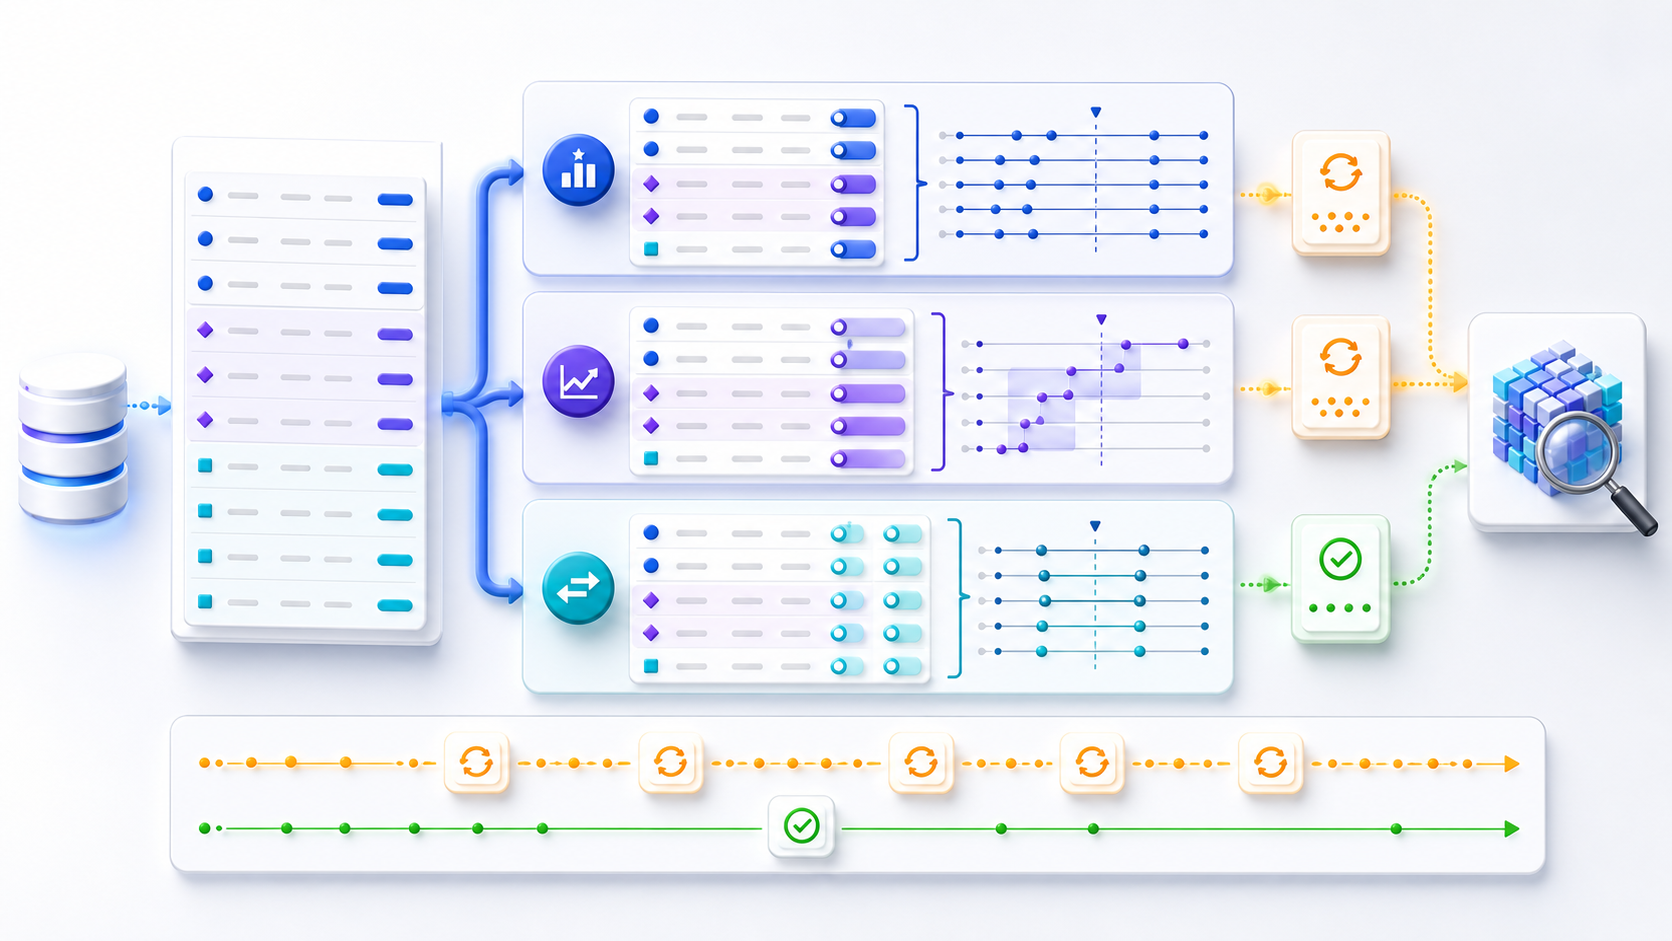
What are window frames in SQL?
Window frames in SQL are the subset of a partition that a frame-sensitive function can see for the current row. The frame moves as each row is processed. PARTITION BY restarts the calculation; that restart boundary is a partition. When ORDER BY is present and no frame is written, the usual default is RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW. When ORDER BY is absent, the frame is the whole partition.
SQL window functions still return a value on every detail row through OVER. Ranking, running totals, moving averages, and previous or next comparisons stay on this page. SUM, AVG, FIRST_VALUE, and LAST_VALUE read the frame. ROW_NUMBER, RANK, LAG, and LEAD follow the partition and the order.
A window definition can contain PARTITION BY, window ORDER BY, and a frame. Partitioning decides where calculations restart. Ordering defines sequence and peers. The frame decides which rows around the current row are visible to frame-sensitive calculations. Treat these as separate design choices.
window_function(expression) OVER (
  PARTITION BY group_key
  ORDER BY sequence_key, unique_tie_breaker
  ROWS BETWEEN frame_start AND frame_end
)
Choose the right window function family
Window functions solve different questions. Ranking functions describe position; offset functions inspect another row; value functions read values at frame boundaries; aggregate functions calculate over a window rather than collapsing a group. Choosing by question prevents complex expressions from being used where a simpler group or join is clearer. ROW_NUMBER, RANK, and LAG use the partition and the order. Frame bounds apply to SUM, AVG, FIRST_VALUE, and LAST_VALUE.
| Family | Examples | Question answered | Main caution |
|---|---|---|---|
| Ranking | ROW_NUMBER, RANK, DENSE_RANK, NTILE | Where does this row sit in its partition? | Tie semantics and deterministic order |
| Offsets | LAG, LEAD | What came before or comes next? | Sequence gaps and repeated timestamps |
| Frame values | FIRST_VALUE, LAST_VALUE, NTH_VALUE | What value is at a frame boundary? | Default frames can surprise LAST_VALUE |
| Window aggregates | SUM, AVG, COUNT, MIN, MAX | What is the partition, running, or moving metric? | Frame and duplicate-row effects |
Separate partition boundaries from row ordering
PARTITION BY customer_id creates an independent customer calculation. Omitting it makes the whole filtered result one partition. Window ORDER BY defines logical order inside each partition but does not guarantee final presentation order. Add a query-level ORDER BY when the delivered rows must be sorted.
SELECT
  order_id, customer_id, order_date, amount,
  ROW_NUMBER() OVER (
    PARTITION BY customer_id
    ORDER BY order_date, order_id
  ) AS order_sequence
FROM orders
WHERE status = 'completed'
ORDER BY customer_id, order_sequence;
The unique order_id resolves equal timestamps. Without a tie-breaker, functions that need a unique sequence may choose peer order unpredictably. Peer-aware functions such as RANK intentionally treat equal ordering values together, so the business meaning of ties should determine the function.
Define window frames instead of trusting defaults
A frame is the subset of the partition visible to the current row for frame-sensitive functions. Common units are ROWS, RANGE, and, where supported, GROUPS. ROWS counts physical result rows. RANGE considers ordering values and peers that share that value. GROUPS counts peer groups. Dialect support and restrictions vary.
| Bound | What it reaches |
|---|---|
UNBOUNDED PRECEDING | The first row of the partition |
N PRECEDING | N rows before the current row for ROWS, or N units of the sort value for RANGE |
CURRENT ROW | The current row; under RANGE, its peer group |
M FOLLOWING | M rows or M sort-value units after the current row |
UNBOUNDED FOLLOWING | The last row of the partition |
| Short form | Same as |
|---|---|
UNBOUNDED PRECEDING | BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW |
N PRECEDING | BETWEEN N PRECEDING AND CURRENT ROW |
CURRENT ROW | BETWEEN CURRENT ROW AND CURRENT ROW |
N FOLLOWING | BETWEEN CURRENT ROW AND N FOLLOWING |
UNBOUNDED FOLLOWING | BETWEEN CURRENT ROW AND UNBOUNDED FOLLOWING |
SUM(amount) OVER (
  PARTITION BY customer_id
  ORDER BY order_date, order_id
  ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
) AS running_revenue
With duplicate ordering values, the default RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW includes every peer and can make a running total jump by several rows. Explicit ROWS plus a unique ordering key creates row-by-row progression. For a moving seven-row average, use a bounded row frame; for seven calendar days, row count is not equivalent to time and a supported interval range or time-spine design may be required.
| order_id | order_date | amount | ROWS running sum | RANGE running sum |
|---|---|---|---|---|
| 1 | 2026-03-01 | 10 | 10 | 30 |
| 2 | 2026-03-01 | 20 | 30 | 30 |
| 3 | 2026-03-02 | 30 | 60 | 60 |
The ROWS column orders by order_date, order_id, so each physical row advances the sum. The RANGE column orders by order_date alone, so both March 1 rows are peers and the first row already shows 30. This is a worked example of peer membership, not a benchmark.
SQL Server accepts RANGE with UNBOUNDED and CURRENT ROW. A count such as 1 PRECEDING belongs on ROWS there. PostgreSQL also accepts GROUPS, which steps by peer group. Confirm the frame your deployed engine actually runs. A year-wide MAX needs ROWS BETWEEN UNBOUNDED PRECEDING AND UNBOUNDED FOLLOWING; the default upper bound stops at the current row's peers.
LAST_VALUE is a classic default-frame trap. With an ordered default frame ending at the current row's peer group, “last” may mean the current value, not the final value in the partition. Specify an unbounded-following frame when the business question needs the partition's final row.
Apply window functions to real analytical patterns
Rank inside each partition, then filter outside. Choose ROW_NUMBER for exactly N rows or RANK/DENSE_RANK when ties should share position.
Order descending by effective timestamp and a unique ingestion key, then keep row number 1. Verify that latest matches the business rule.
Use LAG after defining a complete period series. Missing months can otherwise turn “previous row” into an earlier nonadjacent period.
Divide a row measure by SUM over its partition, with explicit zero-denominator and duplicate-row handling.
SELECT
  region_id, month_start, revenue,
  revenue / NULLIF(
    SUM(revenue) OVER (
      PARTITION BY month_start
    ), 0
  ) AS share_of_month,
  revenue - LAG(revenue) OVER (
    PARTITION BY region_id
    ORDER BY month_start
  ) AS change_from_prior_month
FROM region_monthly_revenue;
Filter window results at the correct query level
Window functions are logically evaluated after the same-level WHERE, grouping, aggregation, and HAVING. Most dialects therefore cannot reference a window alias in that same level's WHERE. Compute the value in a subquery or CTE, then filter outside. Platforms supporting QUALIFY offer a direct window-result filter.
WITH ranked_products AS (
  SELECT
    category_id, product_id, revenue,
    ROW_NUMBER() OVER (
      PARTITION BY category_id
      ORDER BY revenue DESC, product_id
    ) AS rn
  FROM product_revenue
)
SELECT *
FROM ranked_products
WHERE rn <= 2;
Filter placement changes the population. Filtering inactive products inside the CTE ranks only active products. Ranking all products and filtering activity outside asks whether the already-ranked winner happens to be active. Both are valid SQL; they answer different questions.
Reduce repeated work across multiple windows
Several functions with the same partition and order can often share a named window or compatible sort. Functions using different ordering keys may require additional sort passes. A query ranking by revenue, sequencing by time, and calculating a moving average by another timestamp may therefore perform several expensive ordered operations even though each expression is short.
SELECT
  account_id, event_time, amount,
  SUM(amount) OVER w AS running_amount,
  LAG(amount) OVER w AS previous_amount,
  ROW_NUMBER() OVER w AS event_number
FROM account_events
WINDOW w AS (
  PARTITION BY account_id
  ORDER BY event_time, event_id
);
Named windows improve consistency and reduce copy-paste drift, but do not guarantee one physical sort. Inspect the actual plan. Also narrow rows before large sorts when semantics allow; carrying wide text or JSON columns through window operations increases memory and spill risk.
Review window-function performance with evidence
Performance depends on filtered row volume, partition distribution, sorting keys, existing order, memory, parallelism, indexes, and engine behavior. One huge partition can dominate memory even when average partitions are small. Nonselective joins before the window can multiply rows and make every later sort more expensive.
| Signal | Risk | Review |
|---|---|---|
| Several distinct window orders | Repeated sorts and memory pressure | Plan sort nodes and compatible definitions |
| Skewed partition key | One group dominates work | Largest and percentile partition sizes |
| Wide rows | Higher sort and spill payload | Early projection and late attribute joins |
| Unbounded frames | Large state or full-partition work | Confirm the business really needs all rows |
The PostgreSQL window-function reference documents ranking, offsets, value functions, peer groups, and frame-sensitive behavior. Use official documentation for the deployed engine because frame features and null-handling options vary.
Validate window logic before production
- Define the input grain. Audit joins and filters before window evaluation.
- State the partition. Explain why calculation restarts at that business boundary.
- Make order complete. Add stable tie-breakers where row sequence matters.
- Specify the frame. Test peers, first rows, last rows, sparse time periods, and empty frames.
- Check filter placement. Decide whether eligibility applies before or after the window result.
- Compare functions. Test ROW_NUMBER, RANK, and DENSE_RANK at tie boundaries when selecting top N.
- Profile partitions. Measure largest groups, not only averages.
- Inspect the plan. Review sorts, spills, repeated passes, estimates, and actual rows.
Review window functions as a complete analytical system in production
Production review should follow the data from source grain to final consumer rather than examining an isolated OVER clause. Record which rows enter each partition, which columns make ordering deterministic, which frame boundaries apply, and whether later joins or filters can duplicate or remove ranked rows. A technically valid window can still answer the wrong question when upstream data contains repeated events, late-arriving corrections, or multiple current records.
Build a small adversarial fixture before testing at scale. Include two rows tied on the visible sort key, a null ordering value, a one-row partition, a partition with duplicate timestamps, and a correction arriving after the original event. For running totals, add negative adjustments and duplicate business dates. For LAG or LEAD, verify the first and last rows explicitly. For ranking, decide whether ties should share a rank, create gaps, or be broken by a stable identifier.
| Failure signal | Likely mechanism | Evidence to collect |
|---|---|---|
| Rank changes between runs | Incomplete tie-breaker | Rows sharing the complete ORDER BY tuple |
| Running total jumps unexpectedly | Peer rows or duplicate facts | Frame membership and source-key counts |
| Query sorts repeatedly | Incompatible window specifications | Named windows and actual plan operators |
Finally, reconcile a sample partition manually and preserve that fixture as a regression test. Compare row counts before and after every join, check that the selected “latest” row is unique, and inspect actual memory, sort, spill, and parallelism evidence. Optimization is successful only when the result remains identical for ordinary rows, ties, nulls, sparse partitions, and late corrections.
Document engine-specific behavior too. Default frames, null ordering, support for named windows, and availability of QUALIFY differ across systems. Keep portable business logic separate from dialect shortcuts, and link each shortcut to a tested fallback. This makes migrations and mixed-engine reviews safer without forcing every query into the least capable syntax.
Inspect the complete window-function query
Paste a sanitized complete statement into the InfiniSynapse SQL Complexity Checker so windows, partitions, joins, CTEs, nested queries, and aggregation layers can be reviewed together. Then use your database plan and test data to validate runtime and semantics.
Open SQL Complexity CheckerRemove credentials, secrets, personal data, and sensitive literal values.SQL window functions frequently asked questions
It calculates a value for each result row using related rows defined by OVER while preserving detail rows.
GROUP BY collapses rows into groups; window functions keep rows and attach group- or frame-aware values.
PARTITION BY defines independent calculation groups. Window ORDER BY defines logical sequence and peers inside each group.
Window frames in SQL are the rows a frame-sensitive function can see for the current row. With ORDER BY and no frame written, the usual default is RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW, which includes peers that share the sort value. ROWS counts physical rows. RANGE uses the ordering value.
A partition is the restart boundary set by PARTITION BY. The frame is the subset of that partition visible to the current row. One product's rows are a partition. The frame is whichever of those rows the current calculation can see.
The ordering does not uniquely sequence rows. Add a stable tie-breaker when functions require a unique row order.